AI
 AWS
 Agile
 Algorithms
 Android
 Apple
 Azure
 Backend
 Bash
 C++
 Cloud
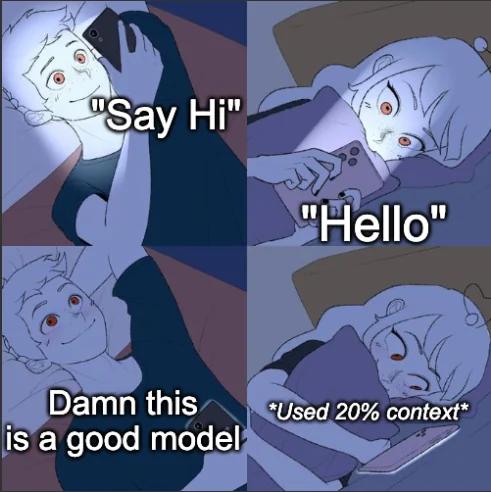
When you're using those fancy new AI coding assistants and you start with a simple "Say Hi" prompt, get back "Hello", and suddenly you're like "damn this is a good model!" — only to realize you just burned through 20% of your context window on pleasantries.
Fable 51 (probably meant to be "Llama 3.1" or some other LLM) users really out here speedrunning their token limits by having polite conversations with their AI instead of, you know, actually coding. Nothing says "efficient prompt engineering" like wasting precious context tokens on greetings when you've got 10,000 lines of spaghetti code to debug. The model's sitting there thinking "I could've held your entire codebase in memory but nah, let's chat first."
POV Average Fable 51 Enjoyer
ai-memes, llm-memes, context-window-memes, prompt-engineering-memes, chatgpt-memes | ProgrammerHumor.io
More Like This