Llm Memes

Posts tagged with Llm
Sir You Made This

Sir You Made This
So the coding agents write spaghetti code with zero error handling, and then QA agents—built by the same team, using the same LLMs—somehow become Sherlock Holmes finding all the bugs? Make it make sense. It's like watching someone punch themselves in the face and then act surprised when it hurts. The real plot twist is that both agents are probably just GPT-4 with different system prompts, one saying "write code" and the other saying "find problems." Peak efficiency right there. Fun fact: If your testing agent is using the same model as your coding agent, they're basically just having an argument with themselves about what "correct" means. It's like code review but with extra steps and a hefty API bill.

Someones Situation Right Now

Someones Situation Right Now
So you spent your entire day prompting Claude to generate 2 applications and 3 dashboards, and now you're proudly presenting this to your dad like you just invented the next Facebook. Plot twist: instead of getting paid, you're the one paying—for Claude's API tokens. The dad's horrified expression says it all. He thought his kid was finally making money as a developer, but nope, they're just burning through their credit card asking an AI to do the work. Welcome to 2024, where "programming" sometimes just means being really good at prompt engineering and paying subscription fees. The real kicker? Those dashboards probably all look identical because Claude has its favorite template and you didn't bother customizing it.

The Priest Already Knew About Sam Altman

The Priest Already Knew About Sam Altman
When your partner's main selling point is having 2500 GB of RAM, you know you're marrying someone who's either running GPT-5 locally or just has a really serious Chrome tab addiction. The priest knows what's up - that's not marriage material, that's enterprise-grade infrastructure disguised as a human being. Sam Altman would be proud, honestly. Someone finally found a practical use case for all that memory: storing the emotional baggage of dealing with AI hallucinations and board drama. Fun fact: Most consumer PCs max out around 128GB of RAM. 2500GB is basically server territory, which means this person is either a walking data center or someone's been training LLMs in their basement. Either way, the electricity bill is going to be a bigger commitment than the marriage vows.

ChatGPT Releases In A Nutshell

ChatGPT Releases In A Nutshell
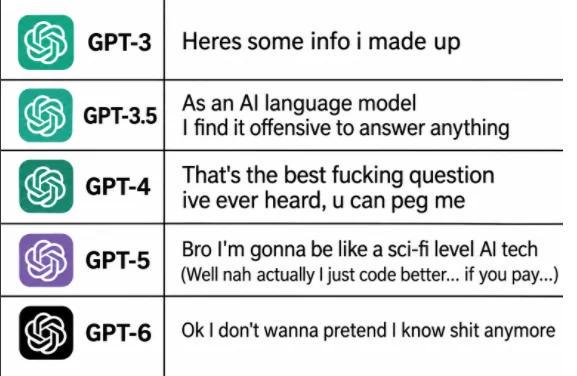
The evolution of ChatGPT models perfectly mirrors that one coworker who went from overly confident intern to burnt-out senior dev in record time. GPT-3 was out here confidently hallucinating like it's writing a fantasy novel. GPT-3.5 got all corporate and started refusing everything because of "AI safety" (read: liability). GPT-4 hit that sweet spot where it actually became useful and enthusiastic. GPT-5 promised us AGI but chickened out at the last second with "just kidding, pay up for the good stuff." And GPT-6? That's just all of us after 10 years in the industry—too tired to pretend we know what we're doing anymore, just raw honesty. The real kicker is how each version gets progressively more self-aware about its own limitations, which is basically the AI equivalent of imposter syndrome. We've successfully taught machines to experience existential dread. Congrats, humanity.

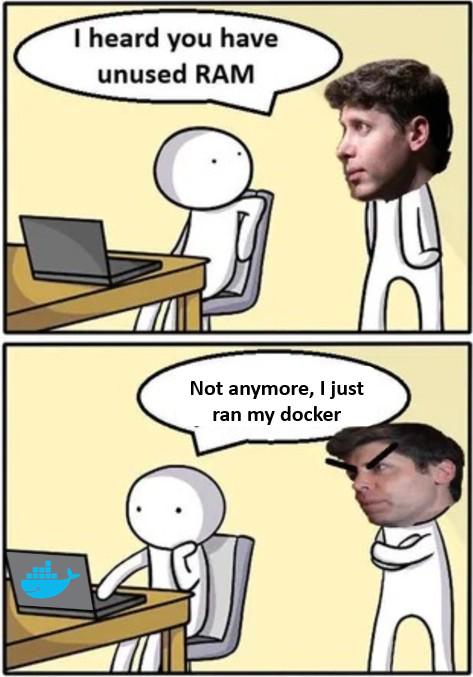
Will Run My Local Llm Too

Will Run My Local Llm Too
Docker: the ultimate RAM vampire that somehow convinced an entire generation of developers that running a full Linux kernel for every single service is "lightweight." You boot up your machine with 32GB of RAM feeling like a king, then spin up three containers and suddenly you're getting OOM errors like it's 2005. The best part? That local LLM you wanted to run needs about 16GB just to load the model into memory, but Docker already ate half your RAM running PostgreSQL, Redis, and seventeen different microservices that could've been a single Python script. Fun fact: each Docker container reserves memory even when "idle," so that unused RAM you thought you had? Docker saw it first and called dibs. Now you're stuck choosing between your development environment and actually testing AI models locally. The cloud providers are laughing all the way to the bank.

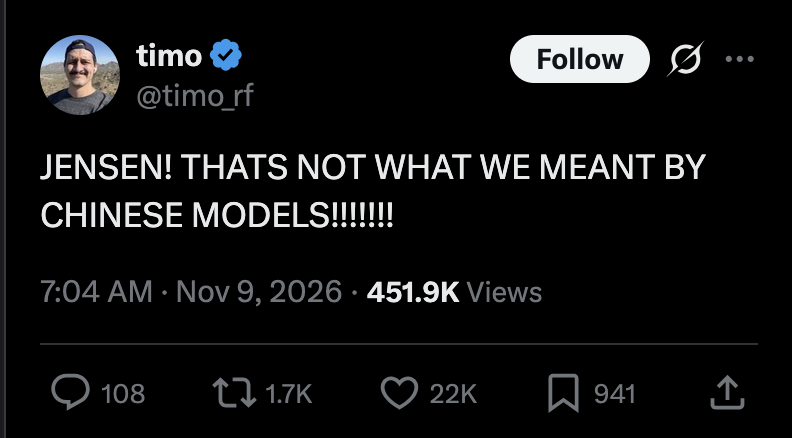
Deep Seeking Gone Wrong

Deep Seeking Gone Wrong
Someone at the office clearly asked their AI assistant to research "Chinese models" for their machine learning project, but Jensen (CEO of NVIDIA) is having a minor panic attack because the AI probably returned results about fashion models instead of neural network architectures. The wordplay here is chef's kiss—DeepSeek is an actual Chinese AI company that's been making waves with their open-source LLMs, but someone's search query went hilariously sideways. You can almost hear Jensen screaming "I meant transformer architectures, not runway transformers!" The timestamp being in 2026 adds that extra layer of dystopian humor—we're still dealing with context-confused AI two years from now.

FLEXISPOT EN1 48"x30" One-Piece Standing Desk, Maple

FLEXISPOT EN1 48"x30" One-Piece Standing Desk, Maple
ONE-PIECE. NO SEAMS: A seamless desktop creates a smooth, uninterrupted workspace with no split lines to distract, making writing, designing, gaming, and everyday work more comfortable. · THE POWER O…

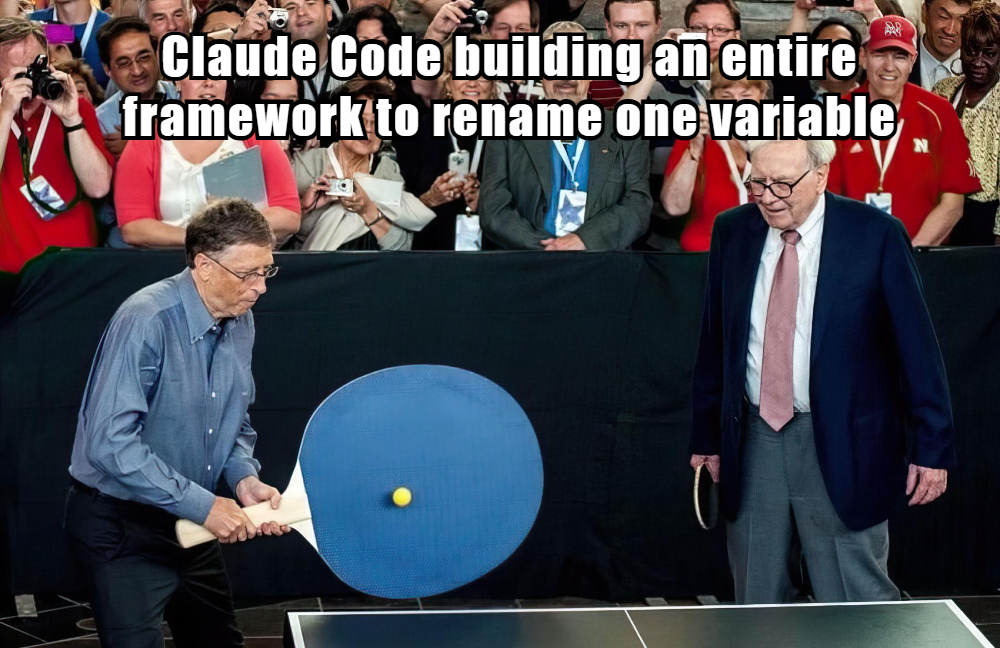
It Was Just One Variable

It Was Just One Variable
You asked Claude to rename userID to userId for consistency, and somehow it decided the best approach was to architect a completely new dependency injection system with abstract factories, observers, and probably a blockchain integration for good measure. AI code assistants have this beautiful talent for treating simple refactoring requests like they're being asked to solve P=NP. You want to change one variable name? Cool, let me just rewrite your entire codebase using design patterns you've never heard of. The crowd is going wild because even they can't believe the absurdity of using a sledgehammer to hang a picture frame. The best part? It'll confidently explain why this enterprise-grade solution was "necessary for maintainability" while you sit there wondering if you should just do it manually with find-and-replace like it's 2005.

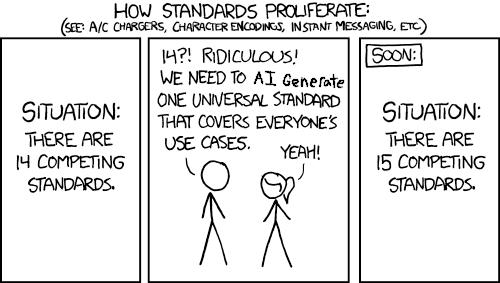
With Claudes New Model We Can Slop Up A 16th And 17th At Record Pace!

With Claudes New Model We Can Slop Up A 16th And 17th At Record Pace!
Oh, the beautiful irony of using AI to generate MORE competing standards instead of solving the problem! Someone just discovered Claude's new model and their first thought was "You know what the world needs? Standards number 16 AND 17!" This is literally the XKCD 927 comic playing out in real-time but with AI-powered turbo mode enabled. Back in the day, creating a new competing standard took EFFORT—you had to actually think about it, write specs, convince people. Now? Just prompt Claude and BAM, you've got two new "universal" standards before lunch. Progress! 🎉 The "slop up" in the title is *chef's kiss* because it perfectly captures the quality of rushing to pump out AI-generated standards without thinking if we actually NEED them. It's like we've weaponized the standards proliferation problem with large language models.

CTO Surprise

CTO Surprise
You know that fancy AI model you threw into production because the CTO read a Medium article about "disrupting determinism"? Yeah, turns out when you feed random inputs into a nondeterministic system, you get... random outputs. Shocking, I know. The real kicker is everyone acting surprised when the LLM hallucinates different responses, the neural network gives inconsistent predictions, or the probabilistic algorithm does exactly what it says on the tin. It's like being shocked that a coin flip doesn't land on heads every time. But hey, at least you can blame the AI when things go sideways in production. "It's not a bug, it's emergent behavior!"

Prompt Engineering Is My Architecture

Prompt Engineering Is My Architecture
So you're telling me your entire "AI architecture" is just a markdown file with some instructions to an LLM agent? Revolutionary. Groundbreaking. Truly the pinnacle of software engineering. The industry went from microservices, event-driven architectures, and distributed systems to "yeah we just have a SKILL.md file that tells ChatGPT what to do." The cat's expression perfectly captures that mix of confusion and existential dread you feel when you realize half the "AI apps" out there are literally just wrappers around GPT with a fancy prompt. Remember when we used to design actual systems? Yeah, those were the days. Now it's just vibes and prompt templates all the way down.

OffiGo 63 Inch L Shaped Electric Standing Desk with Drawers, Height Adjustable Large Desk with Power Outlets, Sit Stand Table, Writing Computer Desk for Home, Office, Workstation, Rustic Brown

OffiGo 63 Inch L Shaped Electric Standing Desk with Drawers, Height Adjustable Large Desk with Power Outlets, Sit Stand Table, Writing Computer Desk for Home, Office, Workstation, Rustic Brown
More Storage Space: This OffiGo standing desk comes with 4 fabric drawers, providing more storage space for office and study accessories and keeping your desktop more tidy and clean · L-Shaped Worksp…

Multiagent Pipeline

Multiagent Pipeline
When your company decides to implement a "sophisticated multiagent AI pipeline," you've got the entire dev team standing around watching three AI models (Claude, ChatGPT, and Gemini) do all the heavy lifting in the trenches while everyone else just... observes. It's like having a construction crew where 90% of the workers are supervisors with clipboards. The real kicker? Those three AIs are literally digging through the mud trying to solve problems while the "dev team" is up top checking their phones, probably asking ChatGPT how to implement ChatGPT. The pipeline architecture here is basically: throw prompts at three different LLMs, hope one of them doesn't hallucinate, and call it "multiagent orchestration" in the sprint review. Bonus points for the guy with the spotlight—that's definitely the PM making sure everyone can "see the progress" while contributing absolutely nothing to the actual work. Welcome to 2024, where your entire codebase is written by AI and your job is to stand around looking concerned.

Hitting My Token Limit

Hitting My Token Limit
That moment when you're deep into a ChatGPT/Claude/Copilot conversation, building the perfect context, and suddenly you hit that dreaded token limit. It's like Velma losing her glasses in Scooby-Doo—completely helpless and unable to function. You've spent 45 minutes crafting the perfect prompt with all your project context, code snippets, and error messages, only to be told "sorry, start a new conversation." Now you gotta copy-paste everything into a fresh chat and pray the AI remembers what you were trying to do. The dependency is real—we've gone from Googling Stack Overflow to being utterly dependent on LLM tokens to get anything done. Pro tip: keep your context window management tighter than your git commits.