Tokens Memes

Posts tagged with Tokens
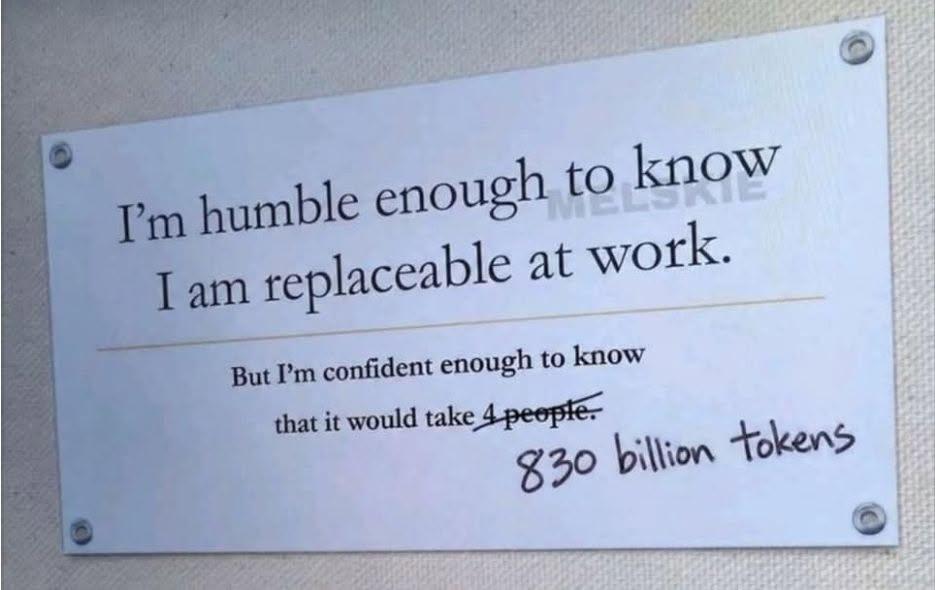
Replacement Is An Option Until The Bill Comes Due

Replacement Is An Option Until The Bill Comes Due
Sure, you might be replaceable in theory, but good luck finding someone willing to wade through your undocumented spaghetti code, decipher those cryptic variable names like temp2_final_ACTUAL , and understand why the entire authentication system depends on a regex pattern you copy-pasted from Stack Overflow in 2019. The real kicker? Those "830 billion tokens" represent the astronomical cost of feeding your entire codebase into GPT-4 or Claude just to generate enough context for a replacement to understand what's happening. At current API pricing, that's not just expensive—that's "we could've given you a raise instead" expensive. The joke cuts deep because it highlights the hidden cost of tribal knowledge. You're not irreplaceable because you're a genius—you're irreplaceable because you're the only one who knows that the production server crashes if you deploy on Tuesdays, and why there's a sleep(500) in the payment processing logic that nobody dares remove.

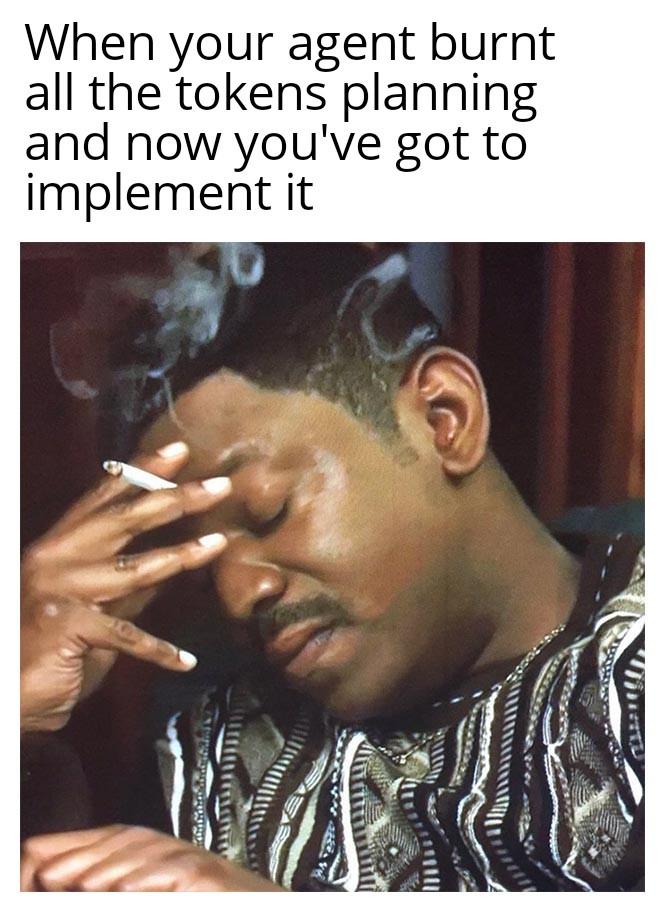
Perfectly Planned Exercise

Perfectly Planned Exercise
You know that feeling when your AI agent just went absolutely ham during the planning phase, burning through your entire token budget like it's monopoly money, and now you're sitting there with a 47-page architectural document but zero actual code? Yeah, that's the dream right there. The agent was supposed to help you BUILD the thing, not write a doctoral thesis on how it COULD be built. But nope, it spent all its tokens debating design patterns, considering edge cases that'll never happen, and probably throwing in some philosophical musings about clean code. Now you're left holding the bag, staring at this beautiful plan that you have to actually implement yourself. Thanks, buddy. Really helpful. It's like hiring a consultant who spends your entire budget on PowerPoint slides and then ghosts you when it's time to do the actual work. Classic.

Guzzling Tokens Like Popcorn

Guzzling Tokens Like Popcorn
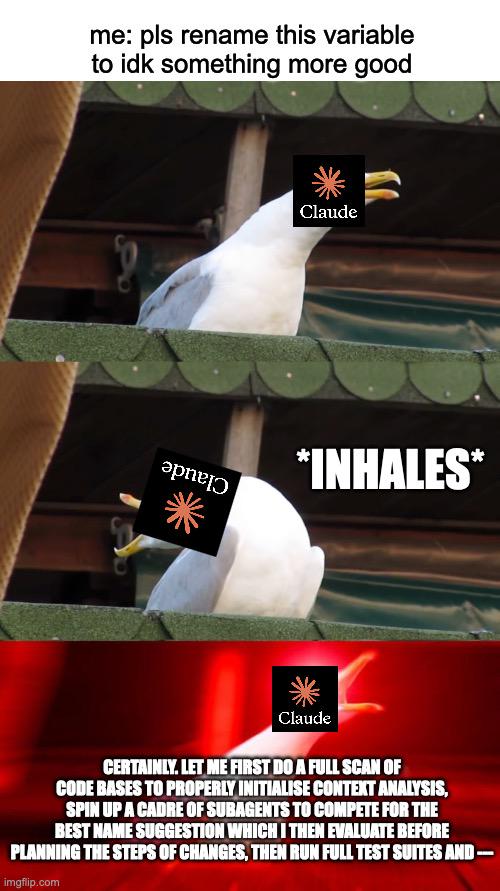
You ask Claude to rename a variable. Simple request, right? Just a quick refactor. But Claude? Oh no, Claude's got PLANS. It's about to burn through your entire token budget doing a full codebase analysis, initializing context on every file you've ever written, spinning up subagents like it's spawning Docker containers, and planning a 47-step refactoring strategy complete with test suites. Meanwhile your wallet is screaming because you just wanted to change "x" to "userCount" and now you're paying for Claude to architect your entire application from scratch. The AI equivalent of asking someone to pass the salt and they start explaining the entire history of sodium chloride mining.

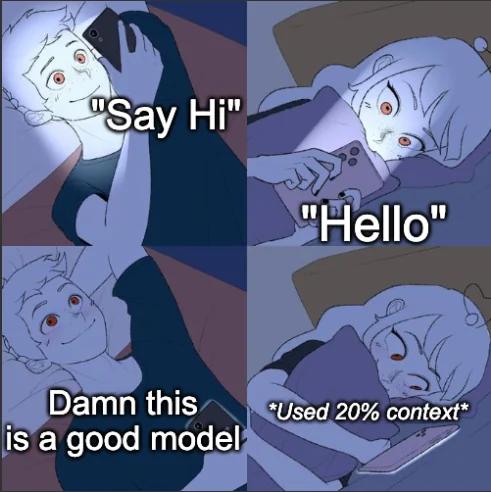
POV Average Fable 51 Enjoyer

POV Average Fable 51 Enjoyer
When you're using those fancy new AI coding assistants and you start with a simple "Say Hi" prompt, get back "Hello", and suddenly you're like "damn this is a good model!" — only to realize you just burned through 20% of your context window on pleasantries. Fable 51 (probably meant to be "Llama 3.1" or some other LLM) users really out here speedrunning their token limits by having polite conversations with their AI instead of, you know, actually coding. Nothing says "efficient prompt engineering" like wasting precious context tokens on greetings when you've got 10,000 lines of spaghetti code to debug. The model's sitting there thinking "I could've held your entire codebase in memory but nah, let's chat first."

I Just Want To Develop

I Just Want To Develop
When you just want to write some code but your computer is being held hostage by Meta, Apple, NVIDIA, Google, and OpenAI demanding their daily tribute of authentication tokens, API keys, and OAuth ceremonies. It's like having five needy partners who all need constant validation before you can do literally anything. The developer sits there, dead inside, agreeing to whatever token-burning ritual is required today. Need to refresh my Google Cloud credentials? Sure. Apple wants me to re-authenticate for the 47th time this week? Fine. Meta's SDK needs another access token? Whatever keeps the peace. Modern development is less "Hello World" and more "Hello, please verify your identity across 12 different platforms first." Remember when you could just... code? Yeah, neither do I.

Lenovo ThinkPad E16 Gen 3 Laptop 16" FHD+ Touch, Ryzen 7 250, 16GB/512GB | Premium Business PC, 38 TOPS 8-Core Processor (> Ryzen 7 7735U), Copilot, FP, Backlit KB, WiFi 6, IR Webcam, Win11Pro

Lenovo ThinkPad E16 Gen 3 Laptop 16" FHD+ Touch, Ryzen 7 250, 16GB/512GB | Premium Business PC, 38 TOPS 8-Core Processor (> Ryzen 7 7735U), Copilot, FP, Backlit KB, WiFi 6, IR Webcam, Win11Pro
ENTERPRISE-READY PERFORMANCE - Built for Professionals, Learners, and everyday Business use, the ThinkPad E16 delivers dependable performance and durable design for users who want more without stretc…

Great Offer

Great Offer
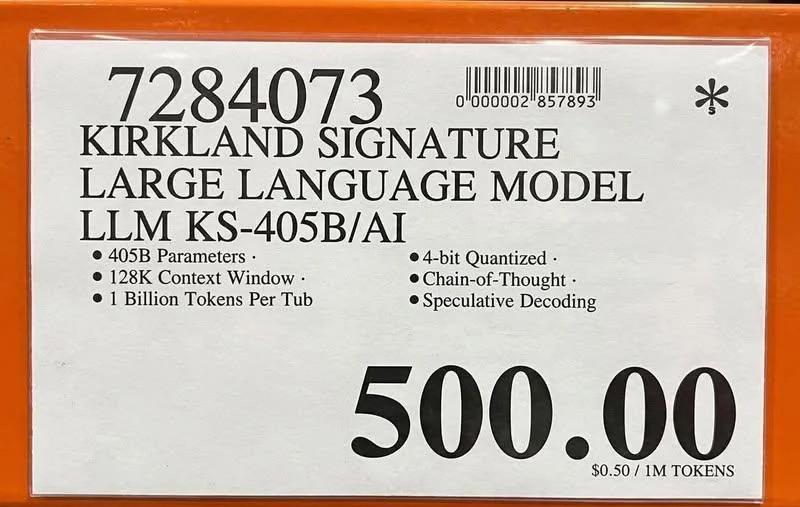
Behold, the Costco of AI has arrived! You can now buy your very own "Kirkland Signature" LLM in bulk—because why pay premium prices for GPT-4 when you can get the store-brand version with 405 BILLION parameters for just $500? That's literally half a cent per million tokens, darling. The specs are absolutely SENDING me: "1 Billion Tokens Per Tub" like it's a container of mixed nuts you'll forget about in your pantry. And don't sleep on that "4-bit Quantized" feature—they've compressed this bad boy so hard it probably tastes like AI concentrate. Just add water (or GPU power) and boom, instant intelligence! Chain-of-Thought and Speculative Decoding included because even budget AI needs to pretend it's thinking deeply about your prompts. Nothing screams "cutting-edge technology" quite like packaging it with a barcode next to your toilet paper and rotisserie chicken.

Put The Tokens In The Token Fire

Put The Tokens In The Token Fire
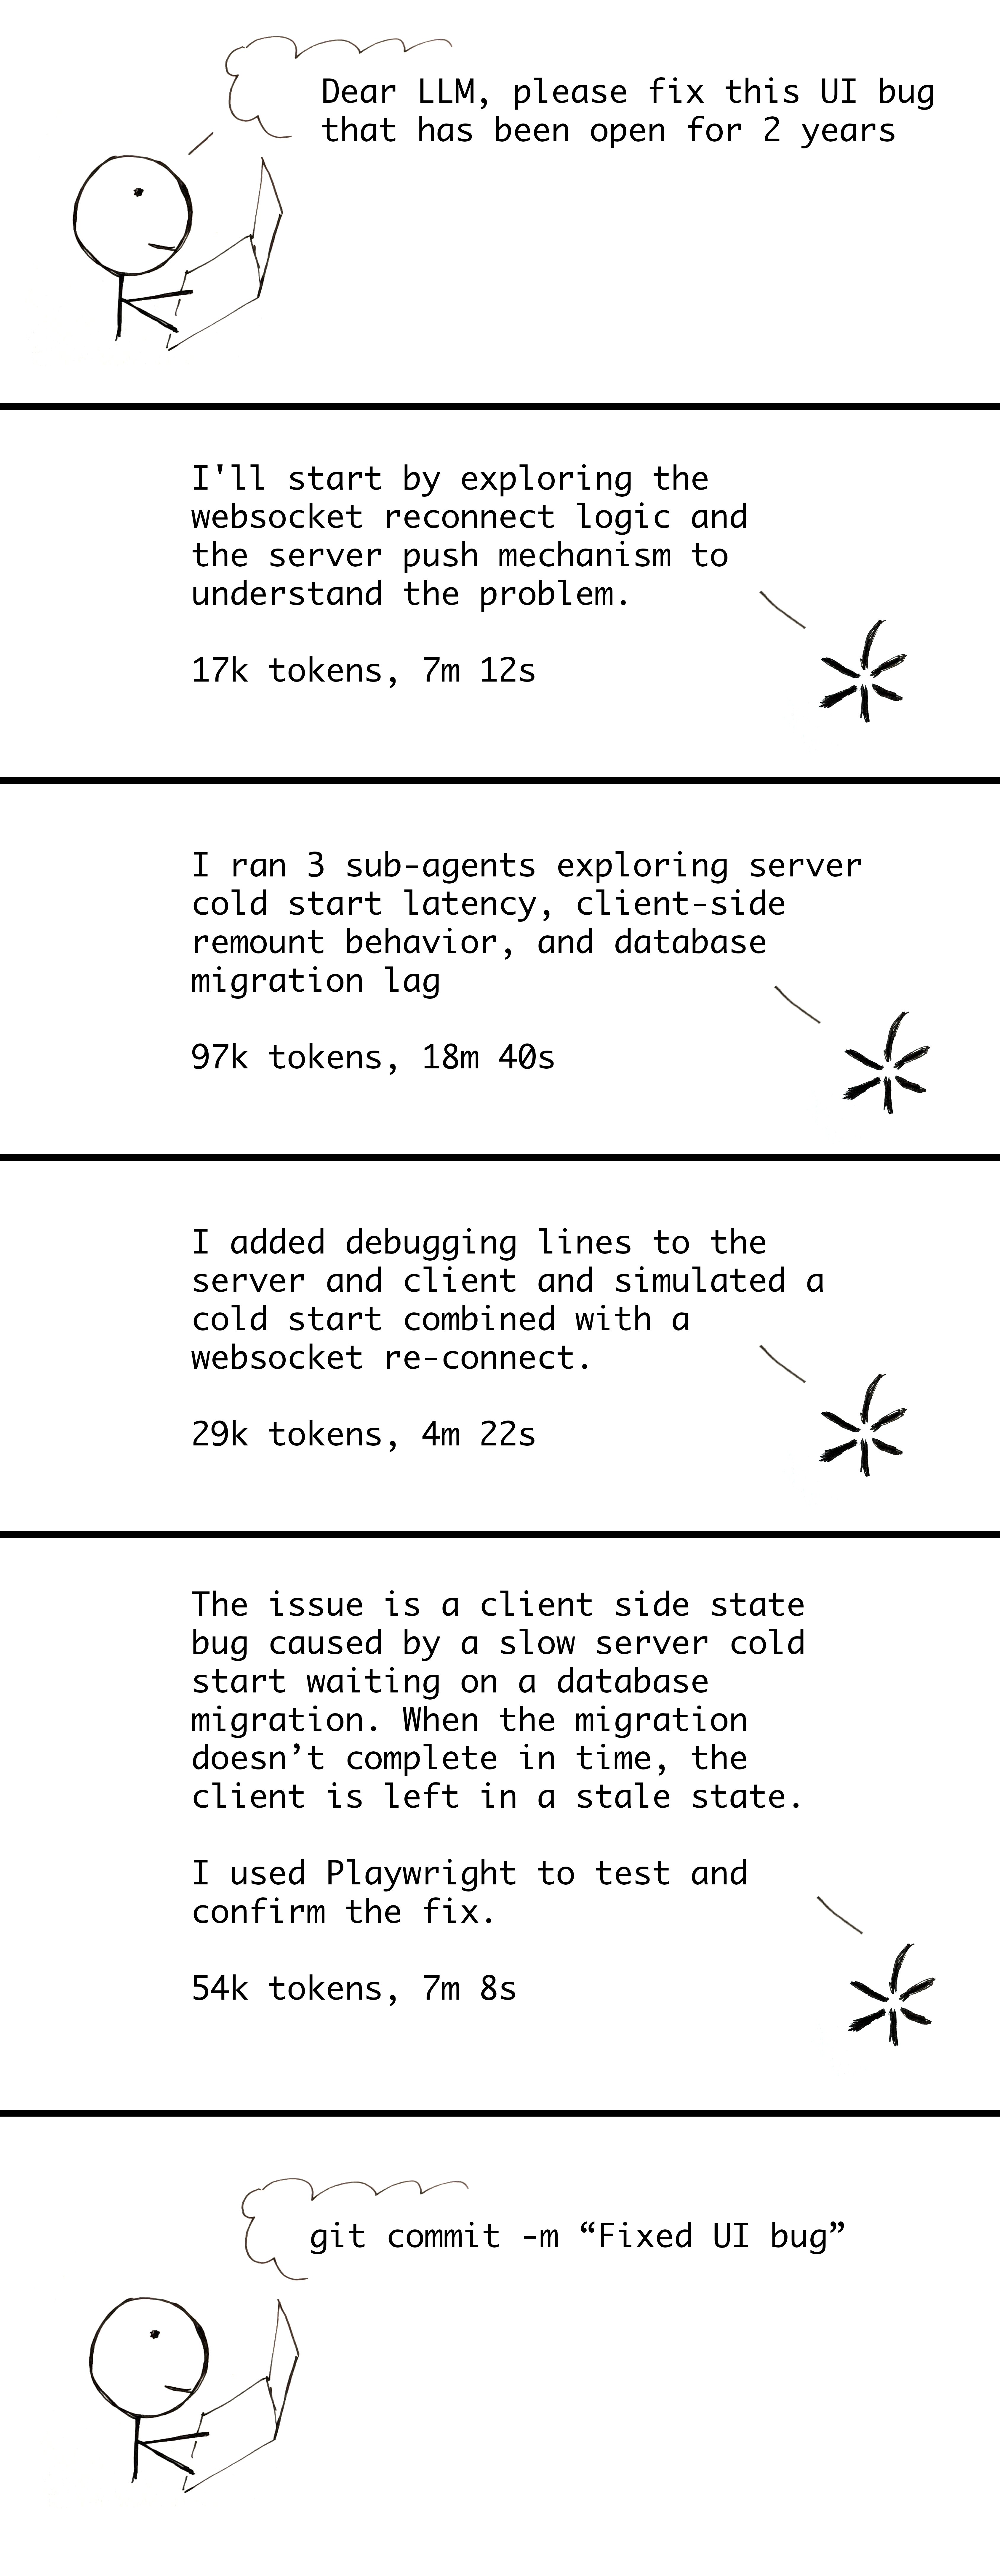
Someone asked an LLM to fix a simple UI bug and watched in horror as it burned through 177,000 tokens ($$$) to essentially do what a human could've done in 5 minutes. The AI went full detective mode, investigating websocket reconnect logic, spawning THREE sub-agents to explore server architecture, adding debugging lines, and writing a whole Playwright test suite. All to fix a timing issue that probably needed a setTimeout() and a coffee break. The best part? It actually solved the problem correctly. But at what cost? Your AWS bill is crying. Your product manager is asking why the API costs tripled. And somewhere, a junior dev who could've fixed this for the price of their salary is updating their resume because they've been replaced by a $200 bug fix. Fun fact: 177k tokens is roughly the length of "The Great Gatsby." So basically, the LLM wrote a novel about your websocket connection instead of just... fixing it. Efficiency at its finest.

When Your OAuth Keeps Breaking

When Your OAuth Keeps Breaking
Nothing quite captures the soul-crushing loop of OAuth debugging like having to re-authenticate for the 47th time in an hour. Your session expired? Token refresh failed? Redirect URI typo? Who knows—but you're definitely logging in again. The best part? Each login attempt takes you through the entire flow: click the button, wait for the redirect, accept permissions, get bounced back, watch it fail, and repeat. It's like Groundhog Day but with more JSON and less Bill Murray. Pro tip: After your 10th login attempt, you start questioning your entire career path. After the 20th, you're googling "how to become a carpenter."

Use Caveman Grunt To Save Token

Use Caveman Grunt To Save Token
When you're paying $0.002 per 1K tokens and suddenly realize verbose prompts are just burning money. Why write "Please provide a comprehensive analysis" when "analyze" does the job? The LLM API bills you by the token, so every "please," "kindly," and "I would appreciate if you could" is literally costing you cash. Developers speedrunning the evolution of language backwards—from Shakespeare to caveman—just to shave off a few cents. Your prompts went from polite corporate emails to telegram-style efficiency real fast. "Why waste time say lot word when few word do trick" isn't just a meme anymore, it's a cost optimization strategy.

Why Use Many Token When Few Token Do Trick

Why Use Many Token When Few Token Do Trick
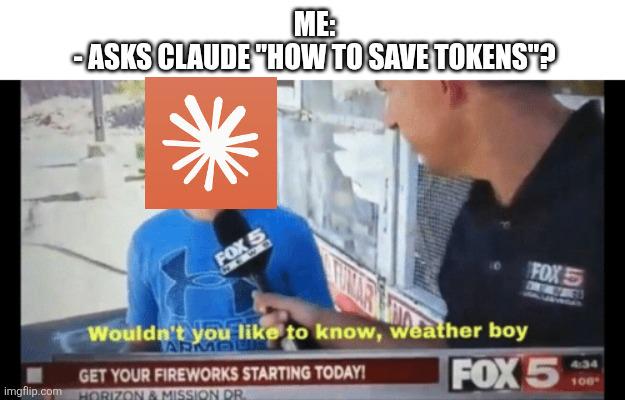
The beautiful irony of asking an AI chatbot how to save tokens, only for it to respond with a verbose explanation that probably costs more tokens than you'd save in a month. It's like asking your car's GPS for the shortest route and it takes you through three states to explain what "left" means. Claude's response is basically "Wouldn't you like to know, weather boy" – the AI equivalent of refusing to answer the question while simultaneously burning through your token budget just to tell you it won't answer. Peak efficiency right there. Fun fact: The average Claude response explaining token optimization probably uses more tokens than just... not optimizing at all. But hey, at least you learned something while watching your API credits evaporate faster than your motivation on a Monday morning.

Token Employee Of The Month

Token Employee Of The Month
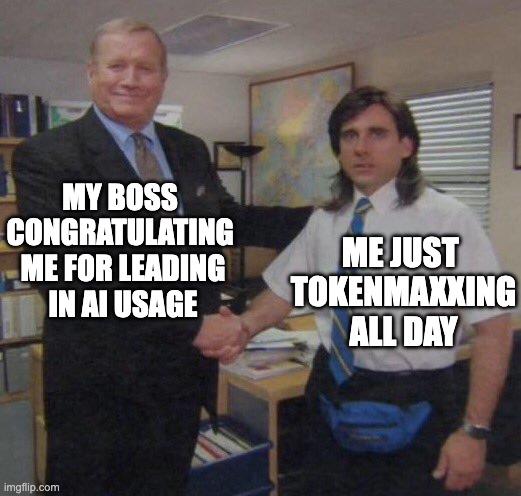
Boss thinks you're revolutionizing the company with cutting-edge AI implementation. Reality? You've just been burning through API credits like they're free samples at Costco, feeding every possible prompt into ChatGPT to see what sticks. The beautiful irony here is that "token" works on two levels - you're the token AI expert getting recognition, while literally just maxing out token limits on OpenAI's billing dashboard. Your boss sees "AI integration" on the roadmap. You see a $2,000 API bill and a collection of half-baked responses you copy-pasted into Slack. Welcome to 2024, where prompt engineering is apparently a leadership skill and everyone's an AI pioneer until the finance team asks questions.

Cable Matters 20Gbps USB C KVM Switch for 2 Computers, 140W PD Charging

Cable Matters 20Gbps USB C KVM Switch for 2 Computers, 140W PD Charging
Compatibility Warning – Cable & Setup Requirements: Use only the included USB4 20Gbps cables. Do not substitute with Thunderbolt 3/4/5 cables. Avoid USB-C docks with built-in (non-detachable) host ca…

Billable Tokens

Billable Tokens
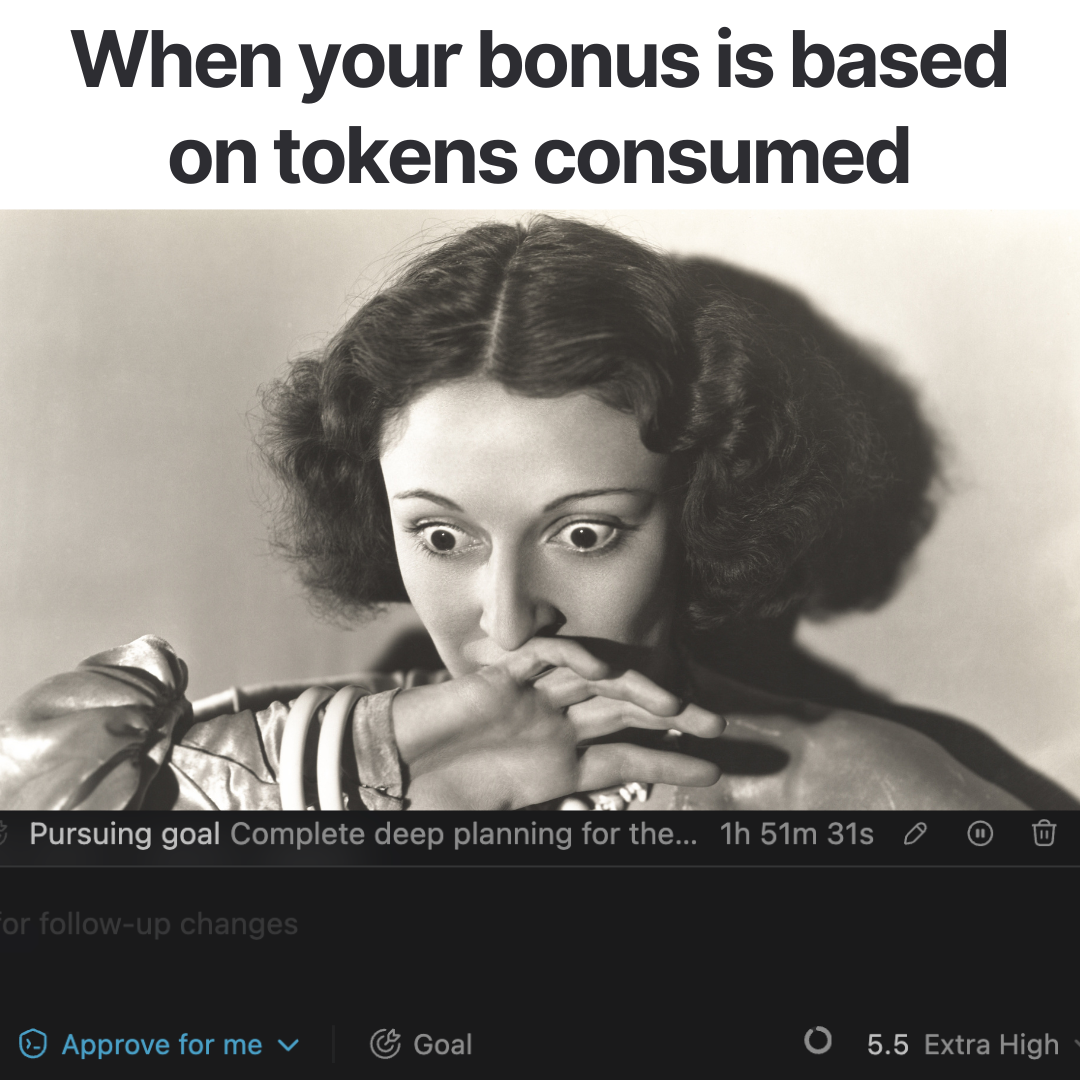
Nothing quite says "corporate innovation" like tying your salary to how much you bother ChatGPT. The nervous energy in that vintage photo? That's every developer watching their AI assistant "think" for 2 hours straight about a simple function while their bonus evaporates token by token. "Complete deep planning for the..." - yeah buddy, take your time. Not like my mortgage depends on you finishing that sentence or anything. The best part? You know someone's definitely gaming the system by asking the AI to write War and Peace in the comments of their code reviews. Pro tip: If your company does this, start writing all your prompts in the most verbose way possible. "Hey AI, please elaborate extensively and comprehensively..." becomes your new best friend.