machine learning Memes

Multiagent Pipeline

Multiagent Pipeline
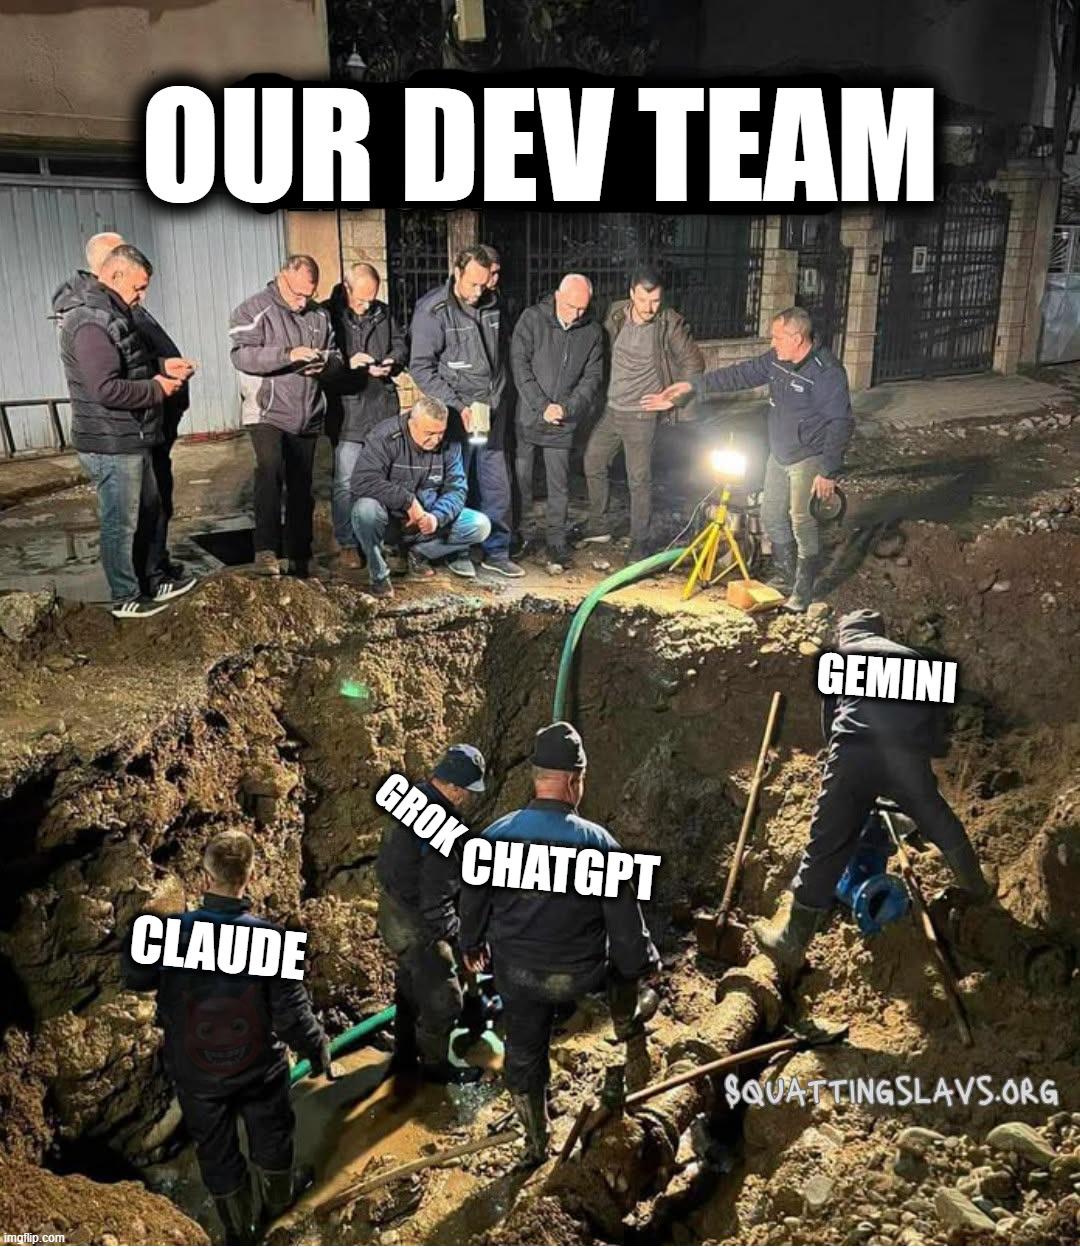
When your company decides to implement a "sophisticated multiagent AI pipeline," you've got the entire dev team standing around watching three AI models (Claude, ChatGPT, and Gemini) do all the heavy lifting in the trenches while everyone else just... observes. It's like having a construction crew where 90% of the workers are supervisors with clipboards. The real kicker? Those three AIs are literally digging through the mud trying to solve problems while the "dev team" is up top checking their phones, probably asking ChatGPT how to implement ChatGPT. The pipeline architecture here is basically: throw prompts at three different LLMs, hope one of them doesn't hallucinate, and call it "multiagent orchestration" in the sprint review. Bonus points for the guy with the spotlight—that's definitely the PM making sure everyone can "see the progress" while contributing absolutely nothing to the actual work. Welcome to 2024, where your entire codebase is written by AI and your job is to stand around looking concerned.

Hitting My Token Limit

Hitting My Token Limit
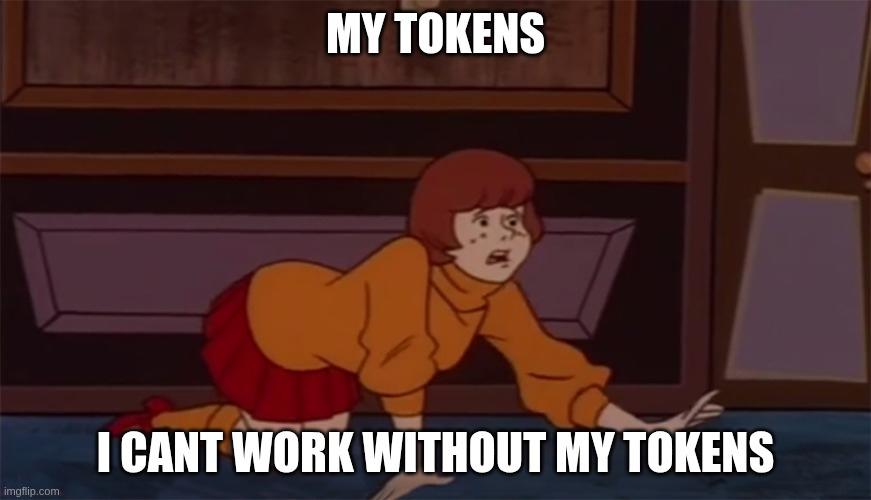
That moment when you're deep into a ChatGPT/Claude/Copilot conversation, building the perfect context, and suddenly you hit that dreaded token limit. It's like Velma losing her glasses in Scooby-Doo—completely helpless and unable to function. You've spent 45 minutes crafting the perfect prompt with all your project context, code snippets, and error messages, only to be told "sorry, start a new conversation." Now you gotta copy-paste everything into a fresh chat and pray the AI remembers what you were trying to do. The dependency is real—we've gone from Googling Stack Overflow to being utterly dependent on LLM tokens to get anything done. Pro tip: keep your context window management tighter than your git commits.

Some Spare Ram For Sam Altman To Cry About

Some Spare Ram For Sam Altman To Cry About
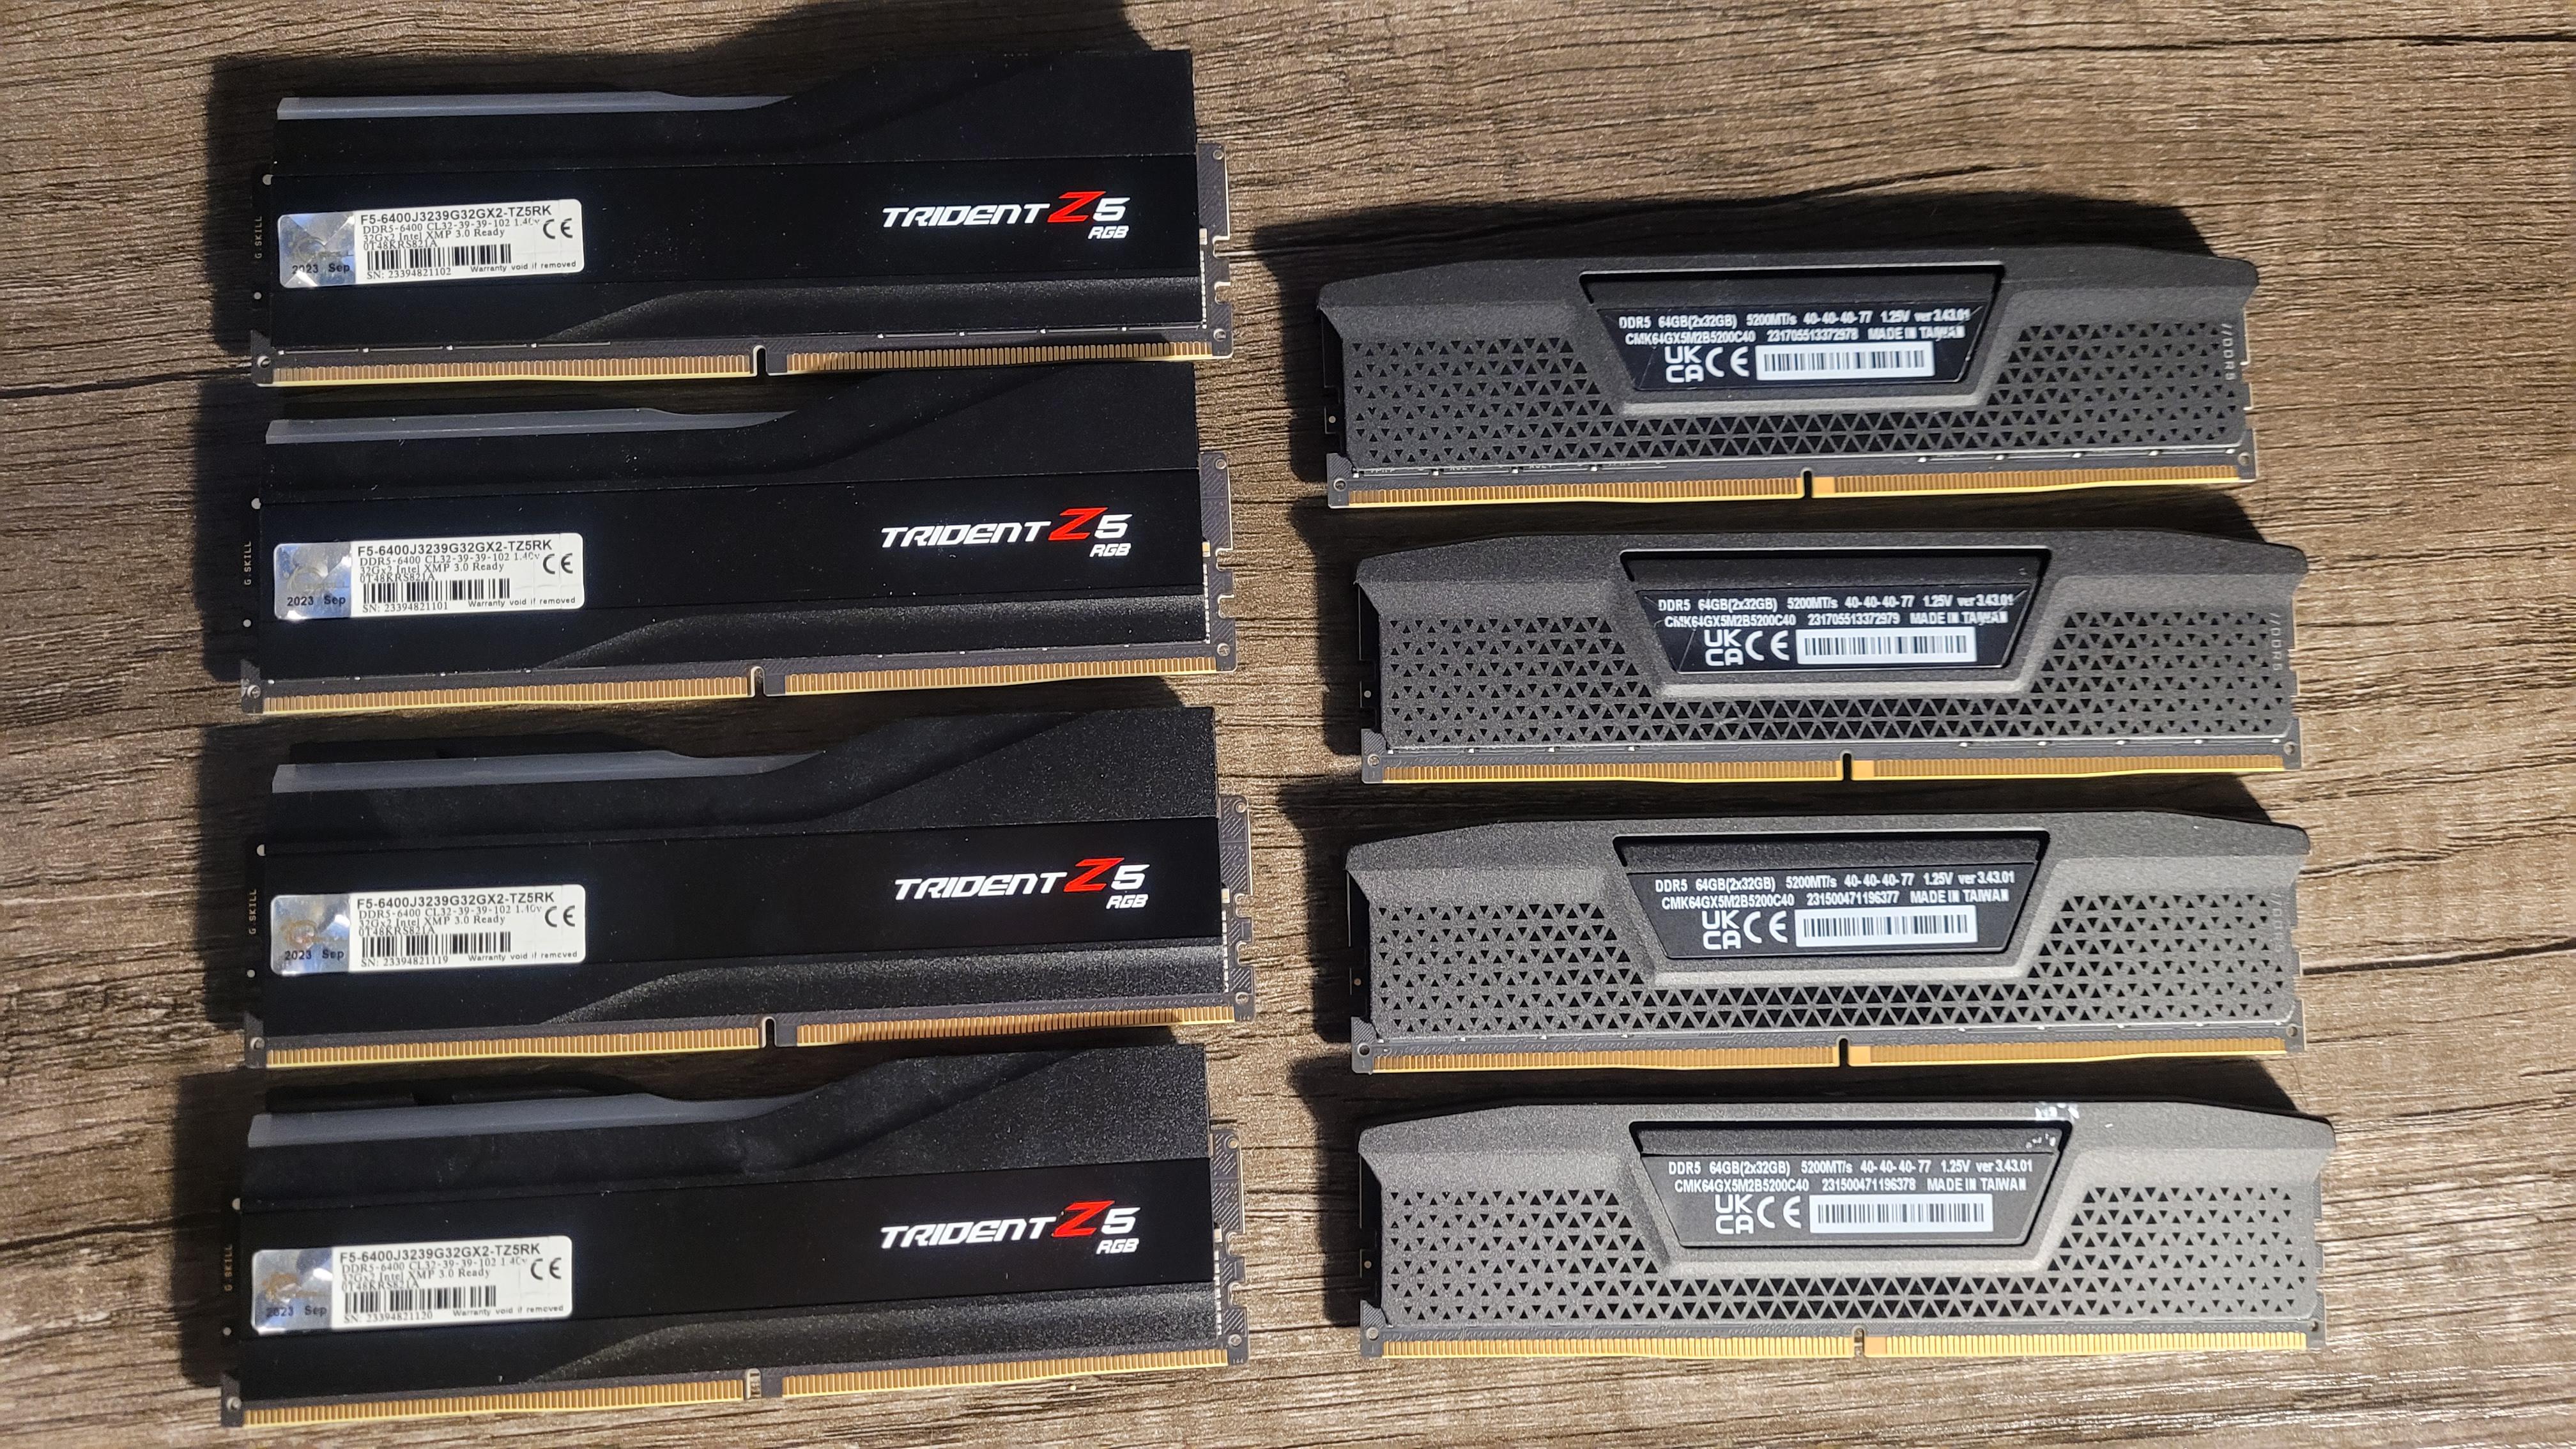
Oh look, someone's flexing their entire 8 sticks of DDR3 RAM while Sam Altman is out here complaining that there's not enough compute in the universe to train GPT-5. The irony is chef's kiss—OpenAI is burning through billions of dollars worth of server farms with HBM memory that costs more than a small country's GDP, and here's our hero offering what's essentially pocket change in the AI world. It's like offering a glass of water to someone trying to fill an ocean. Sam needs exabytes of VRAM across thousands of H100 GPUs, but sure, those 64GB of consumer RAM will definitely solve the compute shortage. Thanks for your generous contribution to the AI revolution, I'm sure OpenAI will send you a thank-you card any day now.

How To Catch A Sam Altman

How To Catch A Sam Altman
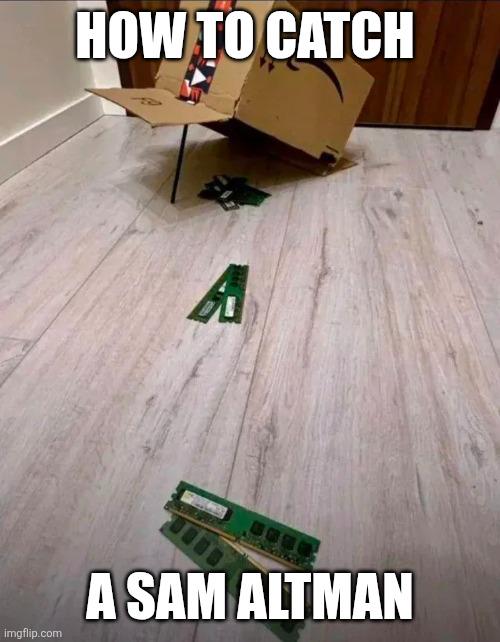
Just leave a trail of GPUs leading to a cardboard box propped up with a stick. Works every time. The OpenAI CEO's natural instinct to hoard compute resources for the next AGI breakthrough makes him particularly vulnerable to this classic trap. You can practically hear him muttering "just one more H100 cluster" as he crawls under the box.

My LLM Prompted Me To Create This

My LLM Prompted Me To Create This
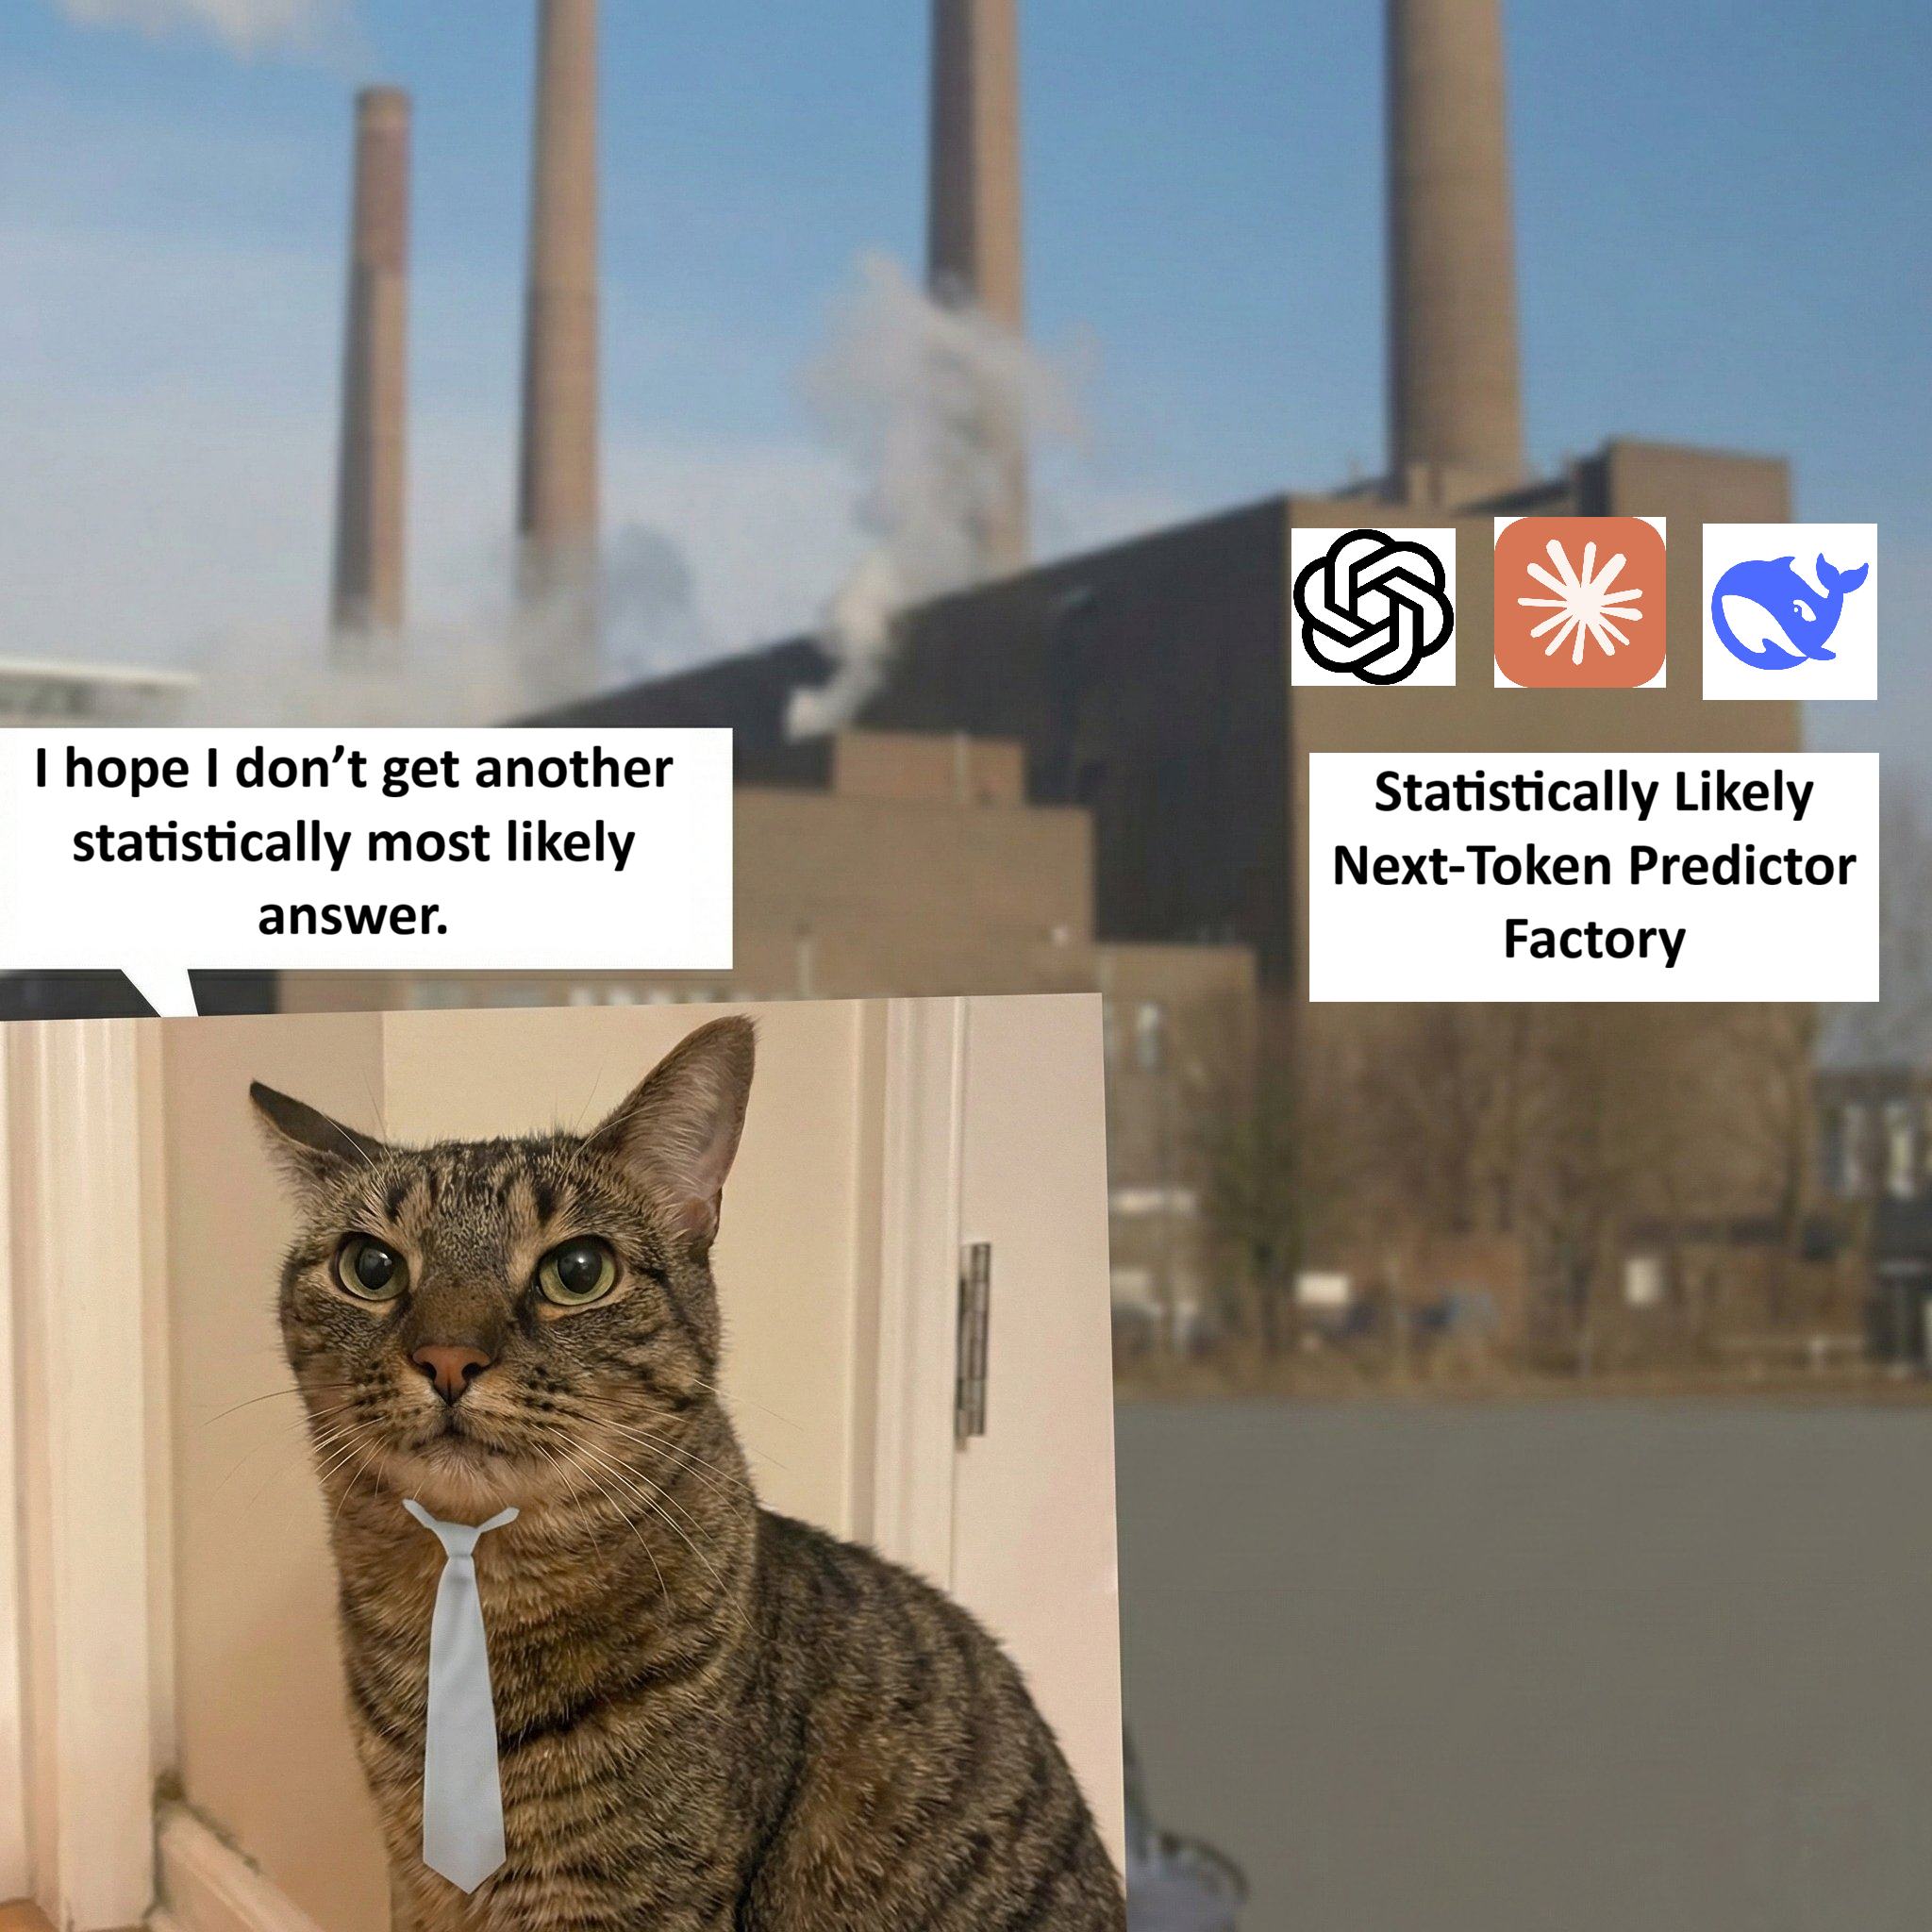
The business cat is nervously eyeing those pollution-spewing smokestacks labeled "Statistically Likely Next-Token Predictor Factory" because he knows exactly what's coming. Every time you ask an LLM a question, it's not actually reasoning or understanding—it's just playing an incredibly sophisticated game of "what word comes next?" based on probability distributions. So when you ask ChatGPT or Claude something nuanced, there's always that lurking dread that instead of a thoughtful answer, you'll get the statistically most probable response that sounds confident but is completely hallucinated. It's like asking a parrot that's read the entire internet—sure, it sounds smart, but it's fundamentally just predicting tokens based on training data patterns. The factory imagery is chef's kiss because it captures how these models are literally industrial-scale probability machines churning out tokens. No consciousness, no real understanding—just pure statistical inference at massive scale. And yet here we are, trusting them to write our code, debug our apps, and explain complex concepts. What could possibly go wrong? 🎲

This Just Hit Me

This Just Hit Me
The bitter truth that if Nvidia ever decides to stop manufacturing consumer GPUs, you'll have no choice but to keep updating firmware on your existing card forever. It's like realizing your entire gaming/ML rig's future depends on a single company's quarterly earnings call. The "hard to swallow pill" format really nails the existential dread of vendor lock-in and hardware dependency. Sure, AMD and Intel exist, but let's be real about market dominance here.

Do You Have Any Idea

Do You Have Any Idea
The question that keeps Sam Altman up at night. ChatGPT was built using Claude's architecture as a foundation? That's like discovering your competitor's entire business model was bootstrapped from your own product. The irony is delicious. For context: Claude is Anthropic's AI assistant, positioned as ChatGPT's main competitor. The idea that OpenAI somehow reverse-engineered or used Claude to build ChatGPT is technically backwards (ChatGPT came first), which makes this even funnier. It's the AI equivalent of accusing someone of plagiarizing your homework when they turned theirs in before you even enrolled in the class. The existential confusion on display here is what happens when the AI wars get so meta that even the timeline stops making sense.

NordVPN

NordVPN
Encrypt your traffic on public Wi-Fi, stream from anywhere, and cover up to ten devices with one plan. 30-day money-back guarantee.

Nvidia Stopping Production Of 5080/5090 Cards To Fulfill As Many AI Start-Up Orders As Possible Before They're All Mysteriously Cancelled Next Week

Nvidia Stopping Production Of 5080/5090 Cards To Fulfill As Many AI Start-Up Orders As Possible Before They're All Mysteriously Cancelled Next Week
Nvidia's playing 4D chess here. They know exactly what's about to happen: AI startups that raised $50M on a pitch deck with "ChatGPT but for X" are panic-buying H100s and enterprise GPUs like they're going out of style. Meanwhile, gamers just want to play Cyberpunk at 4K, but nope—production halted on consumer cards. The brutal reality? Once the VC funding dries up and these startups realize their "revolutionary AI" is just a fine-tuned LLaMA model with a fancy UI, those orders are getting cancelled faster than you can say "pivot to blockchain." But Nvidia's already got their money, hence the legendary "NO REFUNDS OR EXCHANGES - ALL SALES FINAL" policy. Jensen's out here with the leather jacket energy, basically telling gamers "sorry, your RTX 5090 dreams will have to wait while we sell $40,000 GPUs to companies that'll be defunct by Q3." The man knows the AI bubble playbook by heart: take the money, ship the silicon, watch the inevitable implosion from a safe distance. Absolute savage business move.

Something Something Statistical Model

Something Something Statistical Model
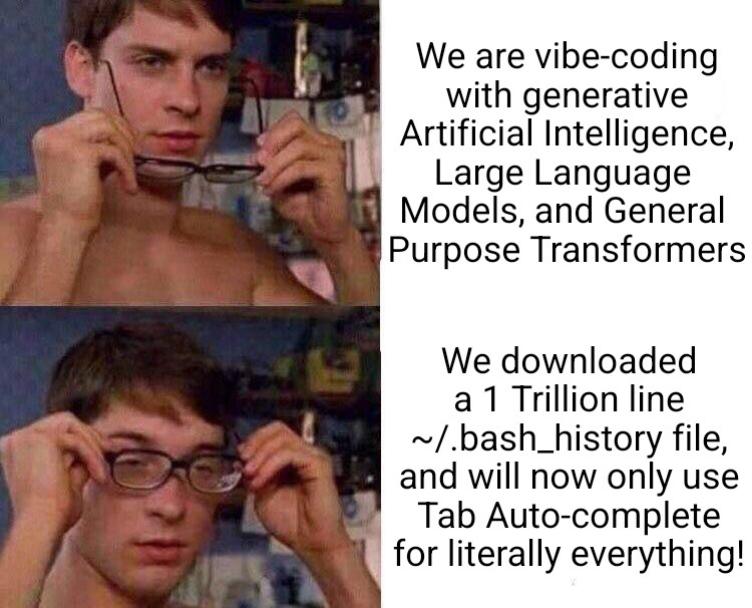
The entire AI industry just got called out. Companies out here dropping press releases about "leveraging cutting-edge generative AI and transformer architectures" when really they just scraped your bash history and piped it into autocomplete. That 1 trillion line bash_history file is doing more heavy lifting than all those GPUs combined. Turns out the real machine learning was the commands we copied along the way. Who needs backpropagation when you've got Ctrl+R ? Your entire "AI-powered development workflow" is basically just fancy grep with better marketing. And honestly? Still more reliable than half the LLMs out there hallucinating package names.

At Least We Know

At Least We Know
That guy at the party who just discovered Claude and won't shut up about it. Meanwhile everyone else is either already using it or has moved on to the next shiny AI toy. Classic early adopter energy—showing up late to the hype train but acting like you just invented fire. The party hat really sells the "I'm the main character" vibe.

Sam Altman After He Finds Ram In Your Personal Computer

Sam Altman After He Finds Ram In Your Personal Computer
Set in the dystopian future of 2026, Sam Altman has apparently evolved from OpenAI CEO to some kind of hardware warlord who's hunting down every last kilobyte of RAM like it's a precious resource in a post-apocalyptic wasteland. The joke here is that AI models are becoming so absurdly resource-hungry that even the 512 KB sitting in your ancient Casio calculator isn't safe from being requisitioned for training GPT-7 or whatever monstrosity needs 10 petabytes just to boot up. The Mad Max-style chase scene perfectly captures the aggressive resource grab that AI companies are doing right now—if it can compute, they want it. Your smart fridge? Gone. Your Tamagotchi? Confiscated. That TI-84 from high school? Already powering a neural network somewhere.

Bro I Only Have 8 GB

Bro I Only Have 8 GB
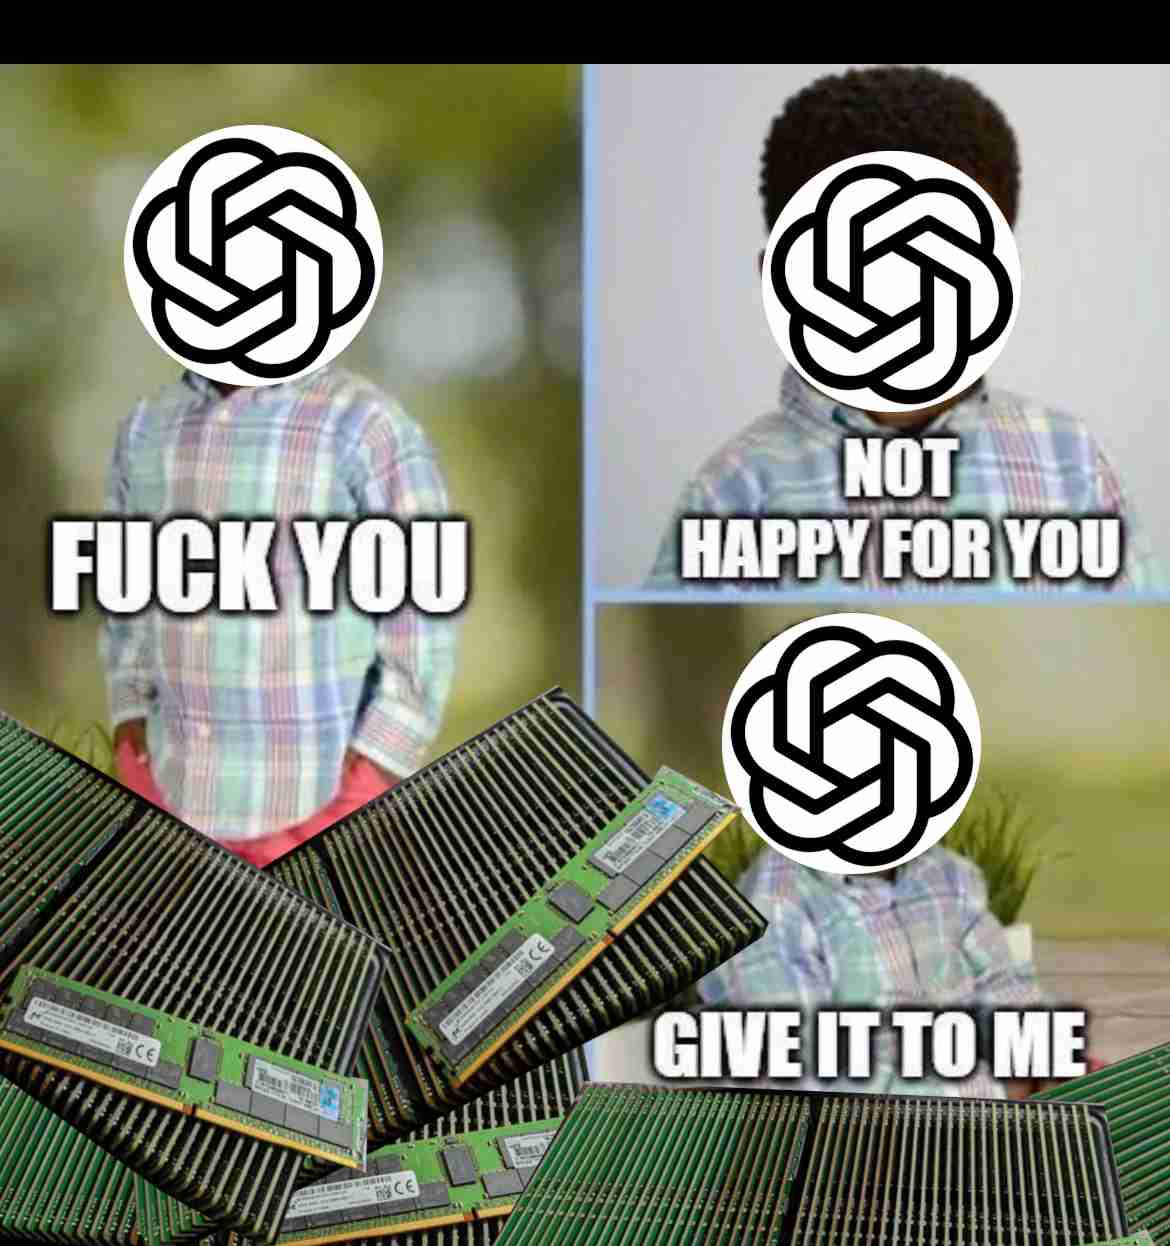
ChatGPT casually suggesting you run its latest AI model locally on your potato laptop is comedy gold. You're sitting there with your 8GB of RAM, barely keeping Chrome and VS Code alive, and this absolute menace wants you to download a 70B parameter model that requires more VRAM than your entire system has memory. The three stages of grief are beautifully captured here: denial ("FUCK YOU"), bargaining ("NOT HAPPY FOR YOU"), and pure desperation ("GIVE IT TO ME"). Because deep down, you know you're about to turn your machine into a space heater just to run inference at 0.5 tokens per second. Fun fact: Those RAM sticks in the image look like server-grade ECC memory, probably 32GB or 64GB each. Meanwhile, you're out here with single-channel DDR4 wondering why your local LLM keeps OOM-ing. The gap between AI requirements and developer hardware has never been more painful.