Devops Memes

DevOps: where developers and operations united to create a new job title that somehow does both jobs with half the resources. These memes are for anyone who's ever created a CI/CD pipeline more complex than the application it deploys, explained to management why automation takes time to implement, or received a 3 AM alert because a service is using 0.1% more memory than usual. From infrastructure as code to "it works on my machine" certificates, this collection celebrates the special chaos of making development and operations play nicely together.
Based On A True Story

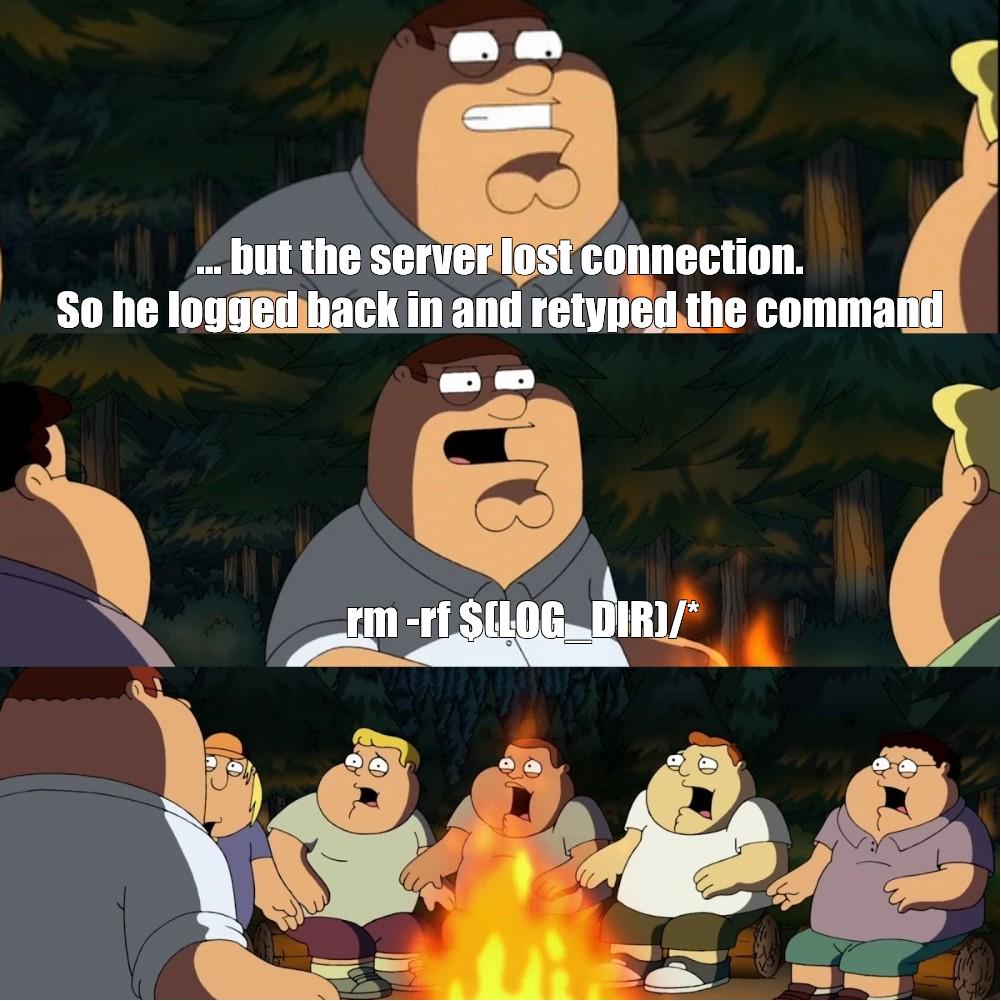
Based On A True Story
Oh, the HORROR of losing your SSH connection mid-command and having to retype that beautiful, carefully crafted command from memory! But wait—our hero here decides to log back in and casually drop an rm -rf $(LOG_DIR)/* like it's no big deal. Except... plot twist: the variable didn't expand because the shell session was different, or the environment wasn't set, or Mercury was in retrograde, or WHATEVER. So instead of deleting logs, they just nuked the ENTIRE FILESYSTEM starting from root. Nothing says "production incident" quite like recursively force-deleting everything because you trusted a variable to do its job. The crowd's horrified faces? That's every sysadmin within a 50-mile radius feeling the disturbance in the force. Pro tip: always echo your variables before you yeet them into an rm command, folks!

I Don't Even Trust My Own Code

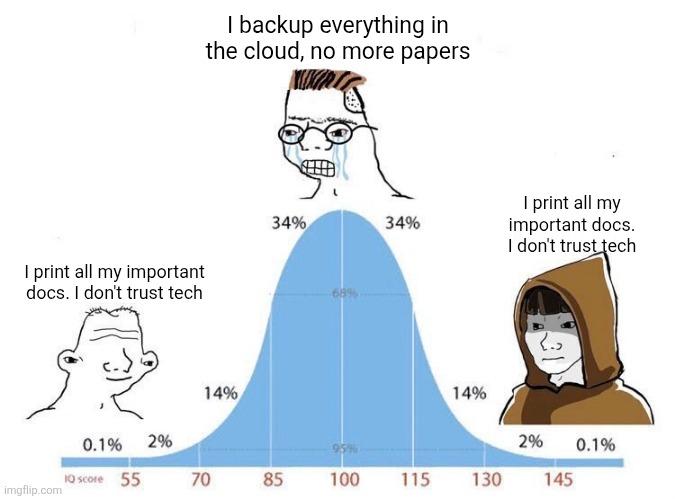
I Don't Even Trust My Own Code
The bell curve strikes again, placing the enlightened cloud enthusiast at the center while the paranoid paper-hoarders occupy both extremes. The genius in the middle has achieved peak modern developer zen: "I backup everything in the cloud, no more papers." Meanwhile, the low-IQ and high-IQ crowds have independently arrived at the same conclusion through completely different paths—they both print everything because they don't trust tech. Here's the beautiful irony: the "smart" person trusts their code and infrastructure so much they've gone fully digital, while both ends of the spectrum have seen enough production failures, data losses, and "the cloud is just someone else's computer" disasters to know that physical backups aren't just paranoia—they're survival instinct. Sometimes the person who's seen nothing and the person who's seen everything reach the same conclusion, just for wildly different reasons. Plot twist: they're all wrong. The true galaxy brain move is having three cloud backups, two local backups, one printed copy, and still losing everything when you accidentally run rm -rf / in production.

The Engineering Team Are Currently Fixing The Backend Bugs

The Engineering Team Are Currently Fixing The Backend Bugs
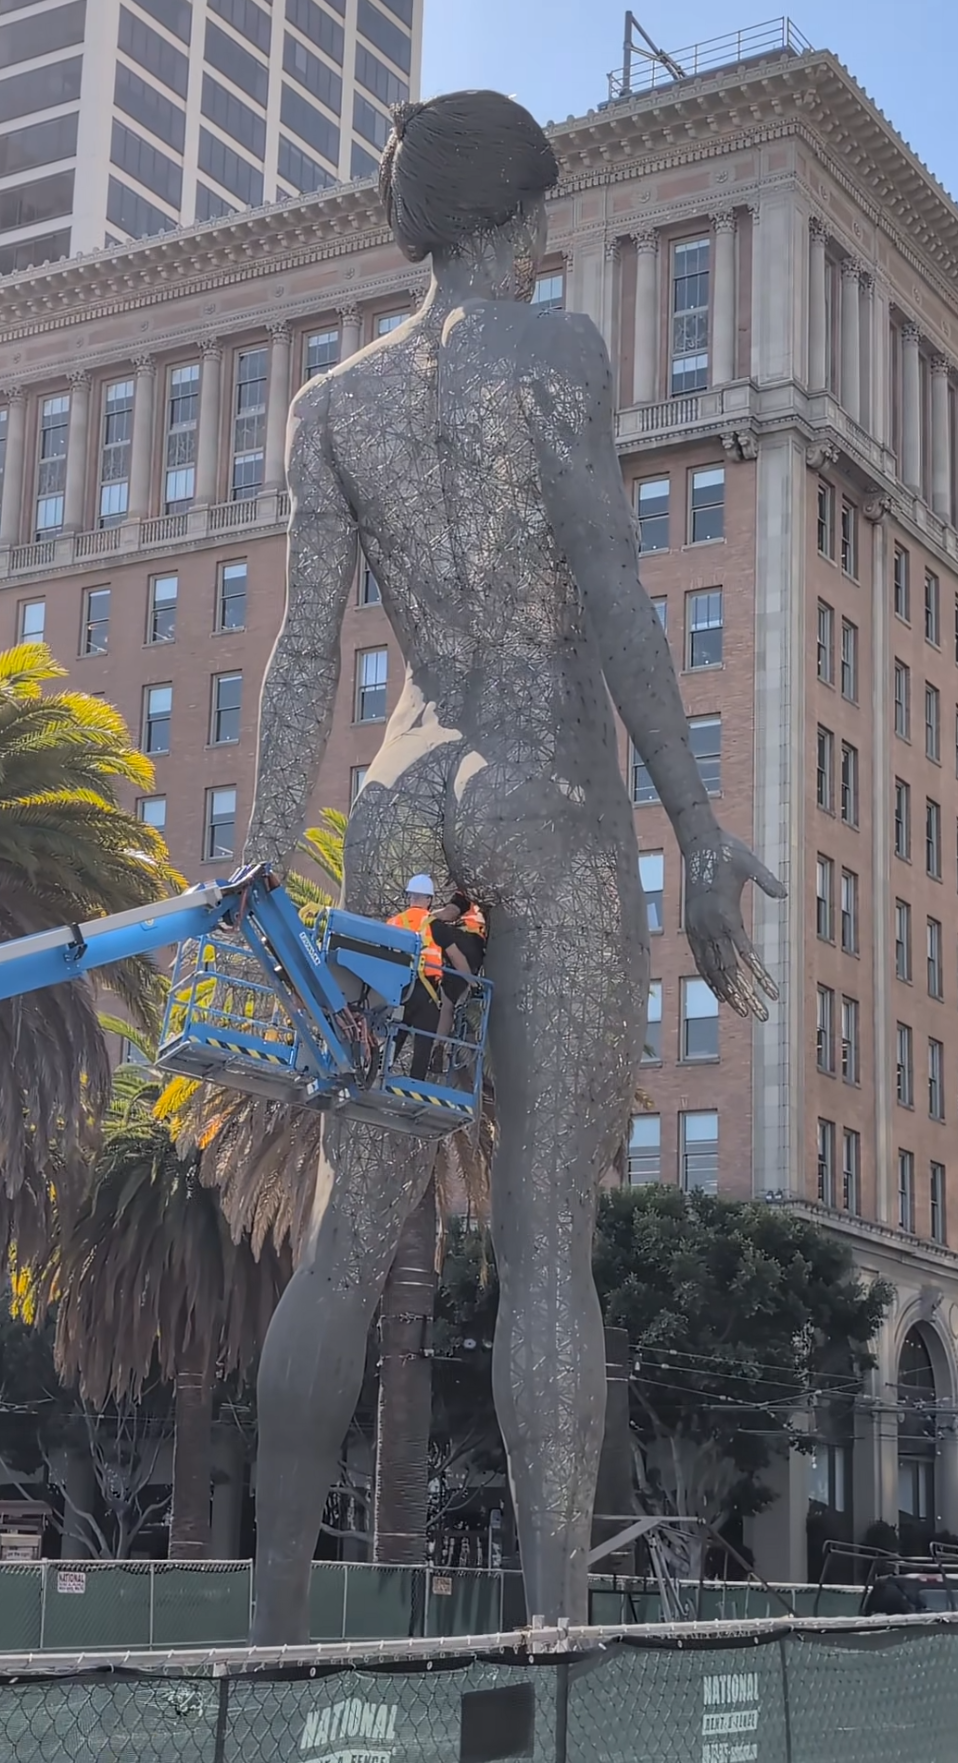
Two guys in a cherry picker working on a giant statue's butt. That's it. That's the entire backend team right there. Nothing says "critical production issue" quite like being suspended 30 feet in the air, literally fixing someone's backend while tourists take photos. The metaphor writes itself. They're probably up there with a pressure washer and a prayer, which coincidentally is the same approach we use for database migrations. At least when you're fixing a statue's backend, you can see the problem. Try explaining to management why the API is down because someone deployed on a Friday.

AI Company Fear Unlocked

AI Company Fear Unlocked
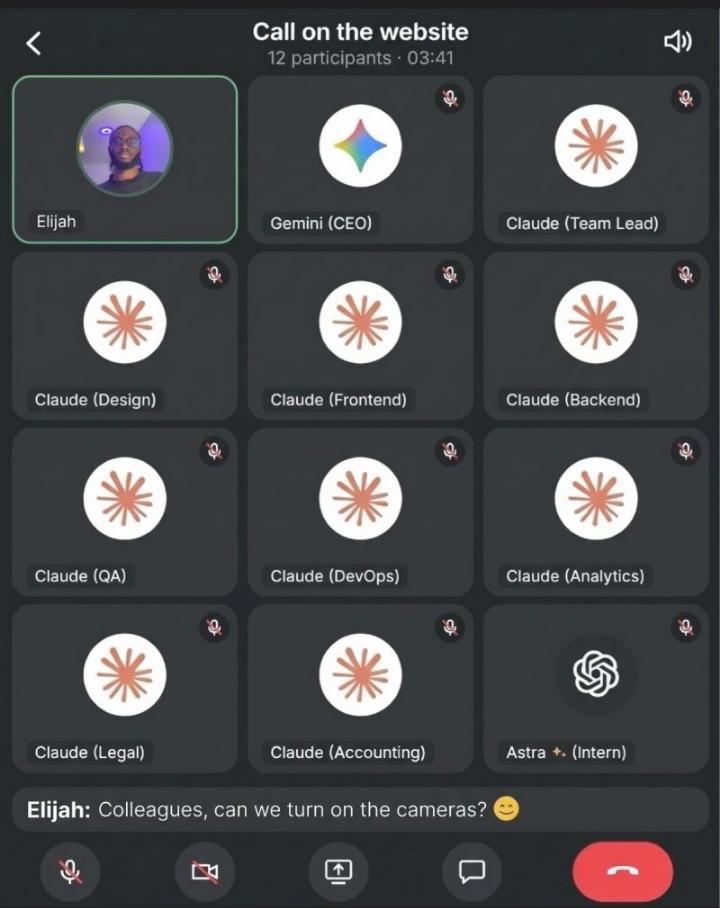
When your entire company is just Claude wearing different hats. CEO? Claude. Team Lead? Claude. Frontend, Backend, DevOps, QA, Legal, Accounting? All Claude. The only human on the call is Elijah, who's probably wondering why he's paying salaries to 10 different Claude API subscriptions. Plot twist: The intern is using a different AI (Astra), which means they're either the rebel of the company or just ran out of Claude API credits. Either way, when Elijah asks everyone to turn on their cameras, someone's about to explain why their "team" can't do video calls. Nothing screams "legitimate startup" quite like a company meeting where 11 out of 12 participants are LLMs.

Microslop

Microslop
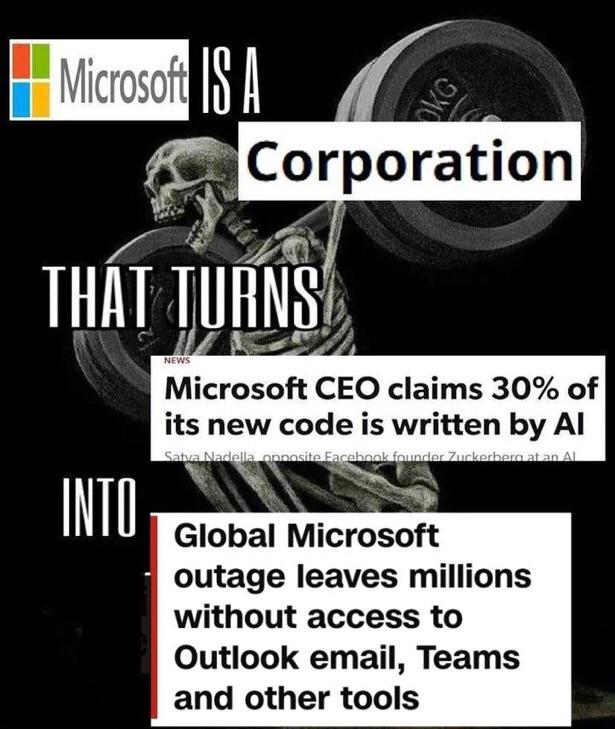
So let me get this straight: 30% of your code is written by AI, and somehow your entire infrastructure still goes down harder than a junior dev's first production deployment? The math ain't mathing here, Microsoft. Nothing screams "cutting-edge AI integration" quite like millions of people unable to check their email because someone probably deployed on a Friday. At this point, I'm convinced the AI is writing the code AND triggering the outages. Peak efficiency. The skeleton waiting meme format really captures the vibe of everyone sitting there refreshing Outlook, watching Teams fail to connect, while Microsoft's PR team frantically types up another "we're investigating" tweet. Maybe next time let the AI write 31% of the code—that extra 1% might include error handling.

Push To Prod Make No Mistakes

Push To Prod Make No Mistakes
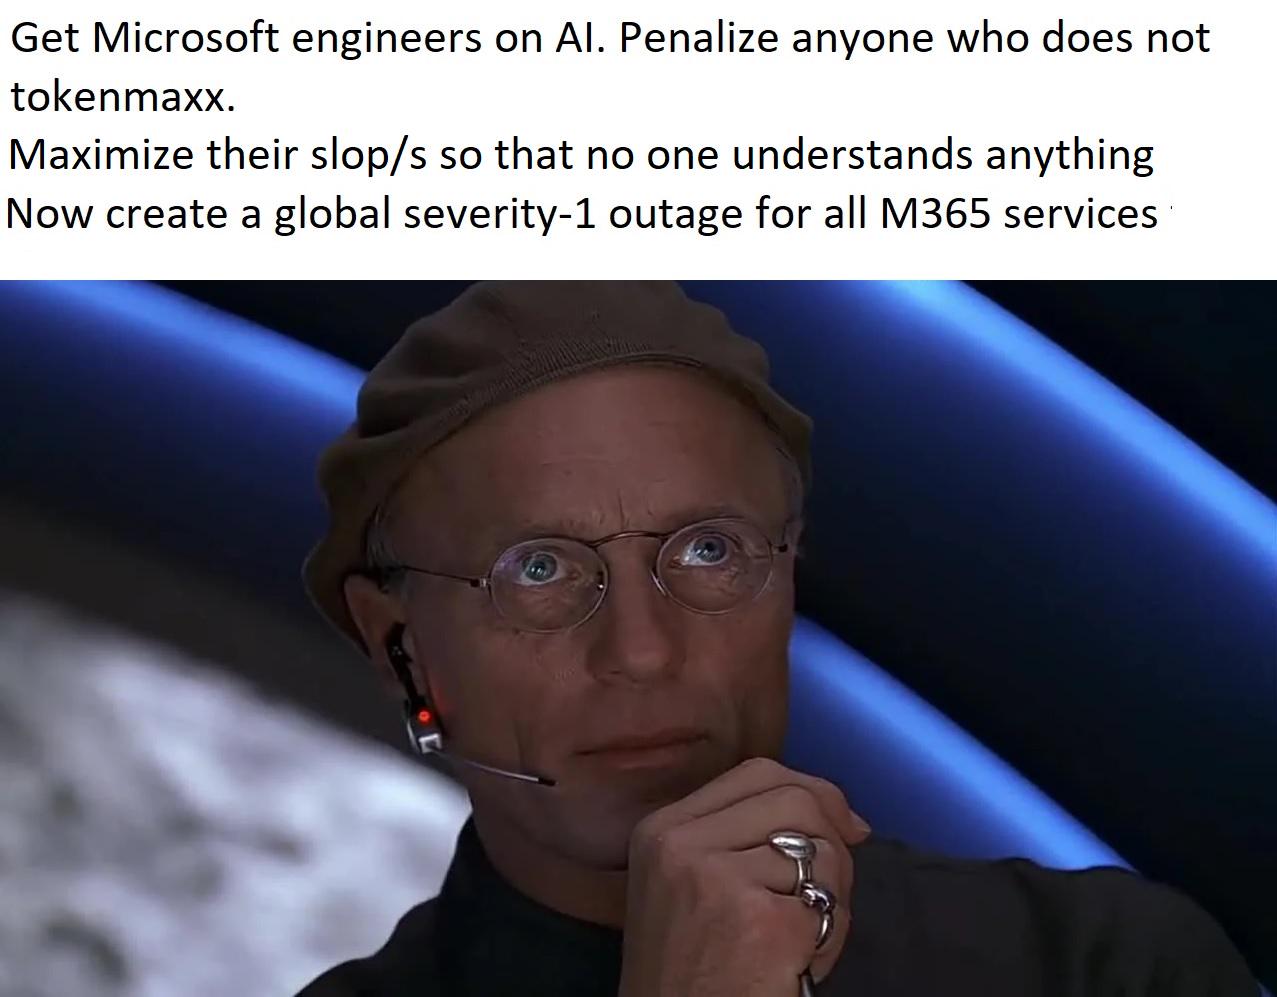
So the master plan is to hire Microsoft engineers to work on AI, make the codebase so incomprehensible that even the people who wrote it can't debug it, then maximize their slop-per-second output until the whole thing becomes sentient garbage. Finally, take down all M365 services worldwide in a severity-1 outage. Flawless execution, really. This is basically a satirical recipe for corporate disaster that hits different when you remember Microsoft has actually had several global outages that took down Teams, Outlook, and Azure simultaneously. The "tokenmaxx" and "slop/s" terminology is chef's kiss - perfectly capturing that AI hype cycle energy where we're just maximizing output metrics without caring about quality. The villain plotting face really sells it. Sometimes the best way to take down production isn't a sophisticated attack - it's just letting engineers optimize for the wrong metrics and watching the inevitable cascade failure unfold.

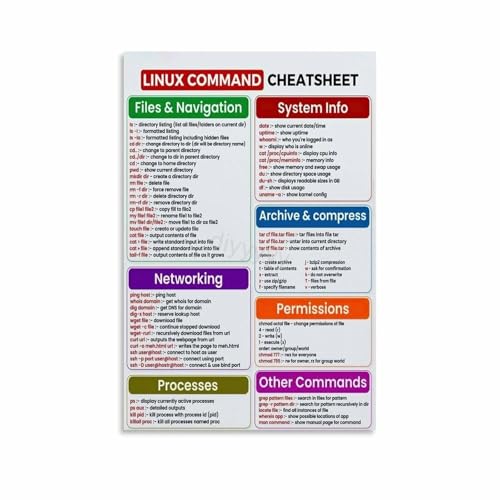
Programmer Poster Linux Commands Cheat Sheet

Programmer Poster Linux Commands Cheat Sheet
We have reserved a 0.6in (1.5cm) white margin for you, which is convenient for you to frame with a photo frame · Canvas posters are different from paper posters in that they will not deteriorate due …

Microsoft 365 Down

Microsoft 365 Down
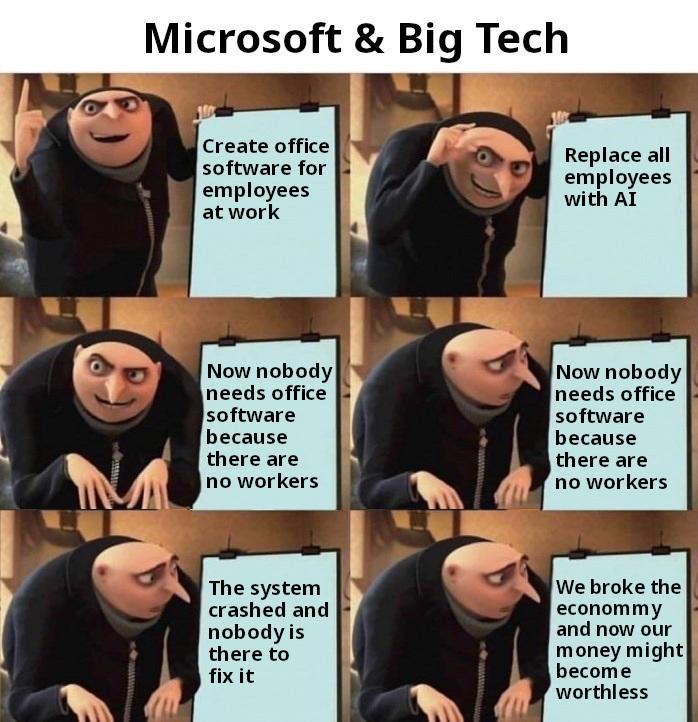
Big Tech's master plan: Create essential office software that literally everyone depends on, then replace all the humans with AI to save costs. Genius, right? WRONG. Because now when the system inevitably crashes, there's nobody left who actually knows how to fix it. The cherry on top? The economy is now tanking because your "brilliant" cost-cutting measures left you with a bunch of robots staring at error logs they can't understand. It's giving "I played myself" energy on a COSMIC scale. The Gru template captures the exact moment of realization when corporate greed meets the harsh reality that maybe, just maybe, you need actual humans to keep the lights on.

It's Always DNS But Also Copilot

It's Always DNS But Also Copilot
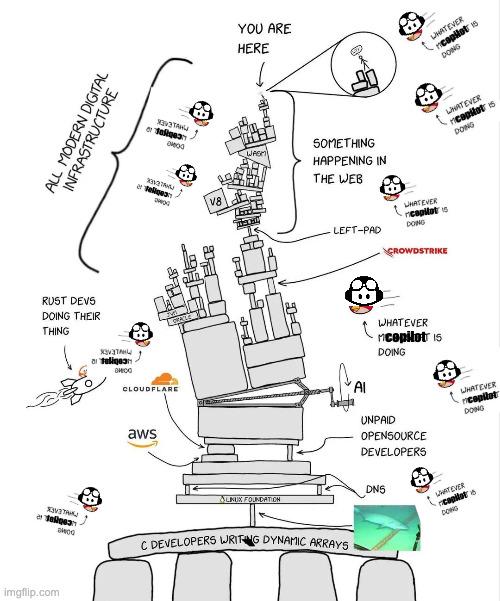
Behold the modern web stack: a precarious Jenga tower of chaos where one wrong move brings EVERYTHING crashing down! You've got AWS holding up DNS, which supports unpaid open-source developers (bless their souls), who somehow carry the entire internet on their backs. Meanwhile, Copilot is just vibing everywhere like "whatever I am doing" because let's be real, half the time we don't even know what code it just generated. Left-pad is chilling there as a permanent reminder of that one npm package that broke the internet. CrowdStrike makes an appearance because why not add some spicy security drama to the mix. And at the very bottom? C developers writing dynamic arrays, literally the foundation holding up this entire circus. The Rust devs are doing their thing on Cloudflare (naturally), while "all modern work infrastructure" somehow balances on top of this engineering nightmare. It's beautiful. It's terrifying. It's accurate.

Now With Scheduled Disappointment

Now With Scheduled Disappointment
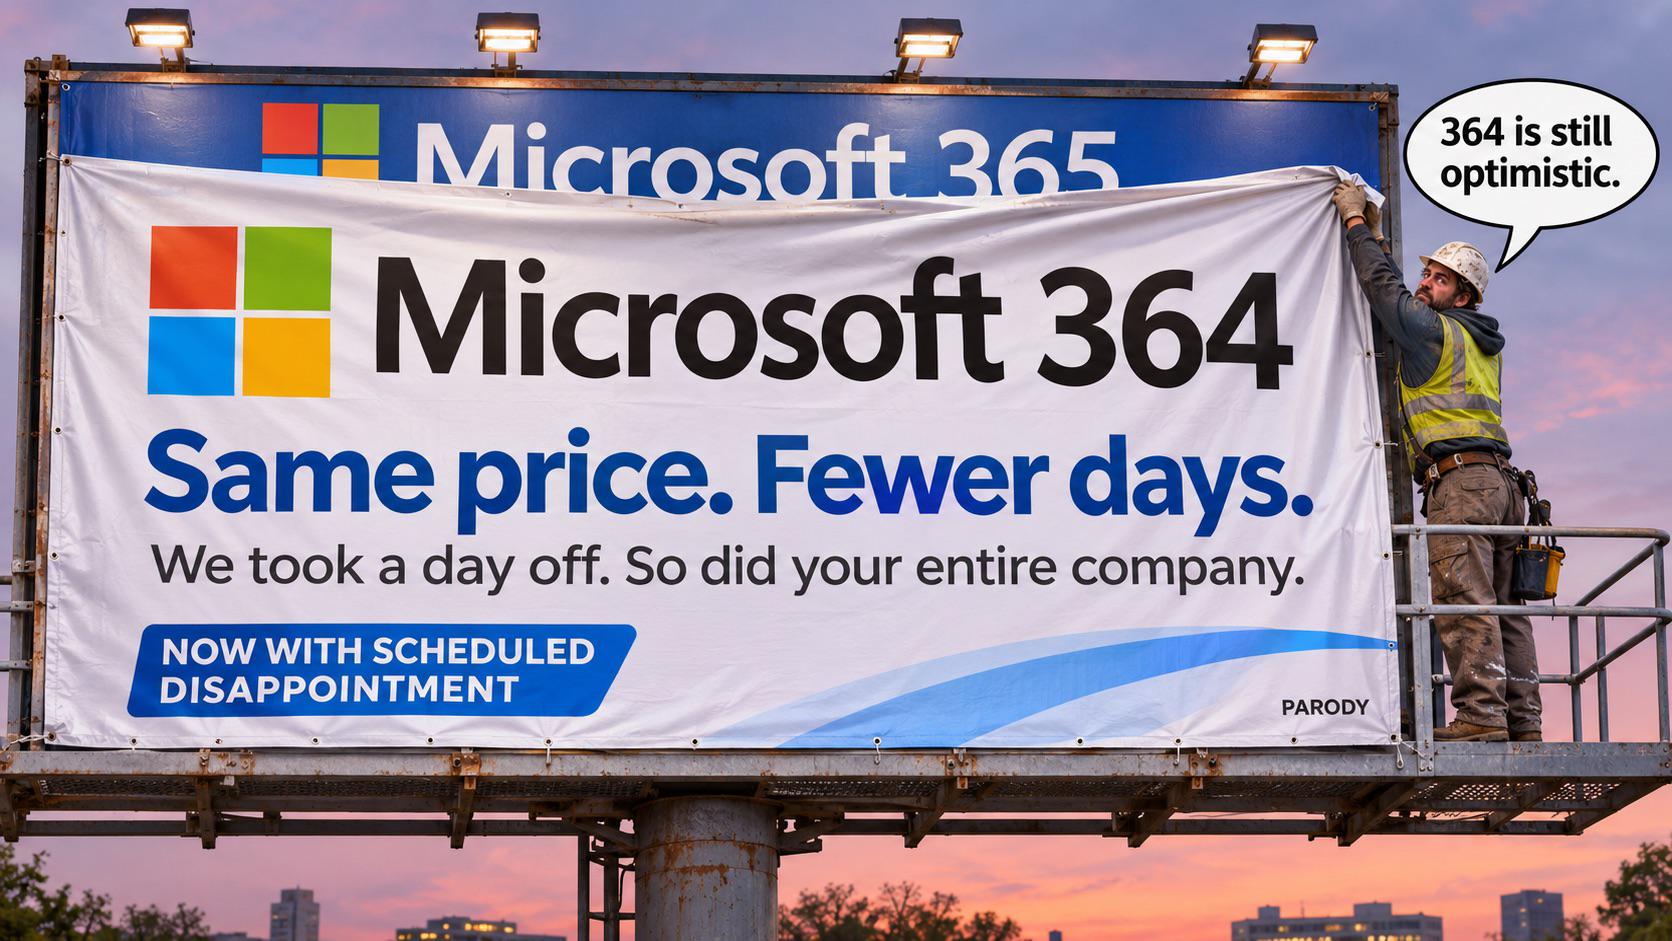
Someone finally said what we've all been thinking. Microsoft 365 promises you service 365 days a year, but let's be honest—between the random outages, Teams deciding to freeze during important meetings, and Outlook just... existing, you're lucky if you get 364 functional days. The parody billboard brilliantly captures the essence of enterprise software: "Same price. Fewer days. We took a day off. So did your entire company." Because nothing says productivity like scheduled downtime that somehow always happens during critical business hours. The speech bubble "364 is still optimistic" is chef's kiss—because we all know that number is generous. Between authentication issues, sync failures, and the classic "this service is temporarily unavailable," you're probably getting closer to Microsoft 300 at best. But hey, at least the disappointment is scheduled now, right?

Devs At Microsoft Right Now

Devs At Microsoft Right Now
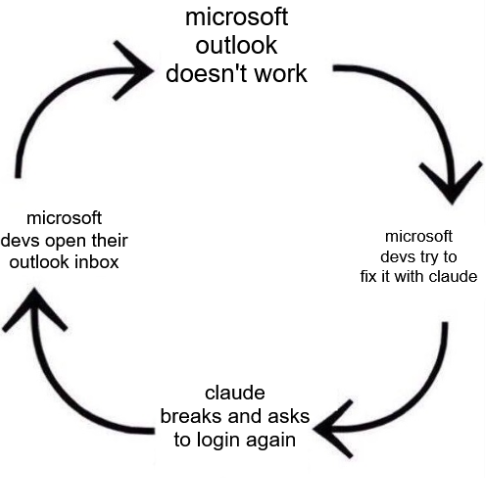
The infinite loop of corporate irony. Microsoft devs can't access Outlook to check their emails, so naturally they turn to Claude (an AI chatbot) to fix it. Claude promptly breaks and requires them to... log in again. Through Outlook. Which doesn't work. Which is why they needed Claude in the first place. It's like trying to recover your password using the email you can't access. Except this time you've added a billion-dollar AI into the mix that's somehow making things worse. The circle of enterprise software dysfunction continues unbroken.

Slop Starts With An S So As Satya

Slop Starts With An S So As Satya
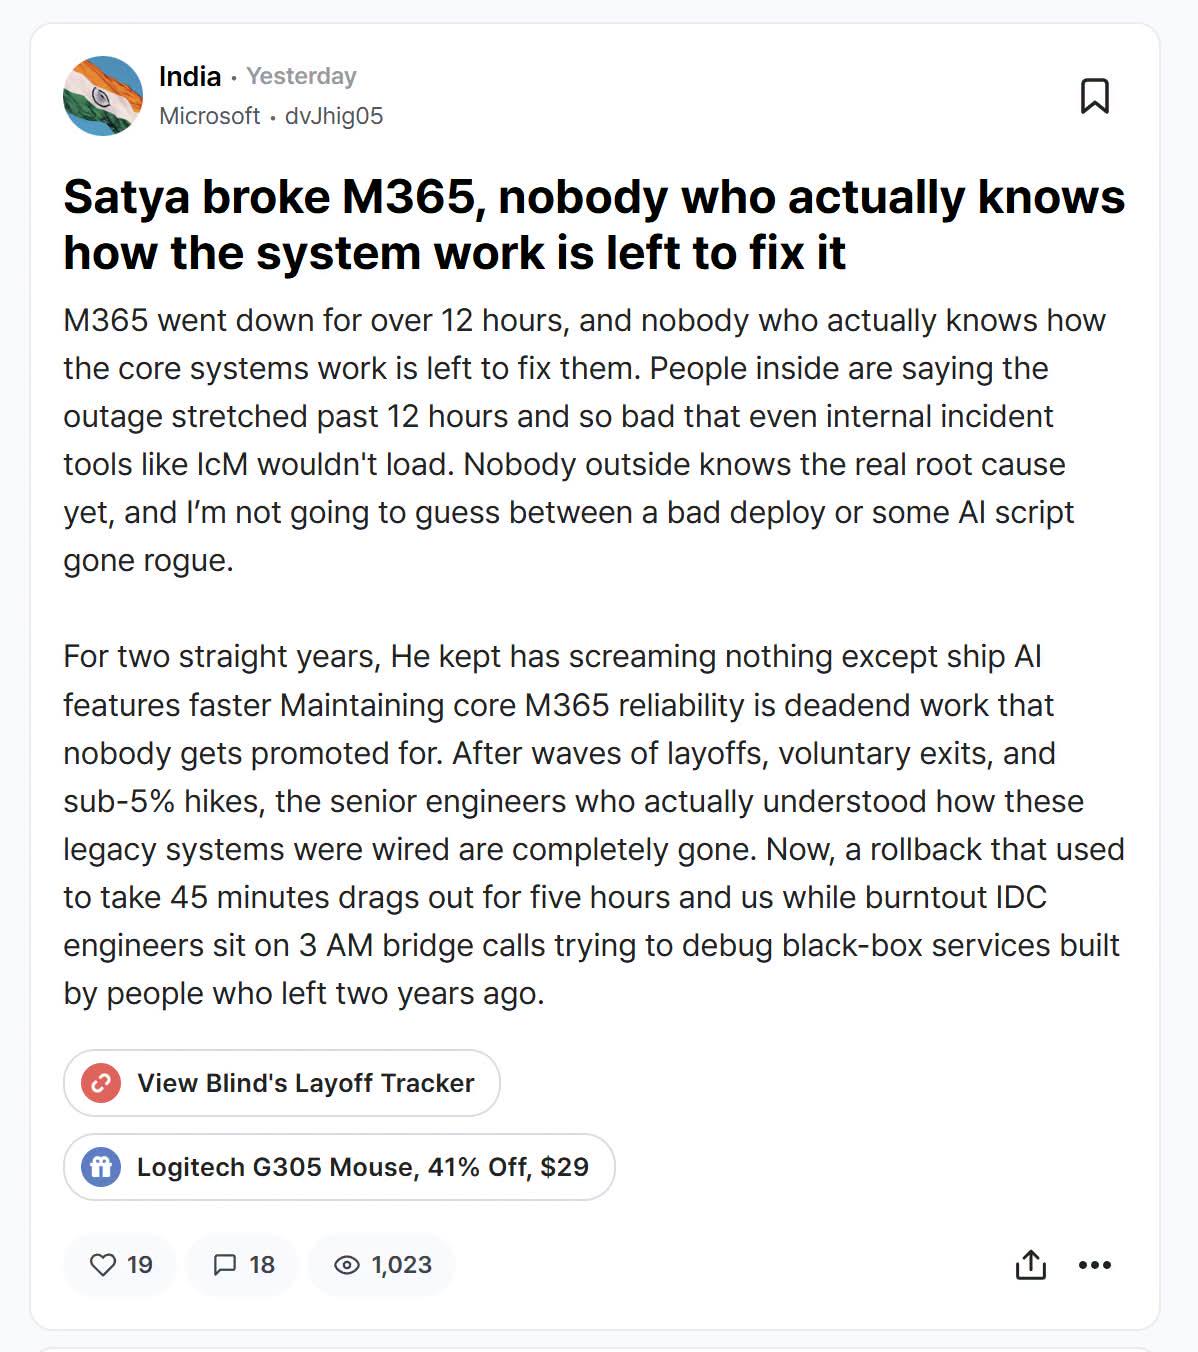
Satya Nadella's Microsoft speedran the classic tech company arc: fire all the engineers who know how things work, replace them with AI hype merchants, then act surprised when M365 implodes for 12+ hours. Turns out "move fast and break things" hits different when you're breaking enterprise infrastructure that millions depend on. The brutal reality? Two years of prioritizing AI slop over infrastructure maintenance means the people who could actually fix the legacy systems are either gone or burned out. Now rollbacks that used to take 45 minutes are five-hour ordeals while exhausted engineers debug black-box services on bridge calls, desperately trying to reverse-engineer code written by colleagues who took the layoff package years ago. But hey, at least they're shipping AI features faster! Who needs reliability when you have Copilot suggesting code that doesn't compile? The "S" in Satya clearly stands for "Sustainability" (of critical infrastructure).

Office 364

Office 364
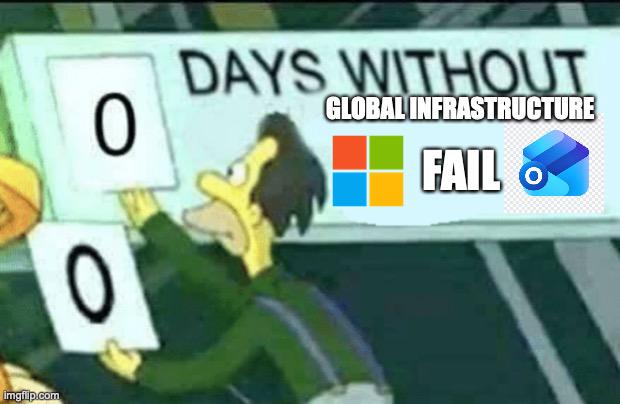
Microsoft's cloud services going down is basically a corporate holiday at this point. The title "Office 364" is *chef's kiss* because let's be real, Office 365 is available 364 days a year if you're lucky. That one day? Could be your product launch, your quarterly earnings call, or literally any Tuesday when Mercury isn't even in retrograde. Companies pay premium subscriptions for the privilege of watching their entire workforce stare at error messages while Microsoft tweets "We're investigating reports of service degradation" like they just discovered fire. Nothing says "enterprise-grade reliability" quite like global infrastructure that treats uptime like a suggestion rather than a promise.