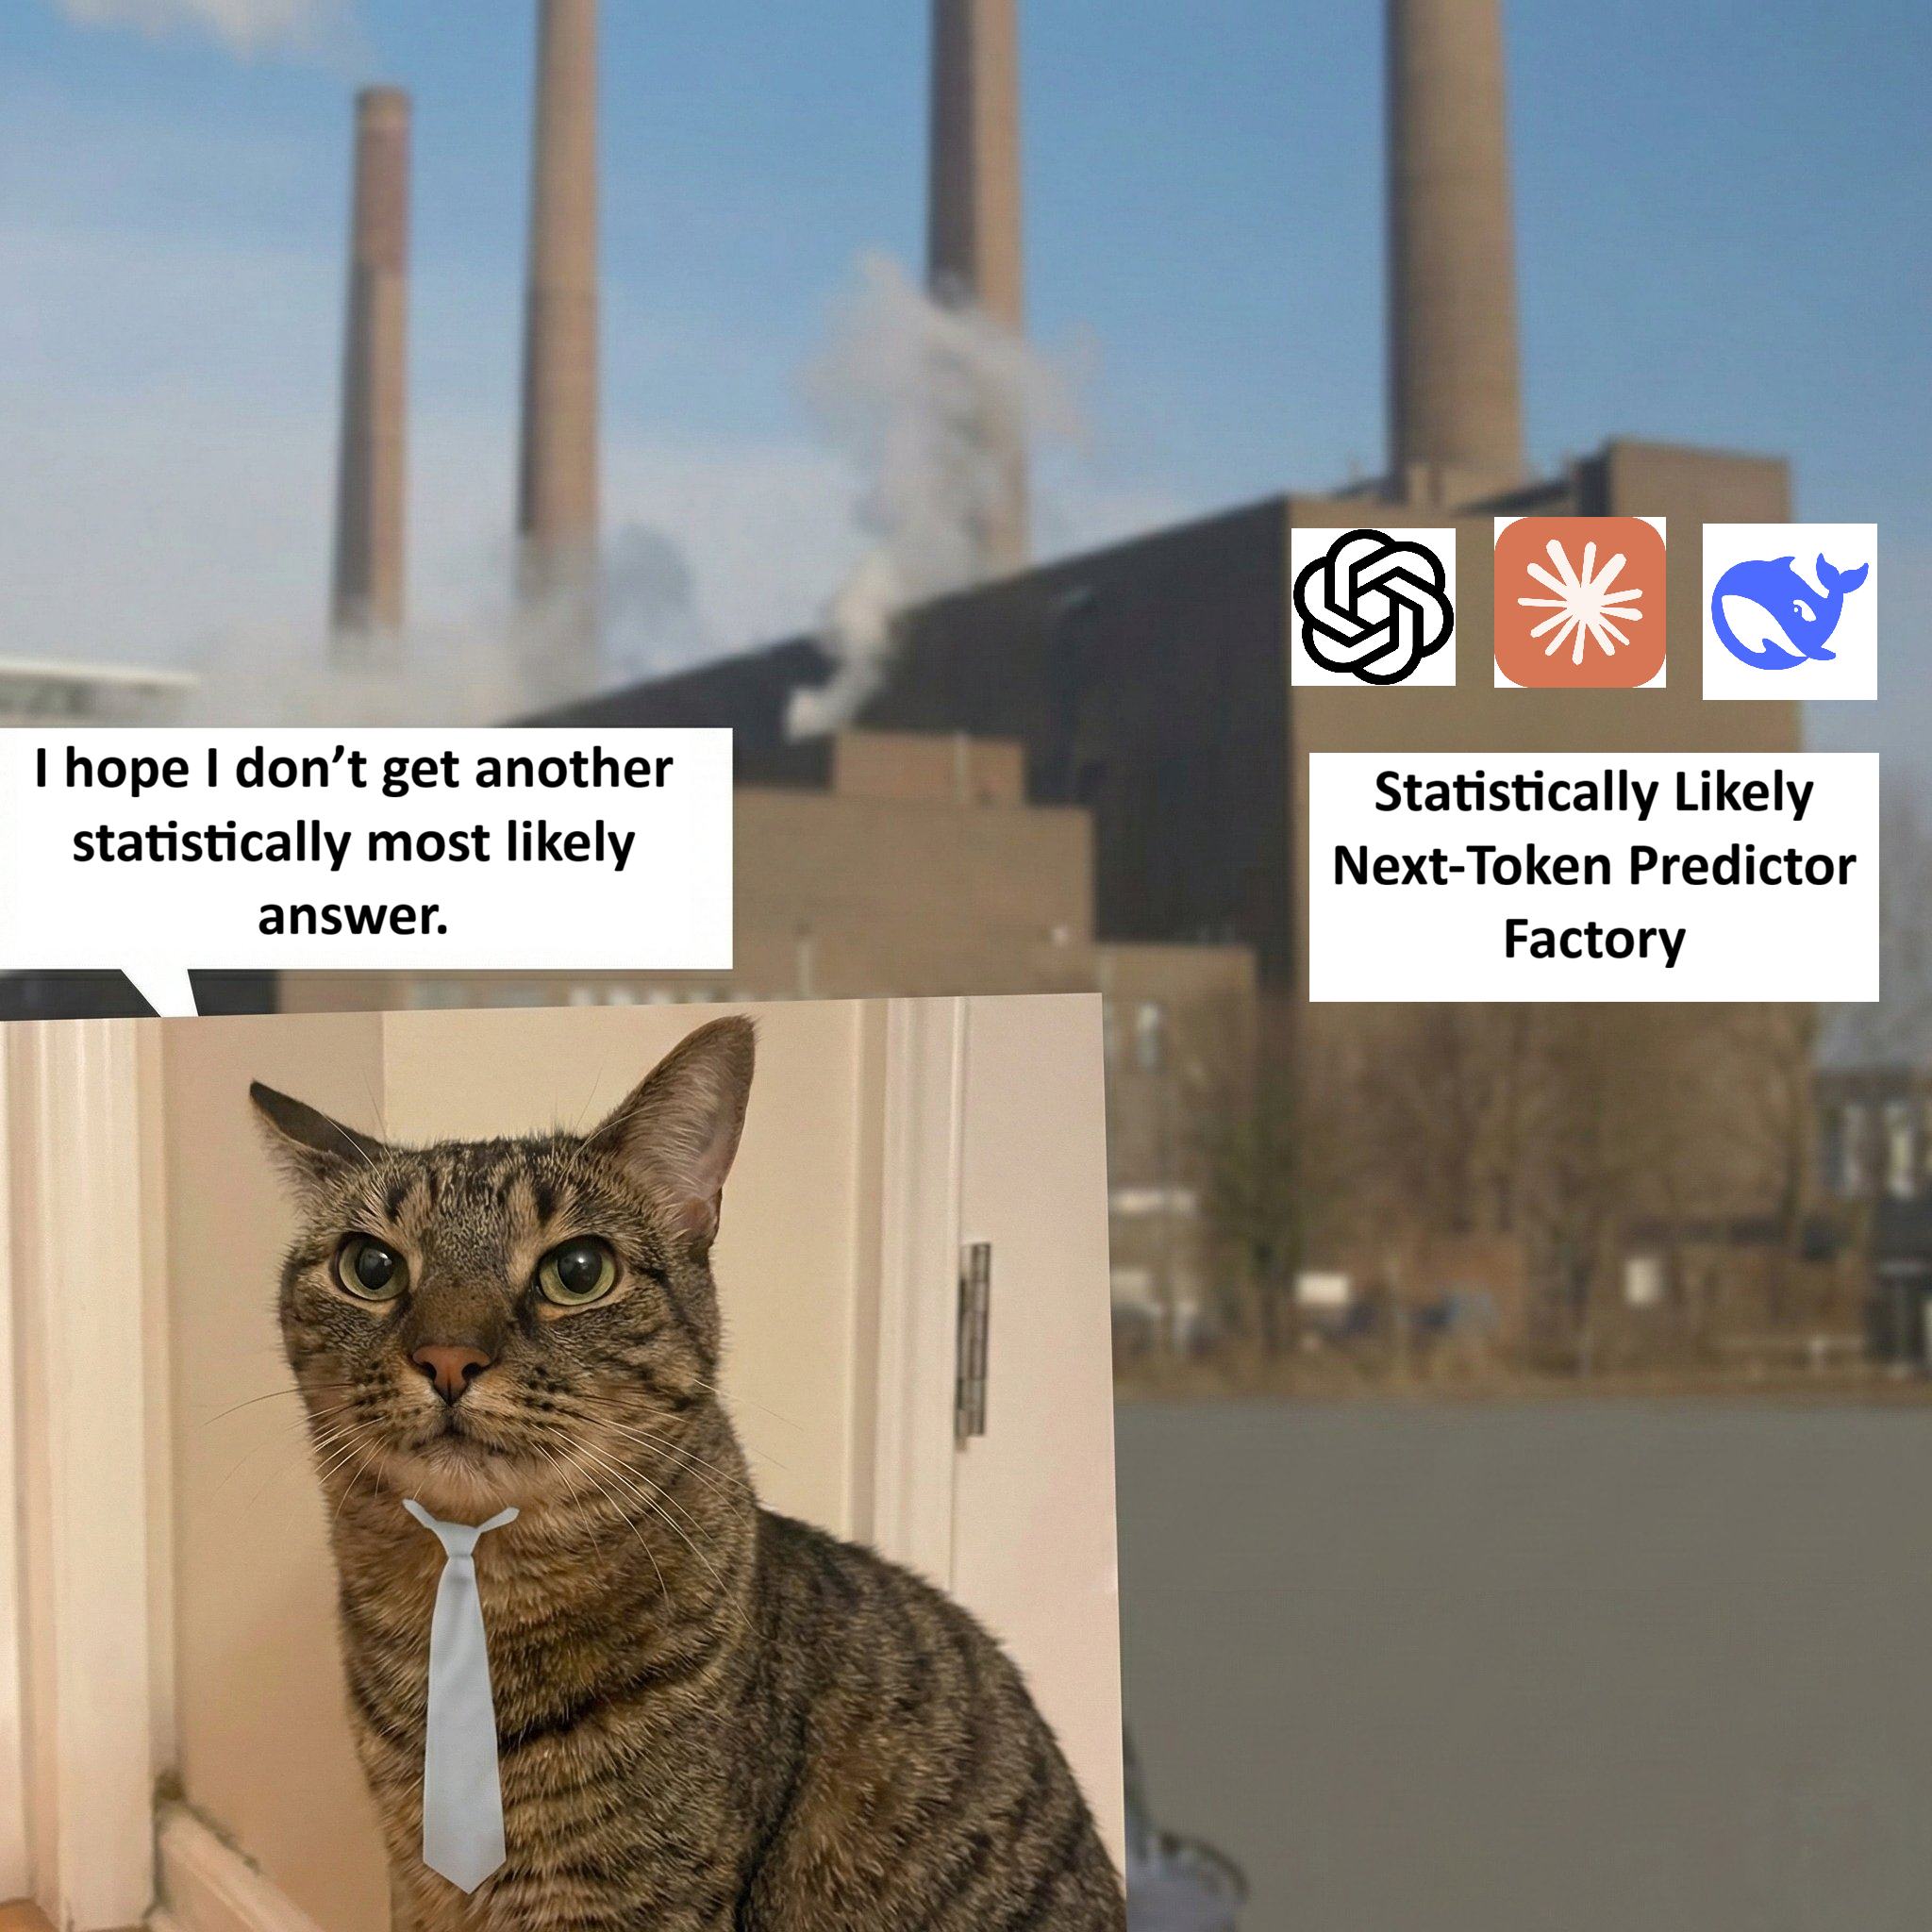
The business cat is nervously eyeing those pollution-spewing smokestacks labeled "Statistically Likely Next-Token Predictor Factory" because he knows exactly what's coming. Every time you ask an LLM a question, it's not actually reasoning or understanding—it's just playing an incredibly sophisticated game of "what word comes next?" based on probability distributions. So when you ask ChatGPT or Claude something nuanced, there's always that lurking dread that instead of a thoughtful answer, you'll get the statistically most probable response that sounds confident but is completely hallucinated. It's like asking a parrot that's read the entire internet—sure, it sounds smart, but it's fundamentally just predicting tokens based on training data patterns. The factory imagery is chef's kiss because it captures how these models are literally industrial-scale probability machines churning out tokens. No consciousness, no real understanding—just pure statistical inference at massive scale. And yet here we are, trusting them to write our code, debug our apps, and explain complex concepts. What could possibly go wrong? 🎲