production Memes

Fuck Fuck Fuck Fuck Fuck Fuck

Fuck Fuck Fuck Fuck Fuck Fuck
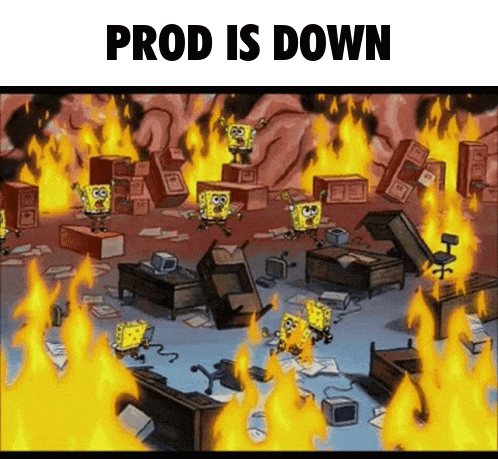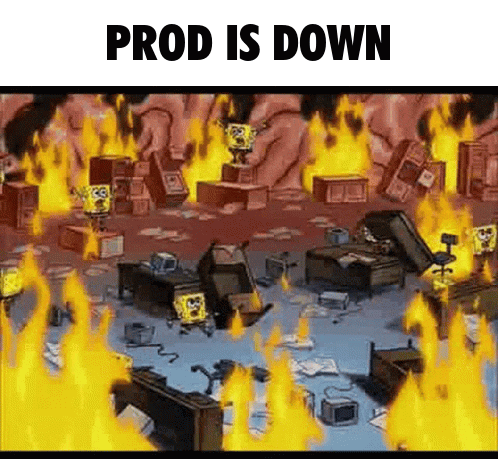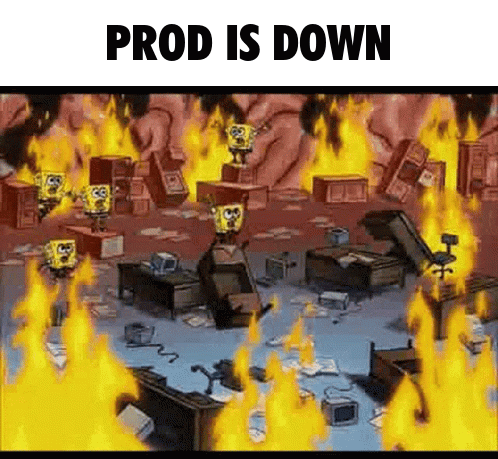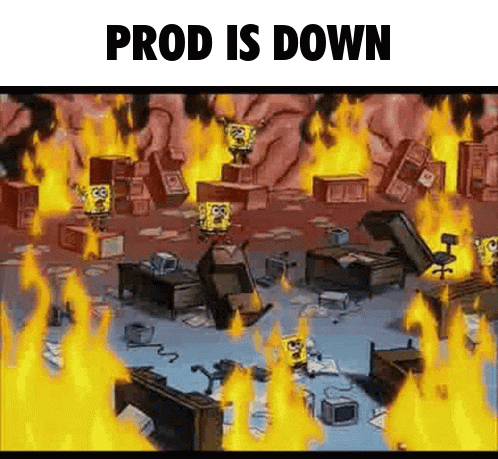
Nothing quite captures the sheer existential terror of watching your production environment go up in flames while you're frantically trying to figure out what broke. Everyone's running around like headless chickens, keyboards are being smashed, error logs are scrolling faster than you can read, and somewhere in the distance you can hear your manager screaming into a phone. Meanwhile, you're desperately trying to remember if you actually tested that deployment you pushed 5 minutes ago or if you just YOLO'd it straight to prod because "it worked on my machine." Spoiler alert: it did NOT work on their machines. The incident channel is blowing up, customers are rage-tweeting, and you're seriously reconsidering every life choice that led you to this career. Welcome to the glamorous world of software engineering, where everything is fine until it absolutely, catastrophically isn't.

My Software Just Got Recruited Into A College Basketball Team

My Software Just Got Recruited Into A College Basketball Team
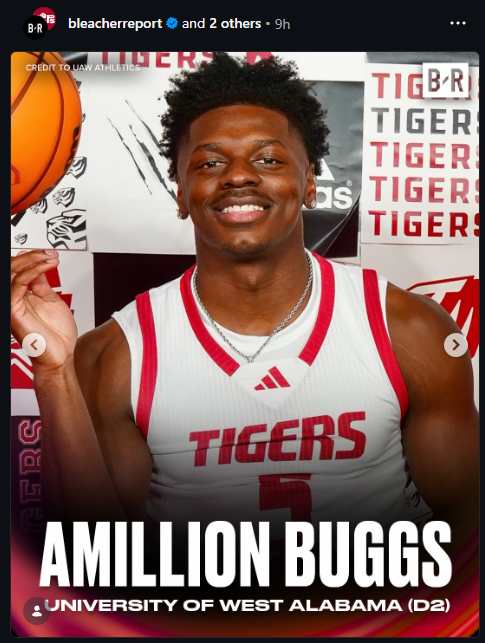
So your code has reached that special level of brokenness where it's literally got "a million bugs" and somehow that qualifies it for a D2 basketball scholarship. The recruiting process must've been wild - "What's your vertical?" "About 500 stack traces per second." Real talk though, we've all shipped code that could probably start at point guard for a mid-tier college team based purely on its bug count. The production environment is just a different kind of court where your software commits fouls every possession and the refs (users) are not happy about it. At least when you have a million bugs, you can't be accused of having just one critical issue - you've got diversity in your failures. That's called being well-rounded.

Temporary Fix

Temporary Fix
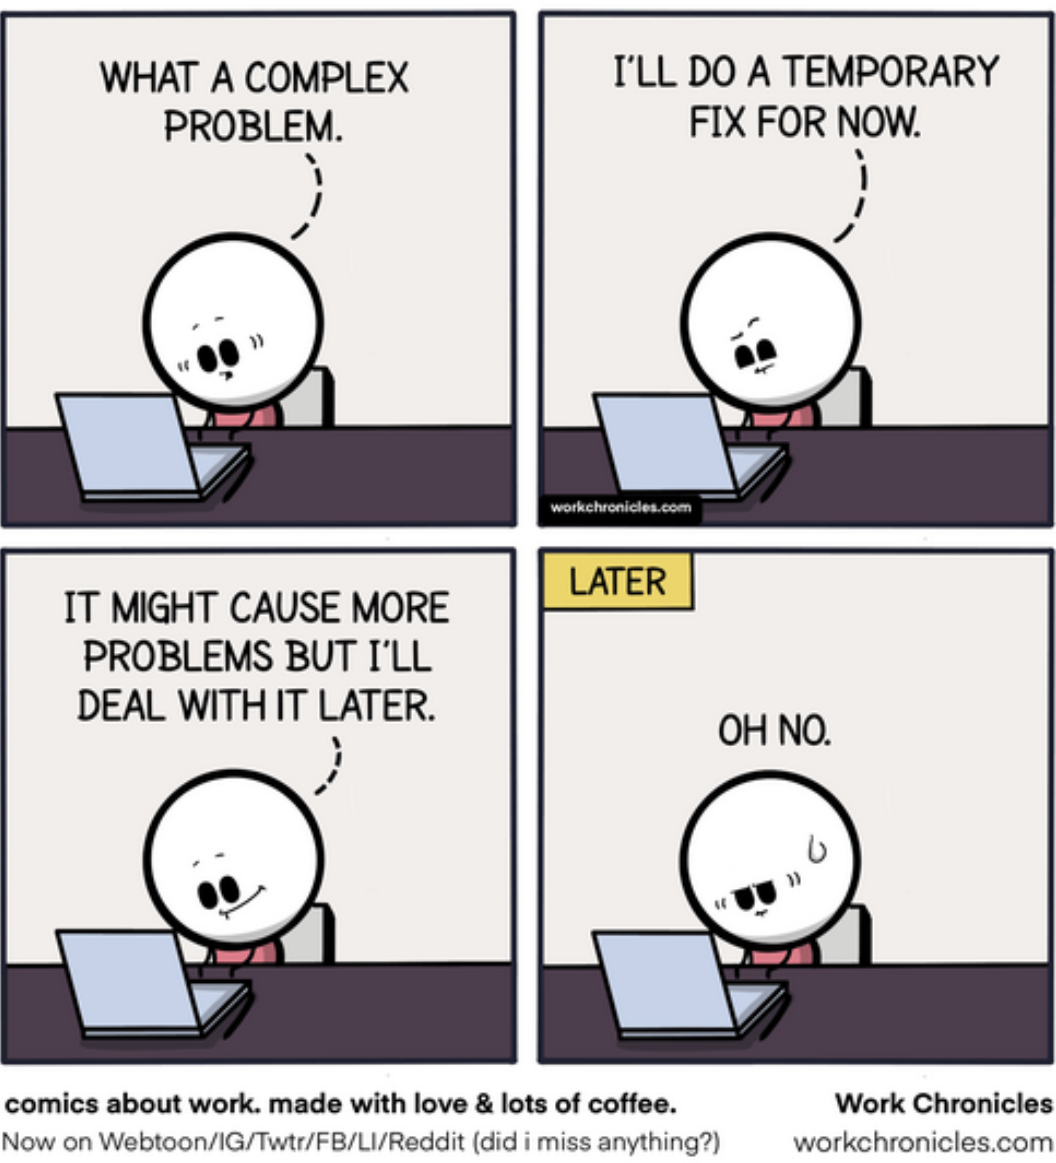
Nothing screams "production-ready code" quite like a bandaid solution that you pinky promise you'll come back to fix properly. The developer's thought process here is flawless: encounter a gnarly bug, slap on a quick workaround, acknowledge it might create cascading issues down the line, and then... just trust that Future You will handle it. Spoiler alert: Future You is currently dealing with 47 other "temporary" fixes from the past six months. The real kicker? That temporary fix becomes permanent the moment it touches production. It'll outlive your tenure at the company, survive three major refactors, and eventually become "legacy code that nobody dares to touch." Someone will find it in 2027 with a TODO comment dated 2023 and wonder what kind of chaos would unfold if they actually tried to fix it properly.

When The Impossible Meets The Scalable

When The Impossible Meets The Scalable
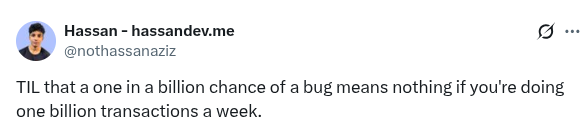
Ah yes, the beautiful paradox of scale. That "one in a billion" edge case you dismissed in code review? Congrats, at a billion transactions per week, you're now guaranteed to hit it every single week . It's like Murphy's Law got a performance upgrade. Your "this will never happen" becomes "this happens every Tuesday at 2 PM." Scale doesn't just amplify your success—it weaponizes your assumptions and turns theoretical impossibilities into production incidents with SLAs attached.

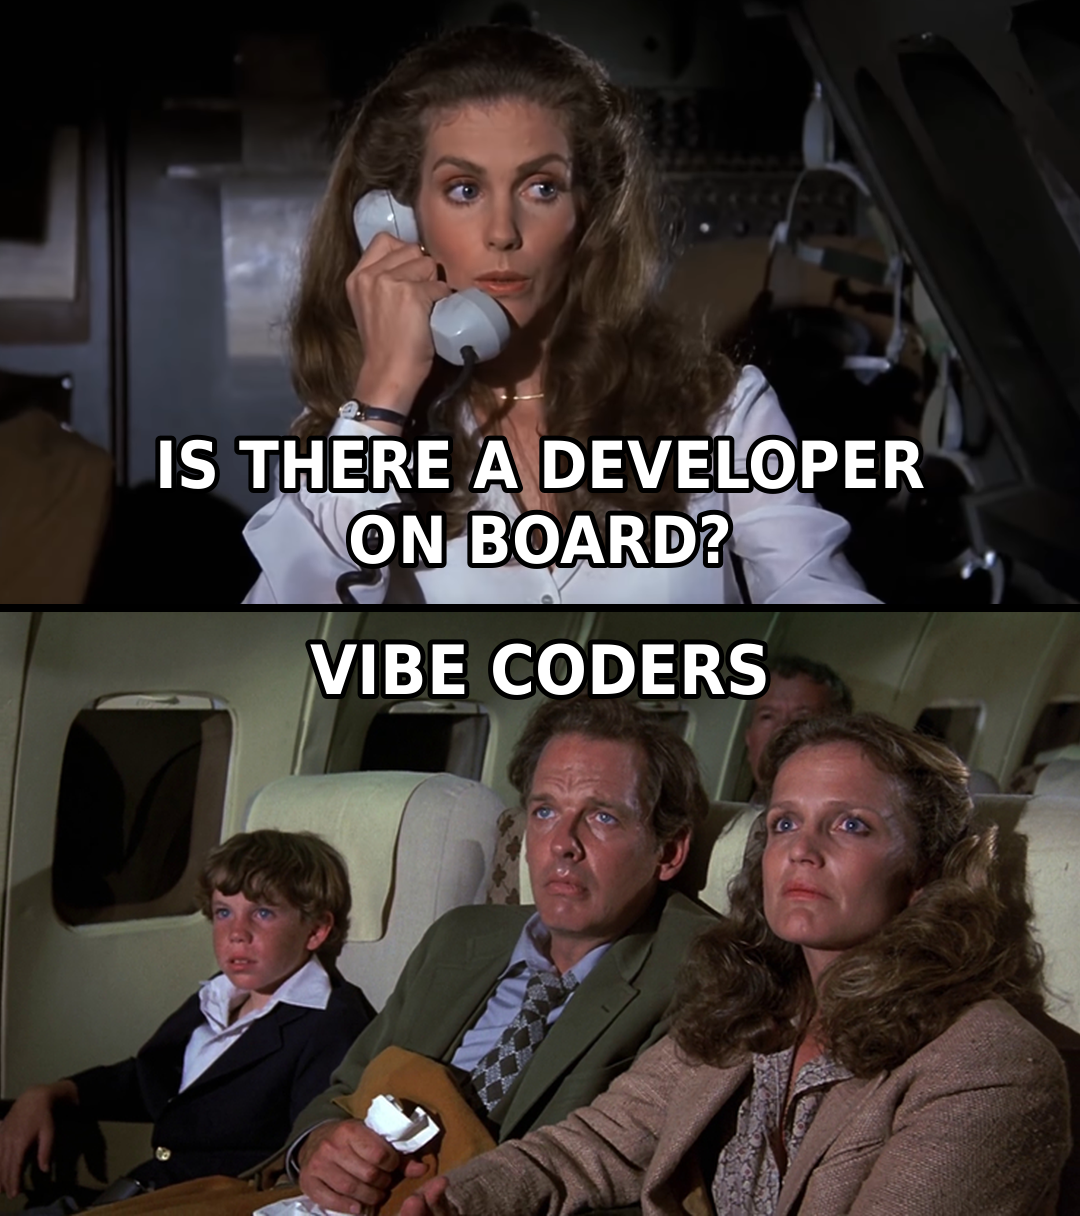
The API Is Down

The API Is Down
When production goes down and management frantically searches for someone who can actually fix things, only to find the entire dev team has suddenly become unreachable. You know those "vibe coders" who spend their standup talking about their side hustle NFT project? Yeah, they're nowhere to be found when the 500 errors start rolling in. Meanwhile, the one senior dev who actually knows the codebase is on a flight with their phone on airplane mode, living their best life while Slack is burning down back at the office. The panic in those passengers' eyes says it all—that's every PM when they realize the API they depend on is actually held together with duct tape and prayers by developers who are currently "in a meeting" (read: pretending not to see notifications).

OneOdio Pro-30 Over Ear Headphone, Wired Premium Stereo Sound Headsets with 50mm Driver, Foldable Comfortable Headphones with Protein Earmuffs and Shareport for Recording Monitoring Podcast PC

OneOdio Pro-30 Over Ear Headphone, Wired Premium Stereo Sound Headsets with 50mm Driver, Foldable Comfortable Headphones with Protein Earmuffs and Shareport for Recording Monitoring Podcast PC
BASS SOUND: Enjoy powerful bass and comfort with the OneOdio Studio headphones. Large 50 millimeter speaker unit drivers combined with neodymium magnets deliver dynamic bass, great for DJing, mixing,…

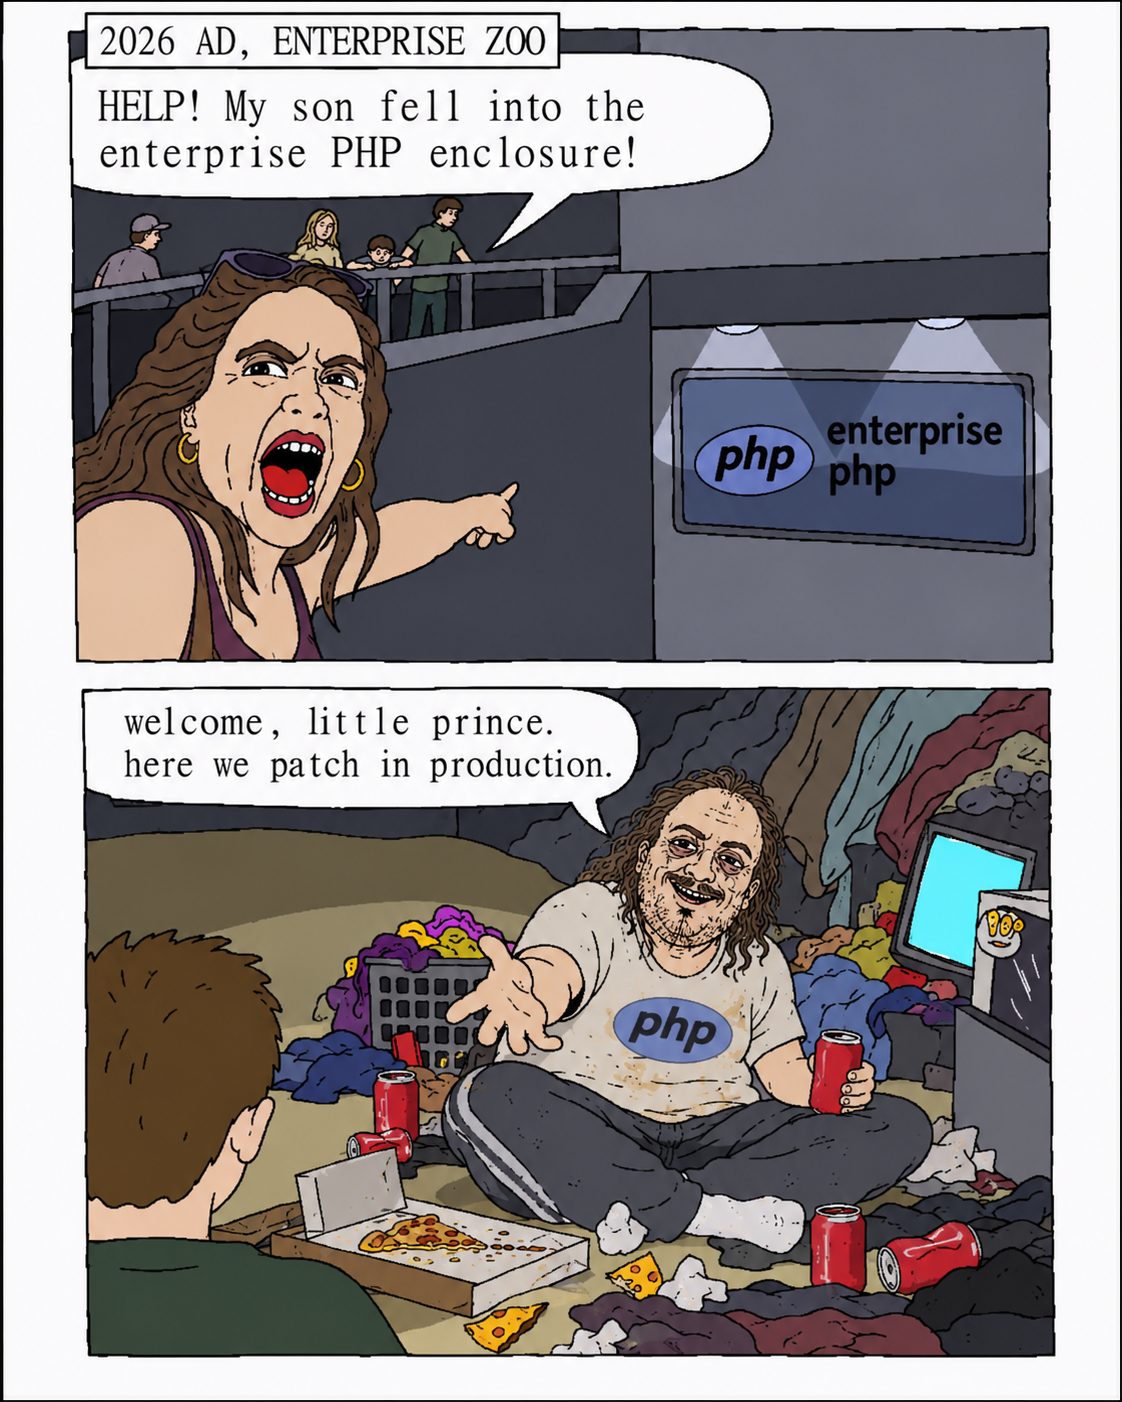
We Patch In Production

We Patch In Production
Set in the year 2026 at an "Enterprise Zoo," where legacy PHP applications are kept alive like endangered species. A parent screams in horror as their child has fallen into the enterprise PHP enclosure—a fate worse than any regular zoo accident. But down in the enclosure, there's no danger. Just a disheveled developer in a PHP t-shirt, surrounded by pizza boxes, energy drink cans, and the general chaos of a production environment that doubles as living quarters. His greeting? "Welcome, little prince. Here we patch in production." The joke brilliantly captures the horror of enterprise PHP codebases that have been running (and being patched directly in production) for so long that they've become their own ecosystem. No staging environments, no CI/CD pipelines, no proper deployment processes—just cowboy coding straight to prod with a side of pepperoni. The "zoo enclosure" metaphor perfectly represents how these systems are observed from a distance with a mix of fear and fascination, while the developers maintaining them have essentially gone feral, adapted to their environment, and accepted their fate. The dystopian future of 2026 implies that somehow, against all odds, these legacy systems will still be running two years from now. Spoiler alert: they absolutely will be.

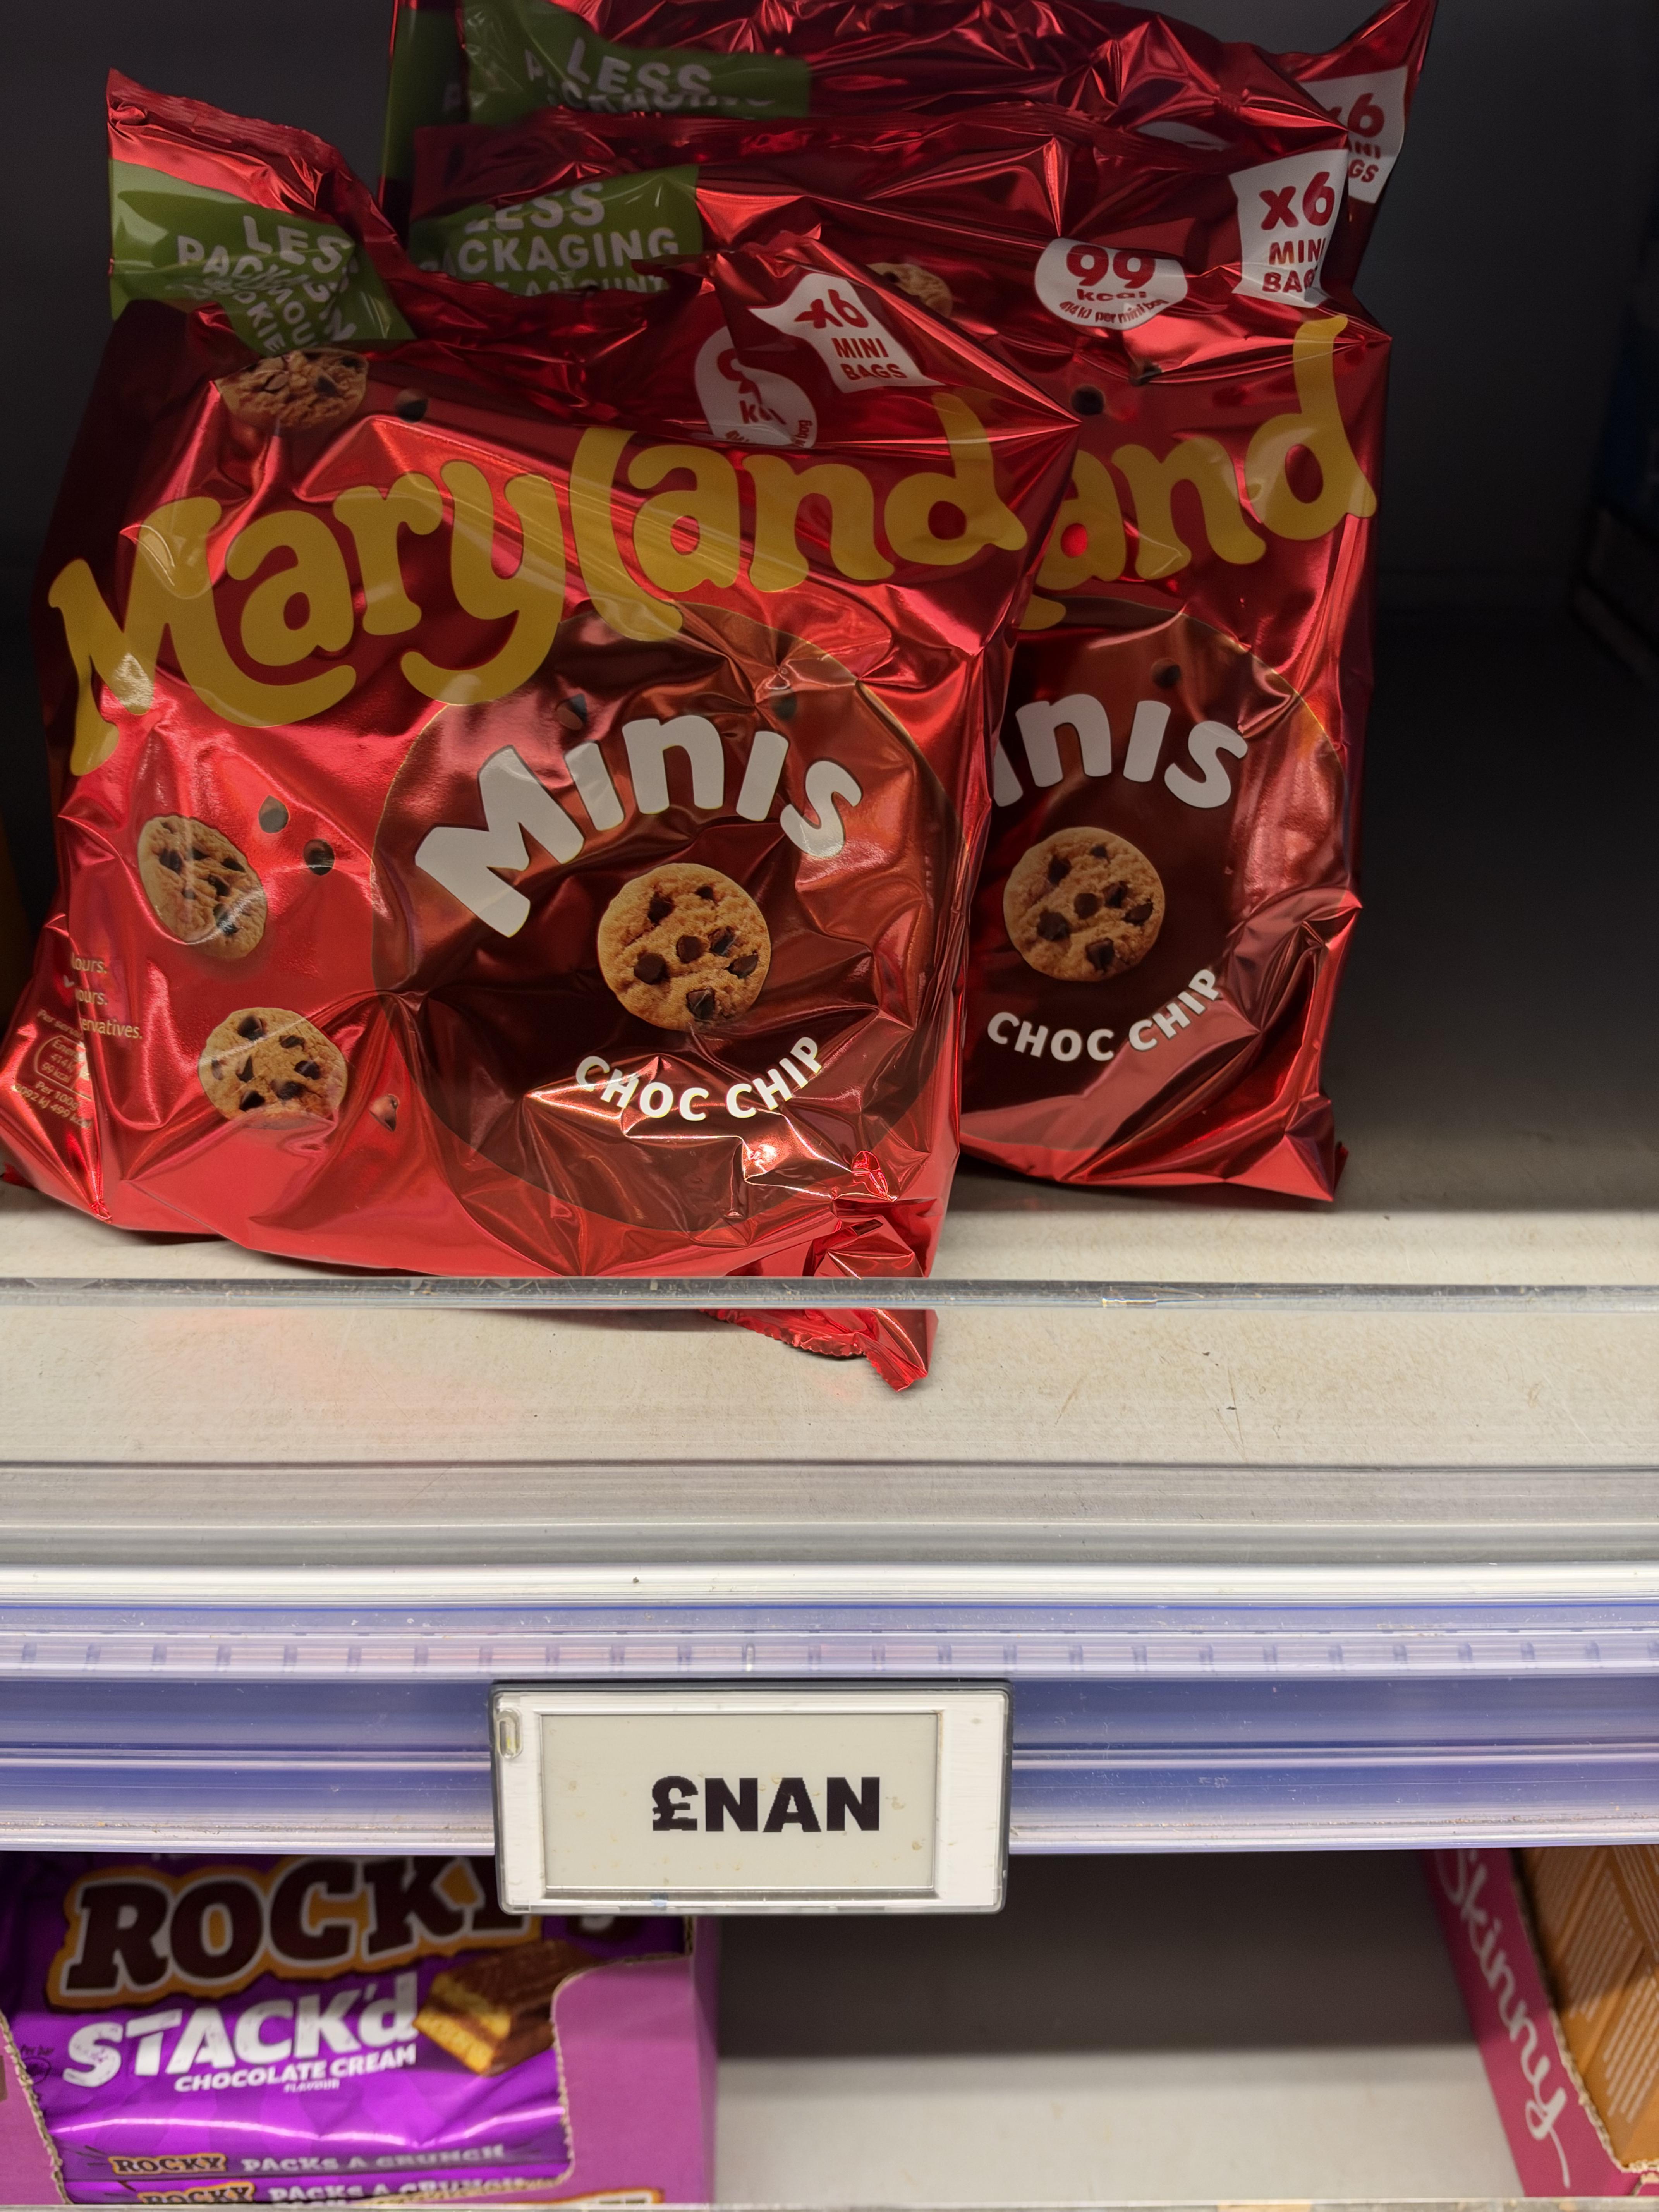
Is This A Good Price For Cookies

Is This A Good Price For Cookies
When the pricing system returns NaN instead of an actual number, so now these cookies cost "Not a Number" pounds. Classic JavaScript moment right there. Someone probably tried to do math on undefined , divided by zero, or parsed a string that definitely wasn't a number. The best part? The label printed successfully and nobody caught it before it hit the shelf. Production bugs hitting different when they're literally on display in a grocery store. Somewhere, a developer is getting a Slack message with a photo attached and their stomach just dropped. Fun fact: NaN is technically a number type in JavaScript, but typeof NaN === "number" returns true. Because of course it does.

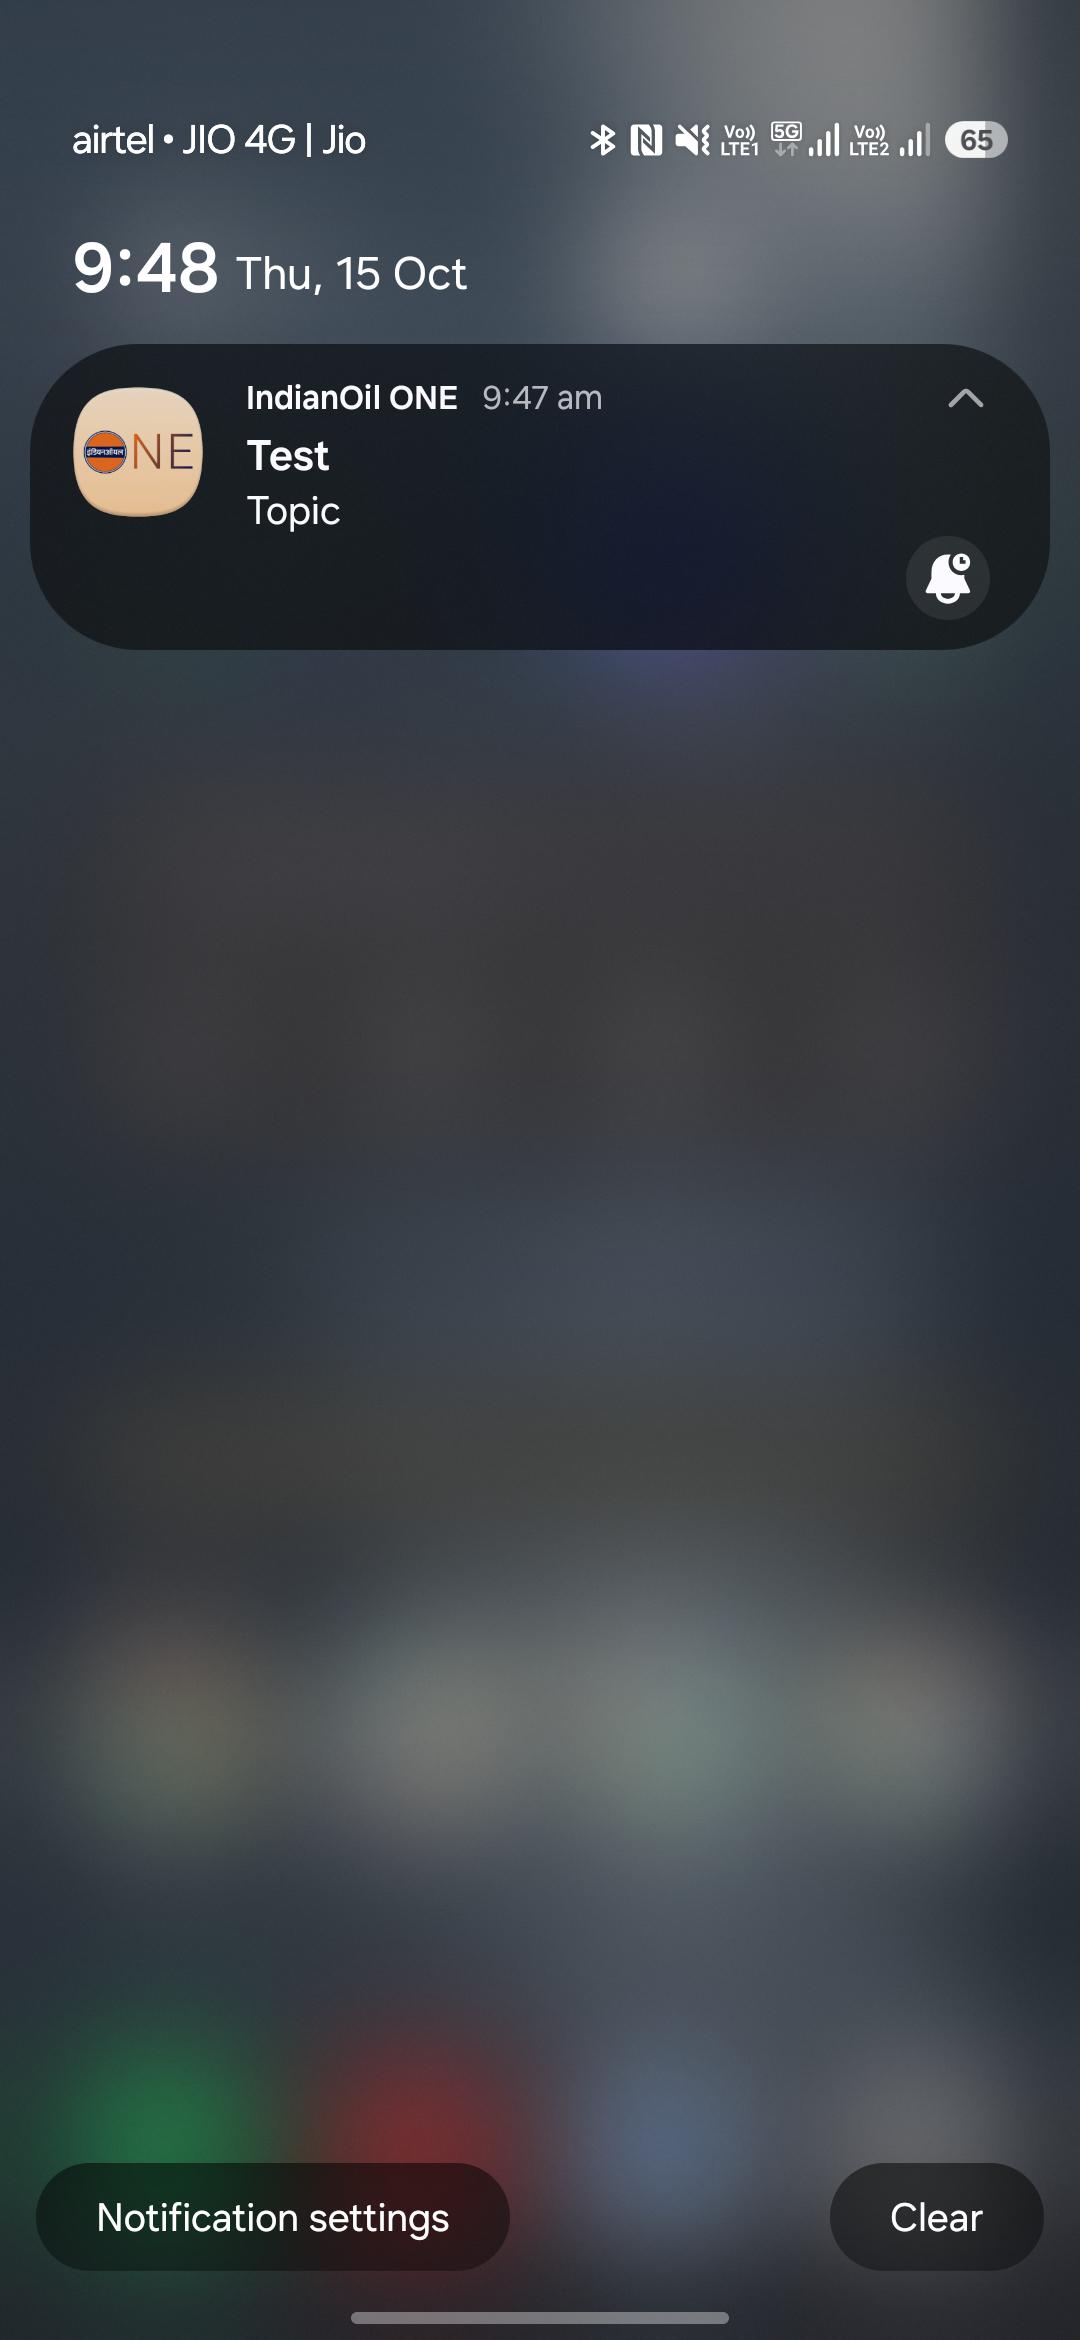
When Testing Happens In Production

When Testing Happens In Production
Nothing screams "we have a robust QA process" quite like a major corporation sending push notifications titled "Test" with the body "Topic" to millions of users. IndianOil really said "staging environment? never heard of her" and just yeeted their test notification straight to production at 9:47 AM on a Thursday morning. Somewhere, a developer is frantically updating their resume while their manager is discovering what "rollback" means. The best part? This notification is now immortalized on thousands of phones, serving as a permanent reminder that test environments are apparently optional in enterprise software development. Pro tip: If your notification says "Test" and "Topic," it's probably not ready for your entire user base. But hey, you get instant feedback from millions of testers simultaneously—that's just efficient DevOps, right?

Bug Pushed Coming To Take Down Prod

Bug Pushed Coming To Take Down Prod
You know that feeling when you hit merge on a PR at 4:58 PM on Friday and suddenly realize you forgot to test that one edge case? That bug is now manifesting as a sentient entity with a singular mission: complete and utter destruction of your production environment. The menacing energy radiating from this character perfectly captures that moment when you check the deployment pipeline and realize your "quick fix" is about to become everyone's problem. Your phone's about to start buzzing with PagerDuty alerts, your boss is going to ask "what happened," and you'll be frantically typing git revert commands while sweating profusely. The bug doesn't care about your test coverage, your code reviews, or your CI/CD pipeline. It's coming, and prod is its target.

CafePress It Works On My Machine Mugs 11 oz (325 ml) Ceramic Coffee Mug

CafePress It Works On My Machine Mugs 11 oz (325 ml) Ceramic Coffee Mug
Dimensions: Our standard size 11 oz mug measures 3.75" tall x 3" in diameter · Color Coordinate: Mix and match your hot cocoa mugs with your decor by choosing from the following interior and handle c…

Deploying To Prod On A Friday

Deploying To Prod On A Friday
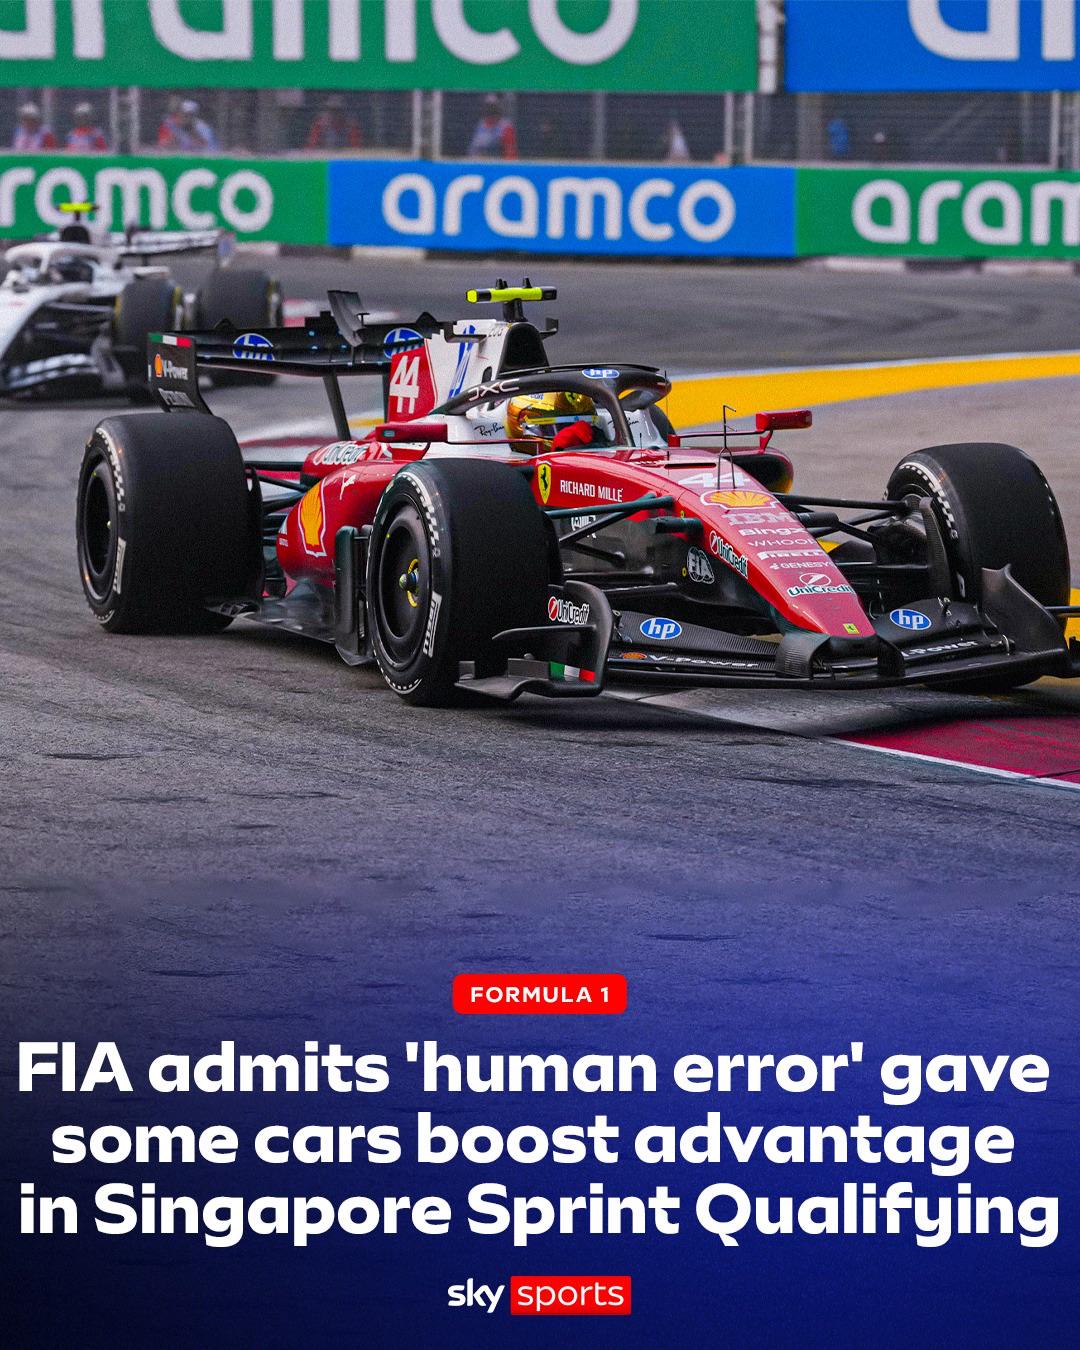
You know that feeling when you push code to production at 4:55 PM on Friday and suddenly realize you just gave some features an unfair advantage while breaking others? That's basically what happened here. FIA (the racing governing body) admitted a "human error" gave certain cars a boost during qualifying – which is the software deployment equivalent of accidentally deploying untested code that somehow makes the checkout button work better for some users but crashes for others. The real kicker? Just like in production, you can't just rollback a qualifying session. The damage is done, the race results are affected, and now someone's gotta write a postmortem explaining how they messed up in front of millions of people. At least when we deploy on Friday, only our on-call engineer and a few angry customers witness the chaos. These folks did it on international television. Remember kids: never deploy to prod on Friday unless you enjoy spending your weekend in a war room with a laptop and regret.

What Happens To John

What Happens To John
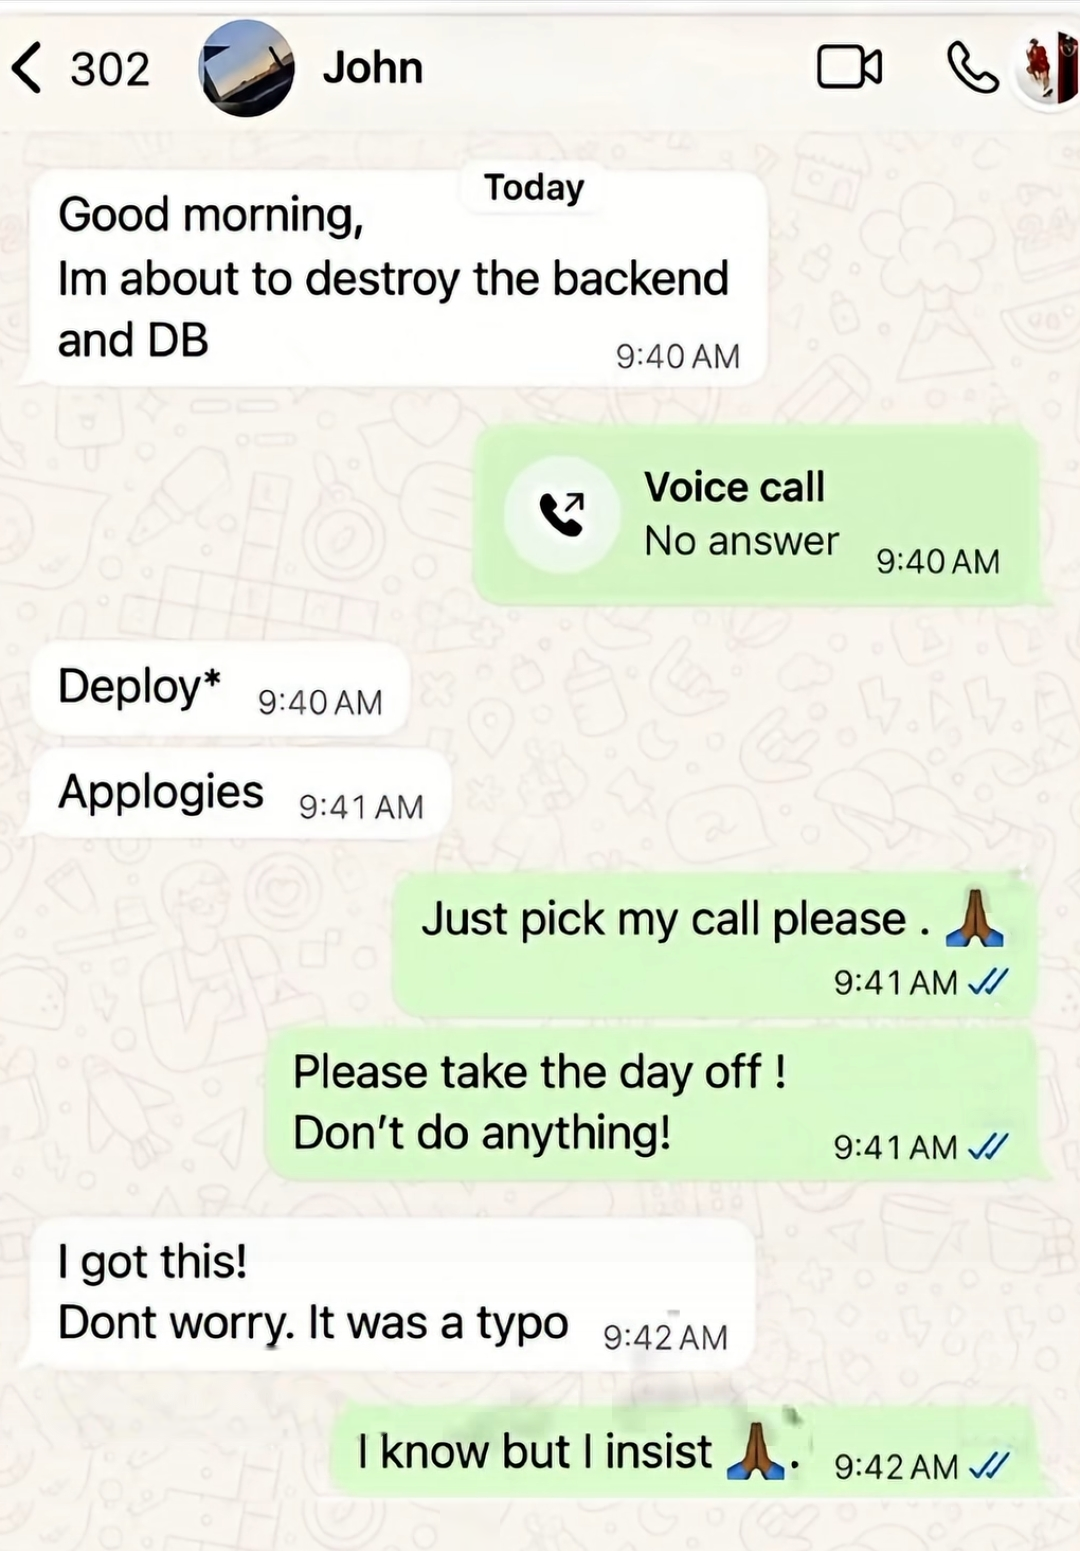
When your junior dev casually announces they're about to nuke production at 9:40 AM on a Tuesday. The sheer panic that follows is palpable—immediate voice call that goes straight to voicemail (because of course it does), followed by "Deploy*" with an asterisk that screams "I ALREADY DID IT," then the world's fastest apology speedrun. The begging escalates beautifully: "Just pick my call please 🙏" then straight to "Please take the day off! Don't do anything!" which is basically the tech equivalent of "PUT THE GUN DOWN." And John, bless his heart, hits back with "It was a typo" like that somehow makes accidentally obliterating the database better. Narrator: It wasn't a typo. Pro tip: If someone says they're about to destroy your backend and DB, maybe have their deploy permissions revoked before they send the message. Just a thought.

Deploy In AI Agents Age

Deploy In AI Agents Age
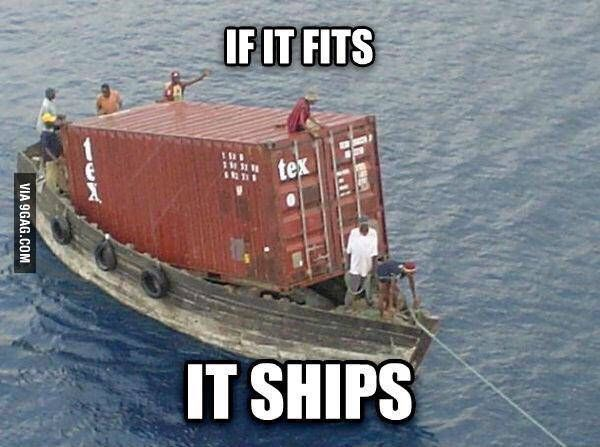
So we've gone from "move fast and break things" to "move fast and hope the AI-generated code doesn't sink the entire production environment." That shipping container balanced on a tiny wooden boat? That's your deployment strategy when you let AI agents write half your codebase and you're just praying it doesn't capsize in production. The boat's barely floating, there's like six people trying to keep this thing steady, and somehow it's still moving forward. Sound familiar? That's every startup right now with their "AI-first" approach—massive infrastructure sitting on the most questionable foundation, but hey, the investors are happy and it technically works. Ship it before anyone asks questions about load testing. The real kicker is we all know this boat is one wave away from disaster, but we're calling it "agile" and "innovative" instead of what it really is: a beautiful disaster waiting to happen. Welcome to 2024, where tech debt is measured in AI hallucinations per second.