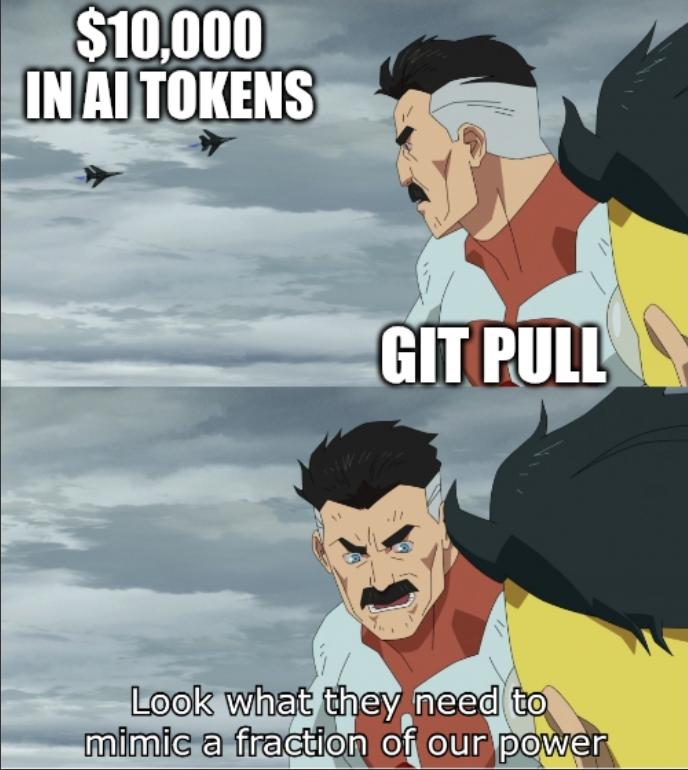
AI
 AWS
 Agile
 Algorithms
 Android
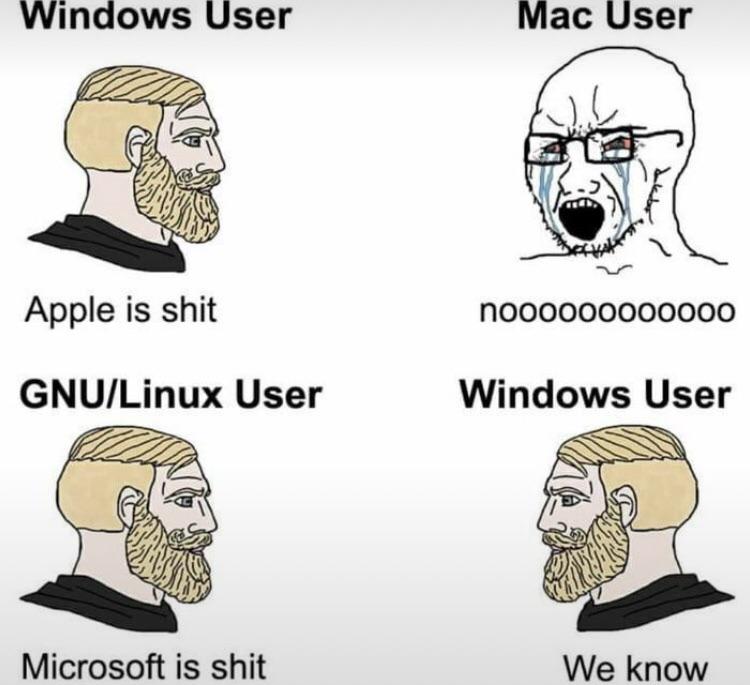
 Apple
 Azure
 Backend
 Bash
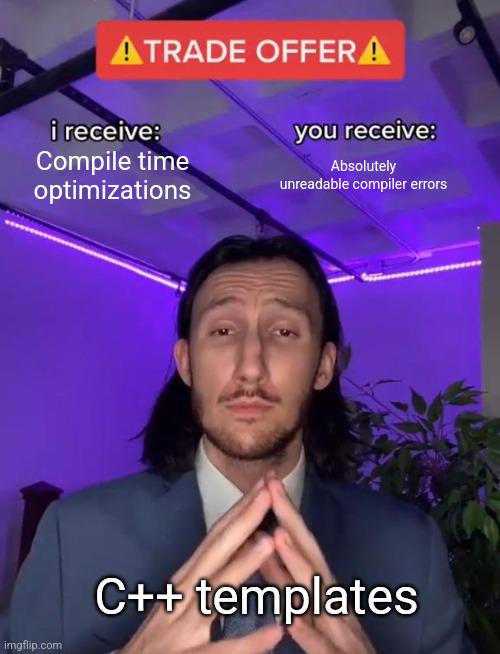
 C++
 Cloud
HTTP 418: I'm a teapot
The server identifies as a teapot now and is on a tea break, brb
HTTP 418: I'm a teapot
The server identifies as a teapot now and is on a tea break, brb
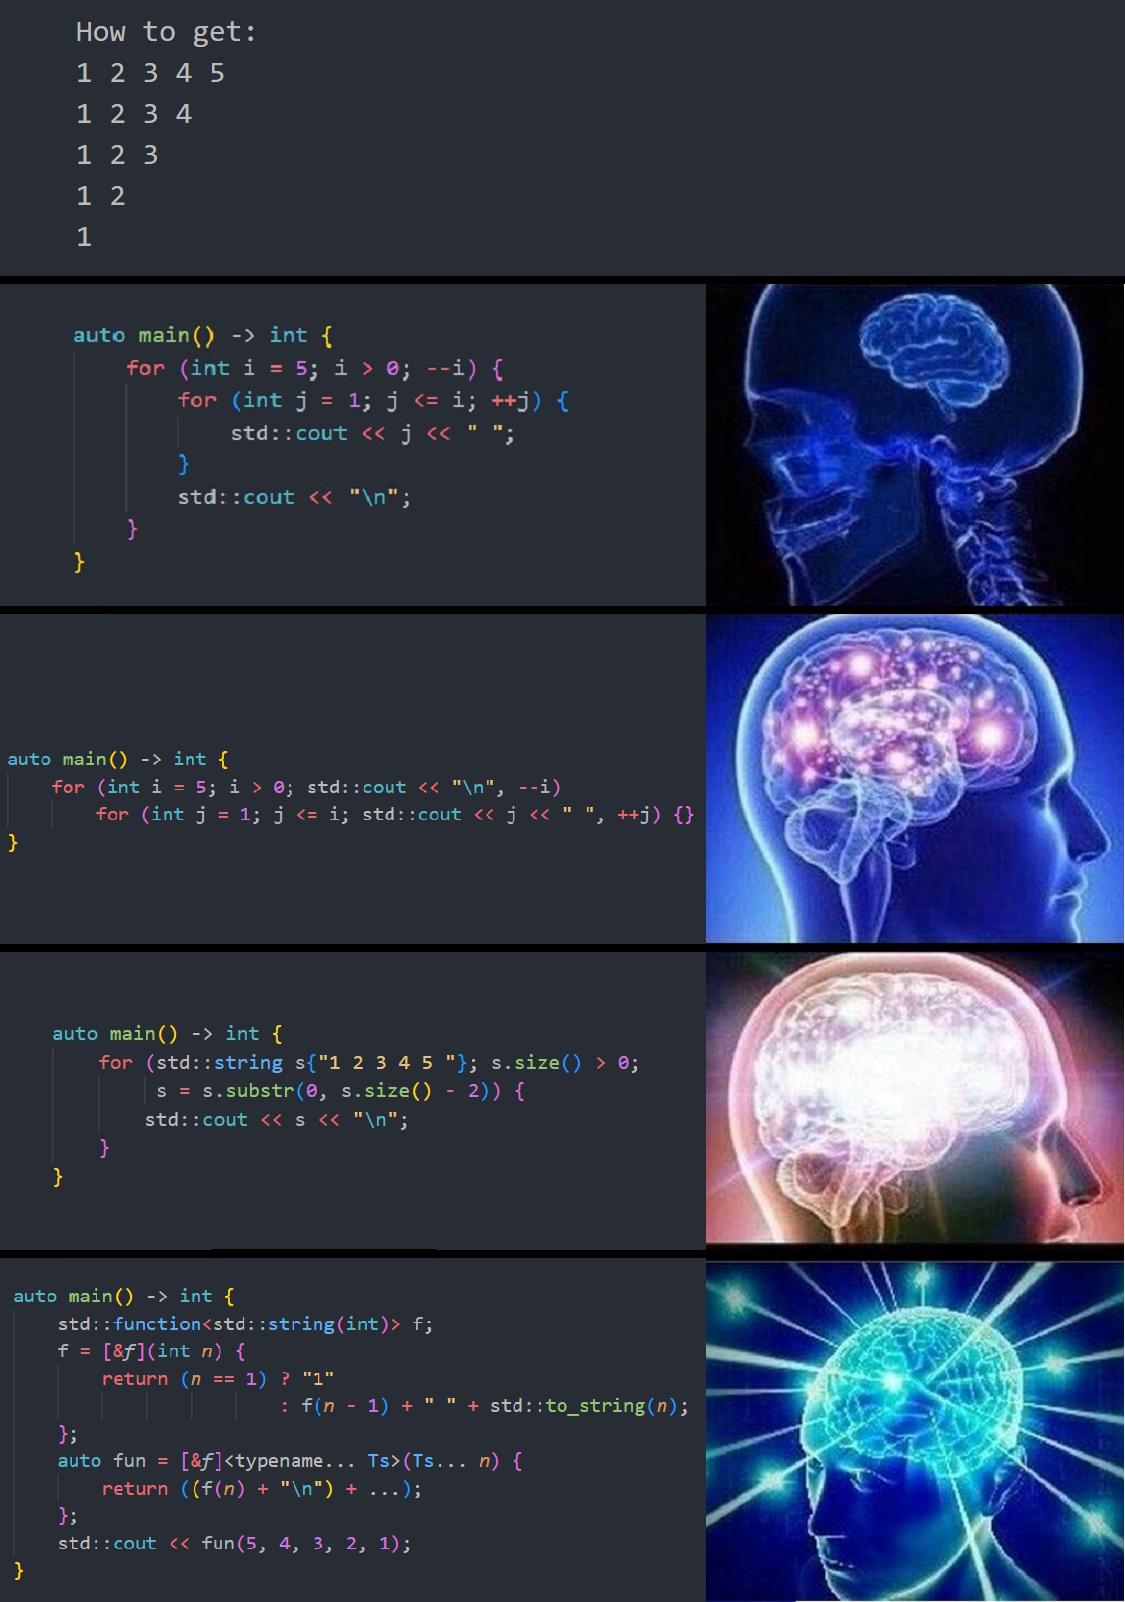
templates Memes

HTTP 418: I'm a teapot
The server identifies as a teapot now and is on a tea break, brb
HTTP 418: I'm a teapot
The server identifies as a teapot now and is on a tea break, brb