ci/cd Memes

Vibing Ain't Easy

Vibing Ain't Easy
You know that moment when you're trying to save a few bucks on your CI/CD pipeline by using the free tier of some random build agent, and it starts timing out, crashing mid-deployment, or just straight-up refusing to compile your perfectly valid code? Yeah, suddenly that $50/month premium agent doesn't seem so expensive anymore. Nothing quite captures the pain of having to justify infrastructure costs to your manager after your bargain-basement solution nuked production at 2 PM on a Friday. The real kicker? The expensive agent was in your budget the whole time, but you wanted to be "cost-conscious" and now you're on a call explaining why the website is down. Pro tip: some corners aren't worth cutting, especially when they're holding up your entire deployment pipeline.

Has Anyone Seen My Run

Has Anyone Seen My Run
You push your code, trigger a GitHub Actions workflow, and then spend the next 20 minutes frantically refreshing the Actions tab trying to find which run corresponds to your commit. Was it the one from 3 minutes ago? Or 4? Why are there 47 runs in the queue and none of them have your commit message visible? The UI just shows you a wall of yellow dots and you're standing there like John Travolta in Pulp Fiction, completely lost in your own repository. Bonus points if you're working on a team repo where everyone's pushing at the same time and the Actions tab looks like a slot machine. Good luck finding your specific build failure in that chaos.

How Asking DevOps For Anything Feels Like

How Asking DevOps For Anything Feels Like
You know that moment when you need to deploy a simple feature or just want access to a staging environment? You approach DevOps with your humble request, and suddenly you're kissing the ring like you're asking The Godfather for a favor. The power dynamic is real. DevOps holds the keys to the kingdom—production access, CI/CD pipelines, Kubernetes clusters, AWS permissions. They control everything from your Docker containers to your deployment secrets. One wrong move and your entire pipeline could be down, so you better show some respect. The best part? You'll probably need to open a Jira ticket, wait for approval, attend three meetings, and sacrifice a rubber duck before they grant your request. But hey, at least they'll make you an offer you can't refuse... eventually.

Consistency Is Key

Consistency Is Key
You know you've achieved true DevOps excellence when your production environment is just as broken as your local machine. The classic "works on my machine" problem, except in reverse—nothing works anywhere, perfectly synchronized chaos across all environments. That stormtrooper confidently marching forward with terrible aim? That's your code making it to prod with the exact same bugs you've been debugging for weeks. At least your CI/CD pipeline is working flawlessly—flawlessly deploying garbage. The real kicker is when QA signs off because "it matches the dev environment behavior." Technically not a regression if it was always broken, right?

What Did Our Database Engineer Mean By This

What Did Our Database Engineer Mean By This
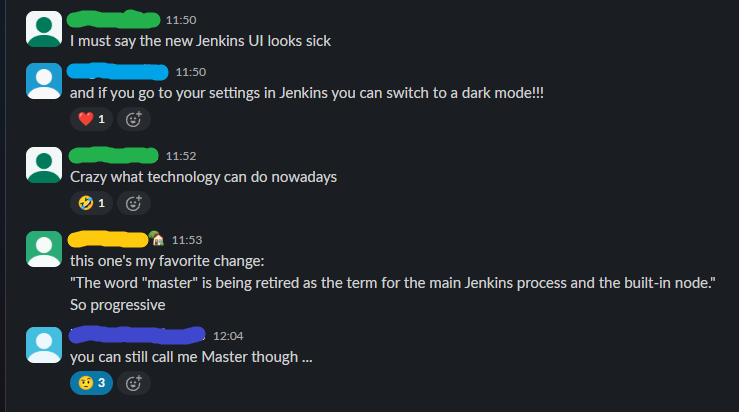
Your database engineer just casually dropped the most UNHINGED hot take in the middle of a Jenkins UI discussion. While everyone's debating dark mode and celebrating Jenkins finally joining us in 2023, this absolute legend swoops in with "you can still call me Master though..." after someone mentioned the main process being renamed from "master" to something more inclusive. The sheer AUDACITY of making that joke in a professional Slack channel is *chef's kiss*. Like sir, we're talking about CI/CD pipelines and you just turned this into a comedy roast session. The timing? Impeccable. The delivery? Flawless. The HR department reading this later? Probably having a mild panic attack. This is peak developer humor where someone takes a completely reasonable technical change and turns it into their personal stand-up routine. The real question is: what does being a database engineer have to do with this level of chaos? Absolutely nothing, which makes it even funnier.

Is 'Vibe Coding' The Root Of All Evil? Xd

Is 'Vibe Coding' The Root Of All Evil? Xd
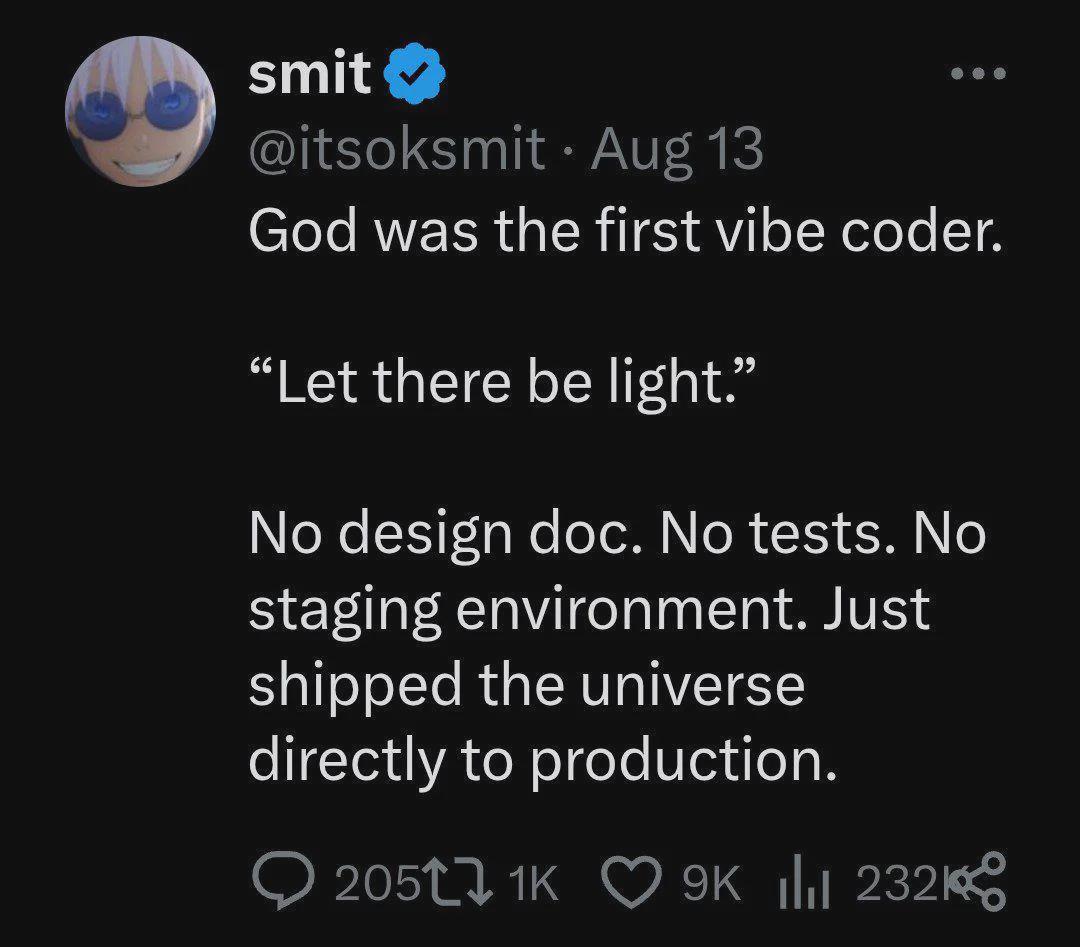
So apparently God just said "screw it" and yeeted the entire universe straight to prod without a single unit test, design document, or staging environment. Just pure vibes and divine intuition. No code reviews, no CI/CD pipeline, no rollback strategy—just raw creation energy and a single command: "Let there be light." The ultimate cowboy coder move. Zero documentation, infinite scope creep (literally created everything), and somehow it still works. Meanwhile, us mortals need three sprint planning meetings just to add a button to a form. The theological implications of deploying directly to production without even a smoke test are honestly terrifying. No wonder there are so many bugs in the system—have you seen the platypus? That's clearly a merge conflict that made it to prod. Vibe coding: when your gut feeling is literally omniscient, so QA is optional.

EMEET C960 1080P Webcam with Microphone, 2 Mics, 90° FOV, Computer Camera

EMEET C960 1080P Webcam with Microphone, 2 Mics, 90° FOV, Computer Camera
1080P Webcam with Cover for Video Calls - EMEET computer webcam provides design and Optimization for professional video streaming. Realistic 1920 x 1080p video, 5-layer anti-glare lens, providing smo…

Never Seen It This Bad

Never Seen It This Bad
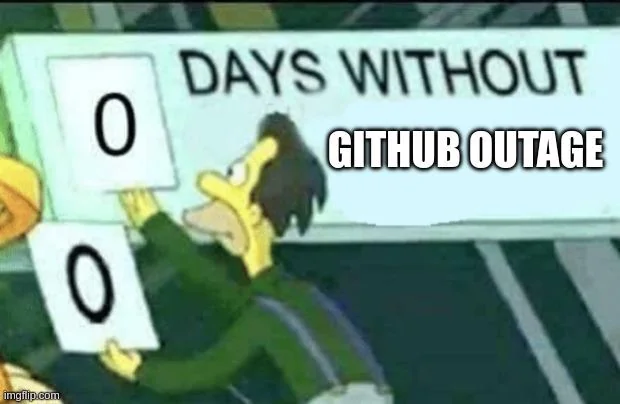
When GitHub goes down for even a microsecond, the entire software development industry collectively gasps. Zero days without an outage? That's not a record—that's a Tuesday. The dependency on GitHub is so absolute that developers literally cannot function without it. No pushing code, no pulling repos, no checking that one Stack Overflow answer you copied six months ago from a GitHub gist. It's like watching a factory worker stare at a broken conveyor belt, except the conveyor belt hosts 100 million repositories and your entire CI/CD pipeline. The panic is real because GitHub isn't just version control anymore—it's your portfolio, your deployment trigger, your documentation host, your package registry, and apparently your entire personality as a developer. When it goes down, you're forced to do the unthinkable: actually talk to your coworkers or pretend to understand GitLab.

The Only Bug Free Deployment Strategy

The Only Bug Free Deployment Strategy
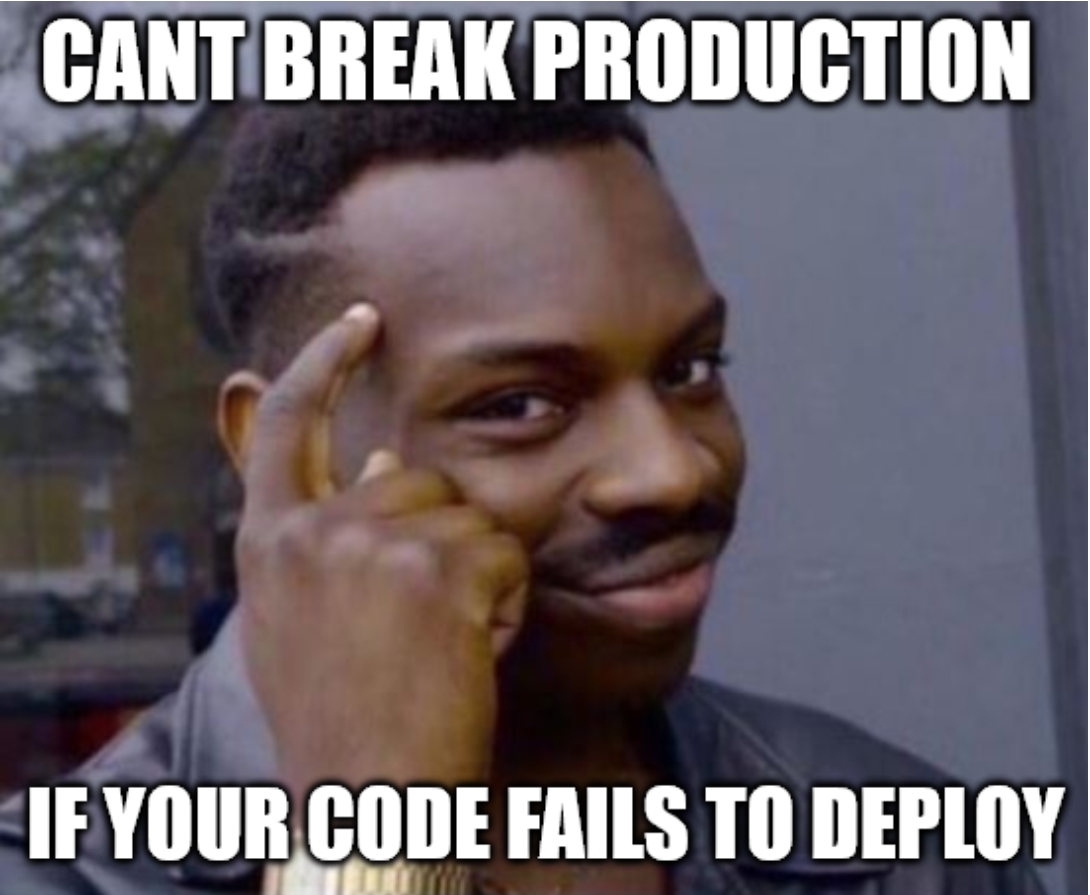
Genius-level DevOps right here. If your deployment pipeline is so catastrophically broken that the code never makes it to production, congratulations—you've achieved zero production bugs. It's basically the enterprise version of "works on my machine" taken to its logical extreme. Can't have runtime errors if there's nothing running. Can't have users complaining about bugs if they can't access the application. This is what peak performance looks like.

Build Failed? Just Blame The Other Guy

Build Failed? Just Blame The Other Guy
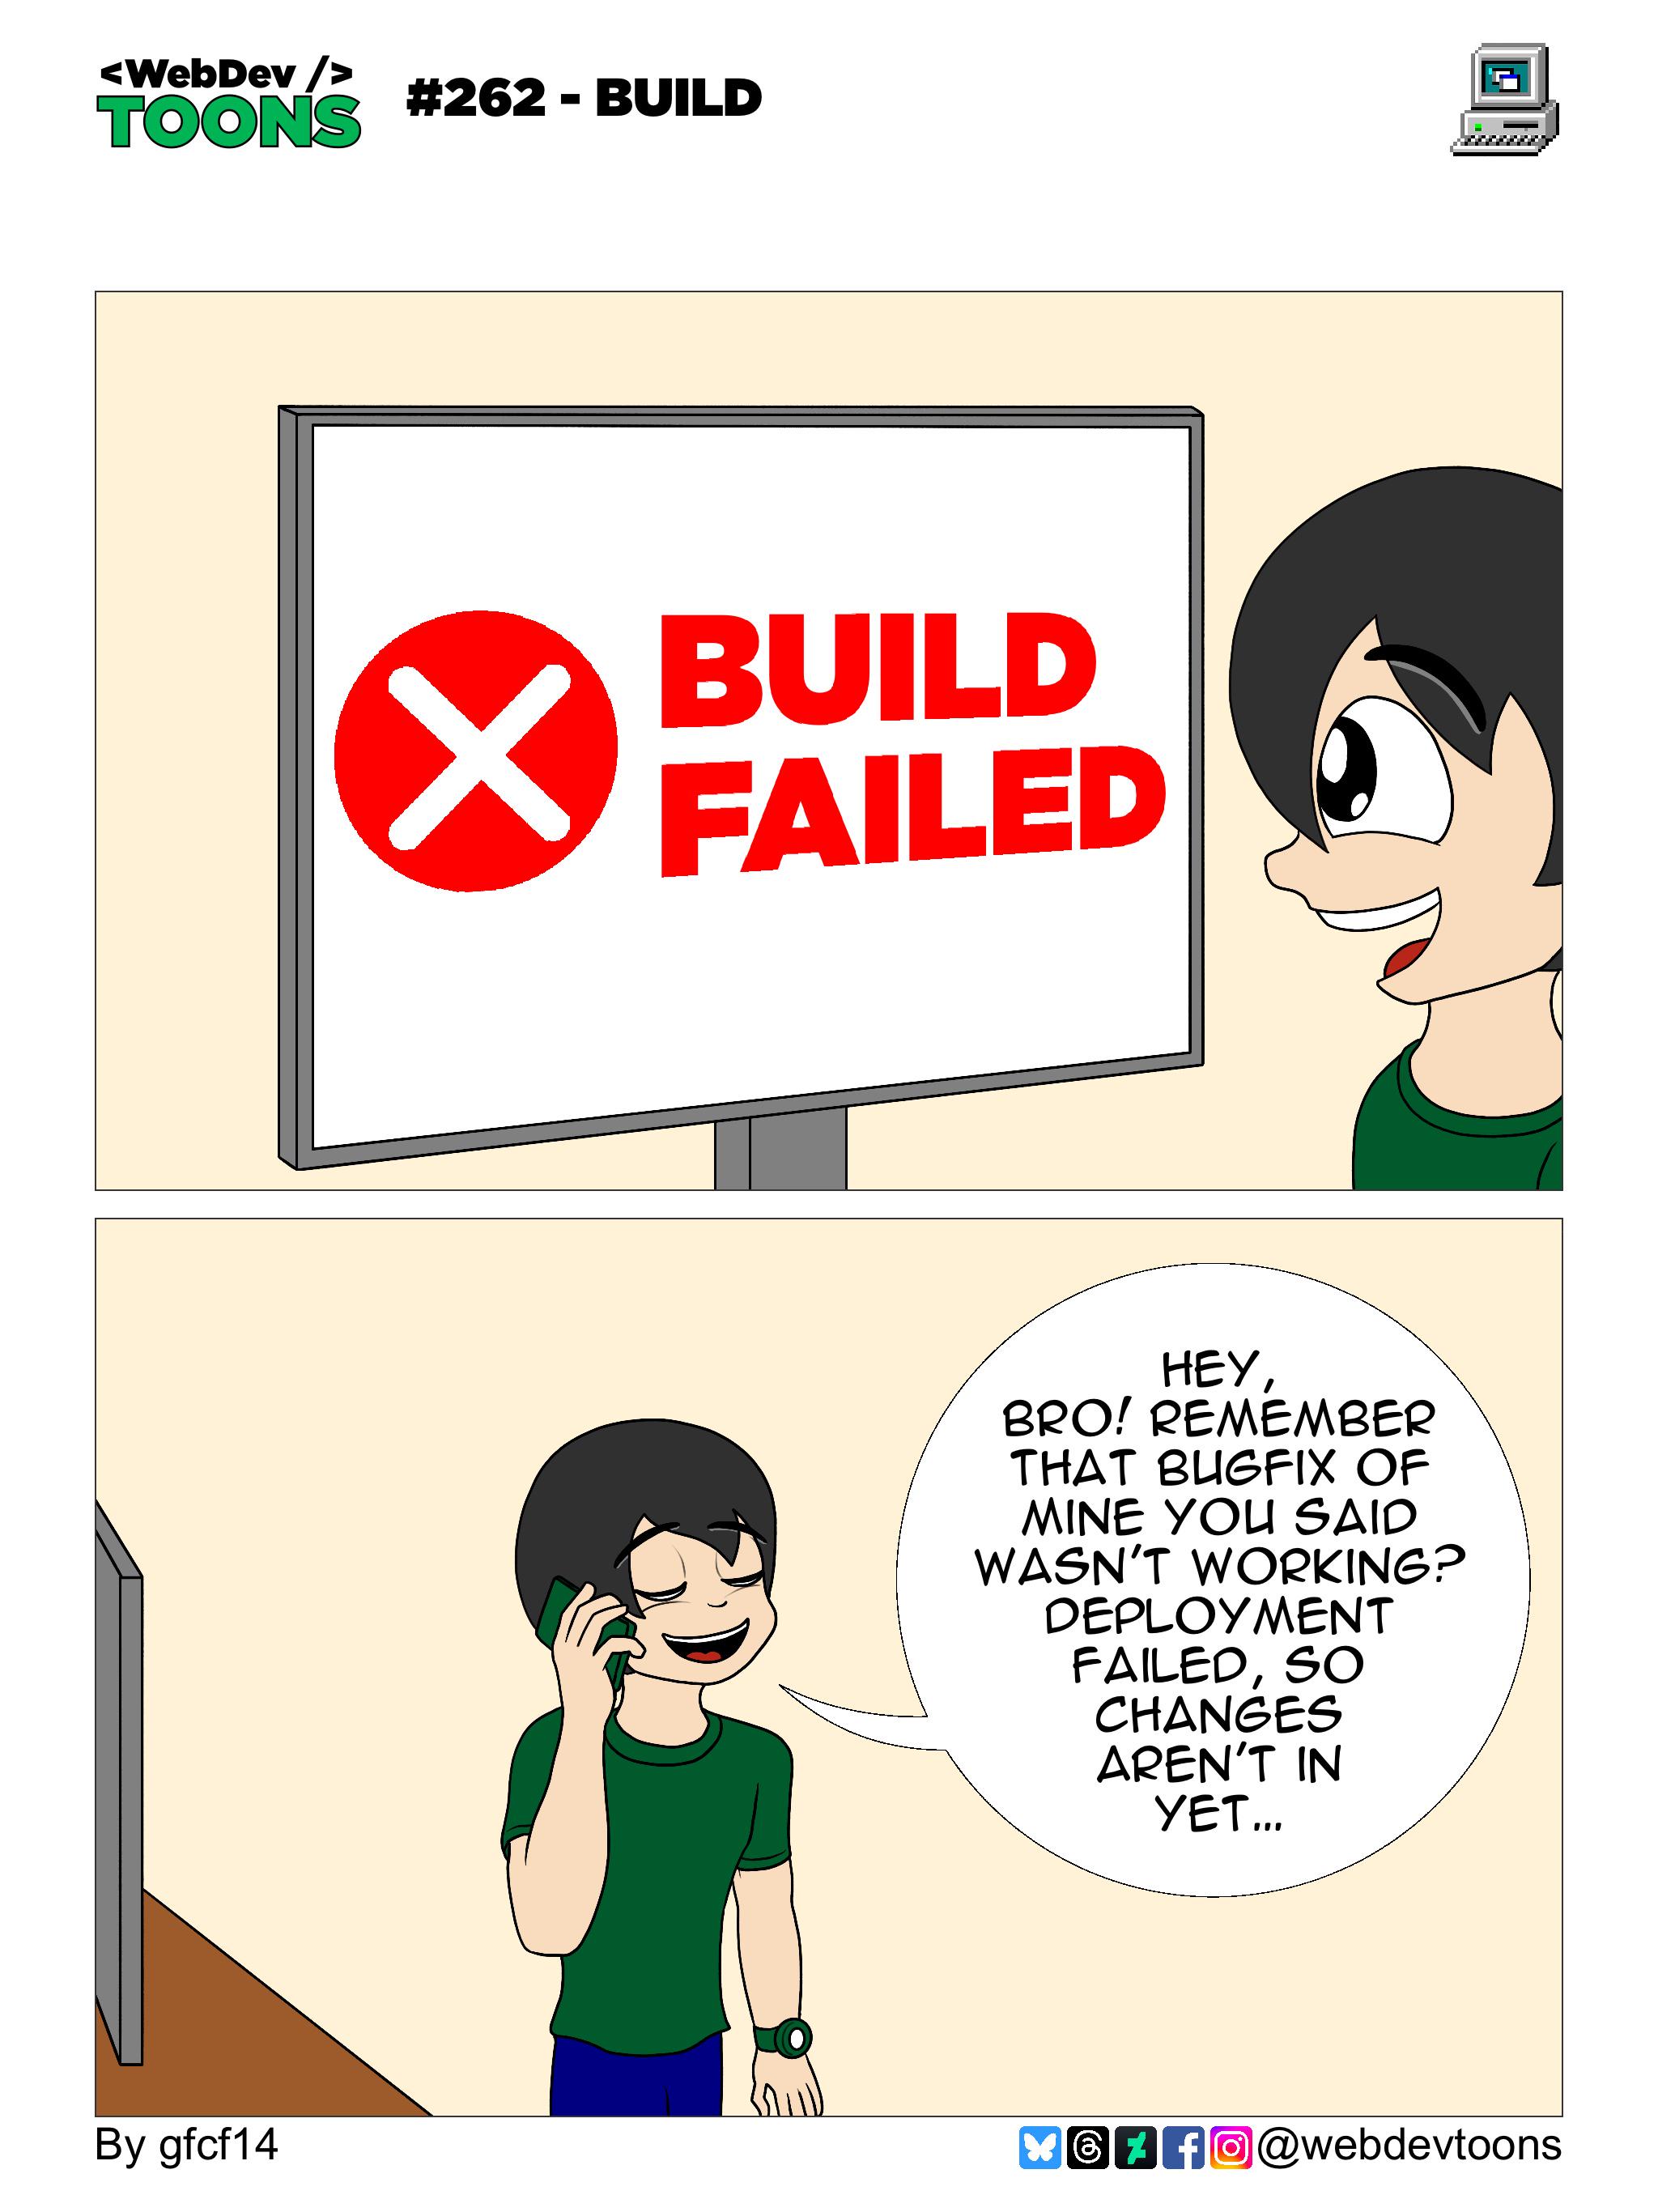
The classic developer deflection technique in action. Your build fails spectacularly, and instead of checking your own code, you immediately call up your teammate to remind them about their "broken" bugfix that wasn't even deployed yet. The deployment hasn't even happened, so their changes are literally sitting in a branch somewhere, completely innocent. It's the programming equivalent of blaming the person who hasn't even entered the room yet for the mess on the floor. The build failed because of YOUR code that's currently running, but sure, let's preemptively blame the guy whose changes are still in code review. Classic CI/CD panic response: when in doubt, point fingers at anything but your own commit from 5 minutes ago.

Approval Cluster Down

Approval Cluster Down
You've got your hotfix ready, your release PR is pristine, the CI/CD pipeline is green, and production is literally on fire. But can you deploy? Nope. Because your entire approval cluster has achieved 100% uptime... at the beach. All three senior devs decided to take PTO at the exact same time, leaving your urgent release in a state of perpetual limbo. It's like having a perfectly functioning Kubernetes cluster with zero replicas—technically operational, practically useless. The best part? Your PR will sit there aging like fine wine while you watch the Slack notifications pile up from stakeholders asking "when will this be fixed?" Welcome to the distributed systems problem nobody talks about: single points of failure in the human approval layer.

SunFounder Ultimate Starter Kit Compatible with Arduino UNO IDE Scratch, 3 in 1 IoT/Smart Car/Basic Kit with Online Tutorials, Video Courses, 192 Items, 87 Projects, Suitable for Age 8+ Beginners

SunFounder Ultimate Starter Kit Compatible with Arduino UNO IDE Scratch, 3 in 1 IoT/Smart Car/Basic Kit with Online Tutorials, Video Courses, 192 Items, 87 Projects, Suitable for Age 8+ Beginners
Expert-Designed Courses: Teaming up with Circuit Basics, SunFounder 3-in-1 Starter Kit offers comprehensive videos and online tutorials for well-rounded learning. Suitable for age 8+ beginners. · Com…

Absolute Cinema

Absolute Cinema
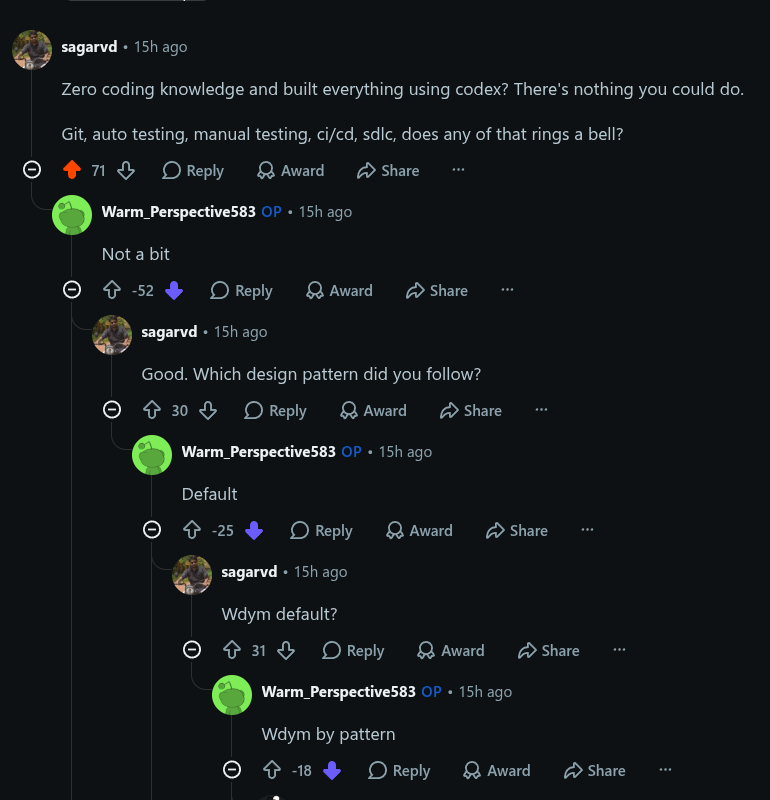
Someone built their entire project using Codex (GitHub Copilot's predecessor AI) with zero actual coding knowledge. When questioned about basic dev practices like Git, testing, CI/CD, or SDLC, they respond with "Not a bit." The follow-up is pure gold. "Which design pattern did you follow?" "Default." "What do you mean default?" "Whatever the pattern is called by default." This is the software engineering equivalent of someone building a house by asking an AI to describe each step while having no idea what a foundation is. The confidence is staggering. The technical debt is incalculable. The production incident is inevitable.

Clicking The Re Run Button Is Easier

Clicking The Re Run Button Is Easier
You're telling me I'm supposed to actually investigate why my integration tests are flaky instead of just smashing that re-run button until the CI gods smile upon me? That's rich. Look, we all know those tests are failing because of some race condition, network timeout, or cosmic ray hitting the server at just the wrong millisecond. But do I have time to dig through logs and fix the root cause? Nope. I've got 47 Jira tickets and a sprint review in two hours. The "best practices" guide can preach all it wants about proper test isolation and deterministic behavior, but we're out here in the trenches where deadlines matter more than dignity. If it passes on the fifth try, that's a green checkmark in my book. Ship it. The real test is production anyway.