AI
 AWS
 Agile
 Algorithms
 Android
 Apple
 Azure
 Backend
 Bash
 C++
 Cloud
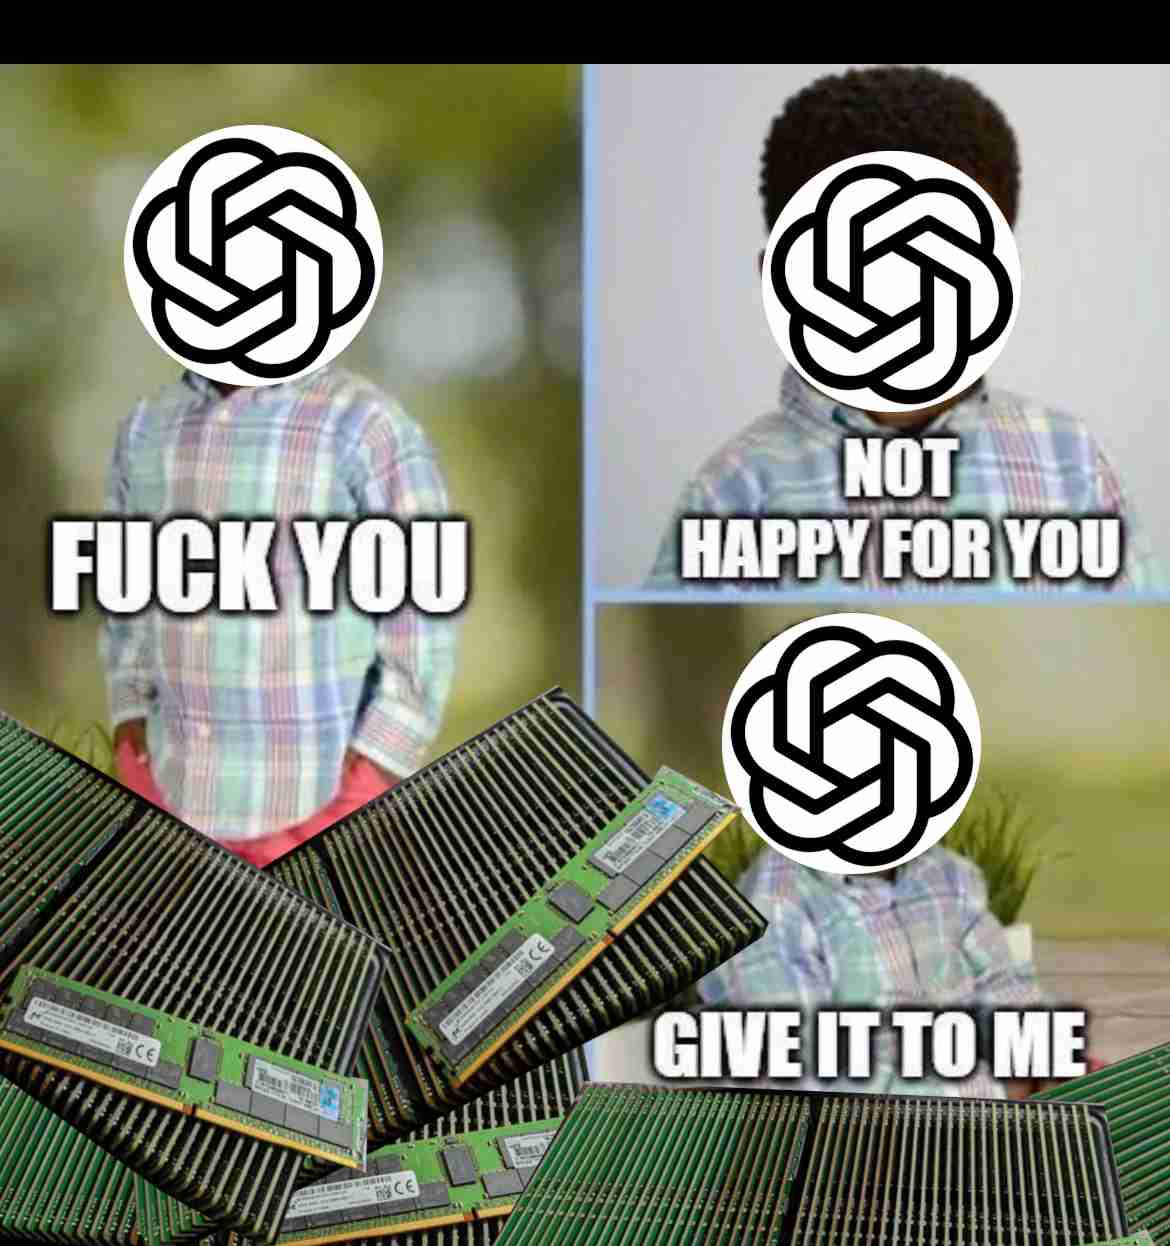
ChatGPT casually suggesting you run its latest AI model locally on your potato laptop is comedy gold. You're sitting there with your 8GB of RAM, barely keeping Chrome and VS Code alive, and this absolute menace wants you to download a 70B parameter model that requires more VRAM than your entire system has memory.
The three stages of grief are beautifully captured here: denial ("FUCK YOU"), bargaining ("NOT HAPPY FOR YOU"), and pure desperation ("GIVE IT TO ME"). Because deep down, you know you're about to turn your machine into a space heater just to run inference at 0.5 tokens per second.
Fun fact: Those RAM sticks in the image look like server-grade ECC memory, probably 32GB or 64GB each. Meanwhile, you're out here with single-channel DDR4 wondering why your local LLM keeps OOM-ing. The gap between AI requirements and developer hardware has never been more painful.