data science Memes

Decision Trees Before They're Harvested

Decision Trees Before They're Harvested
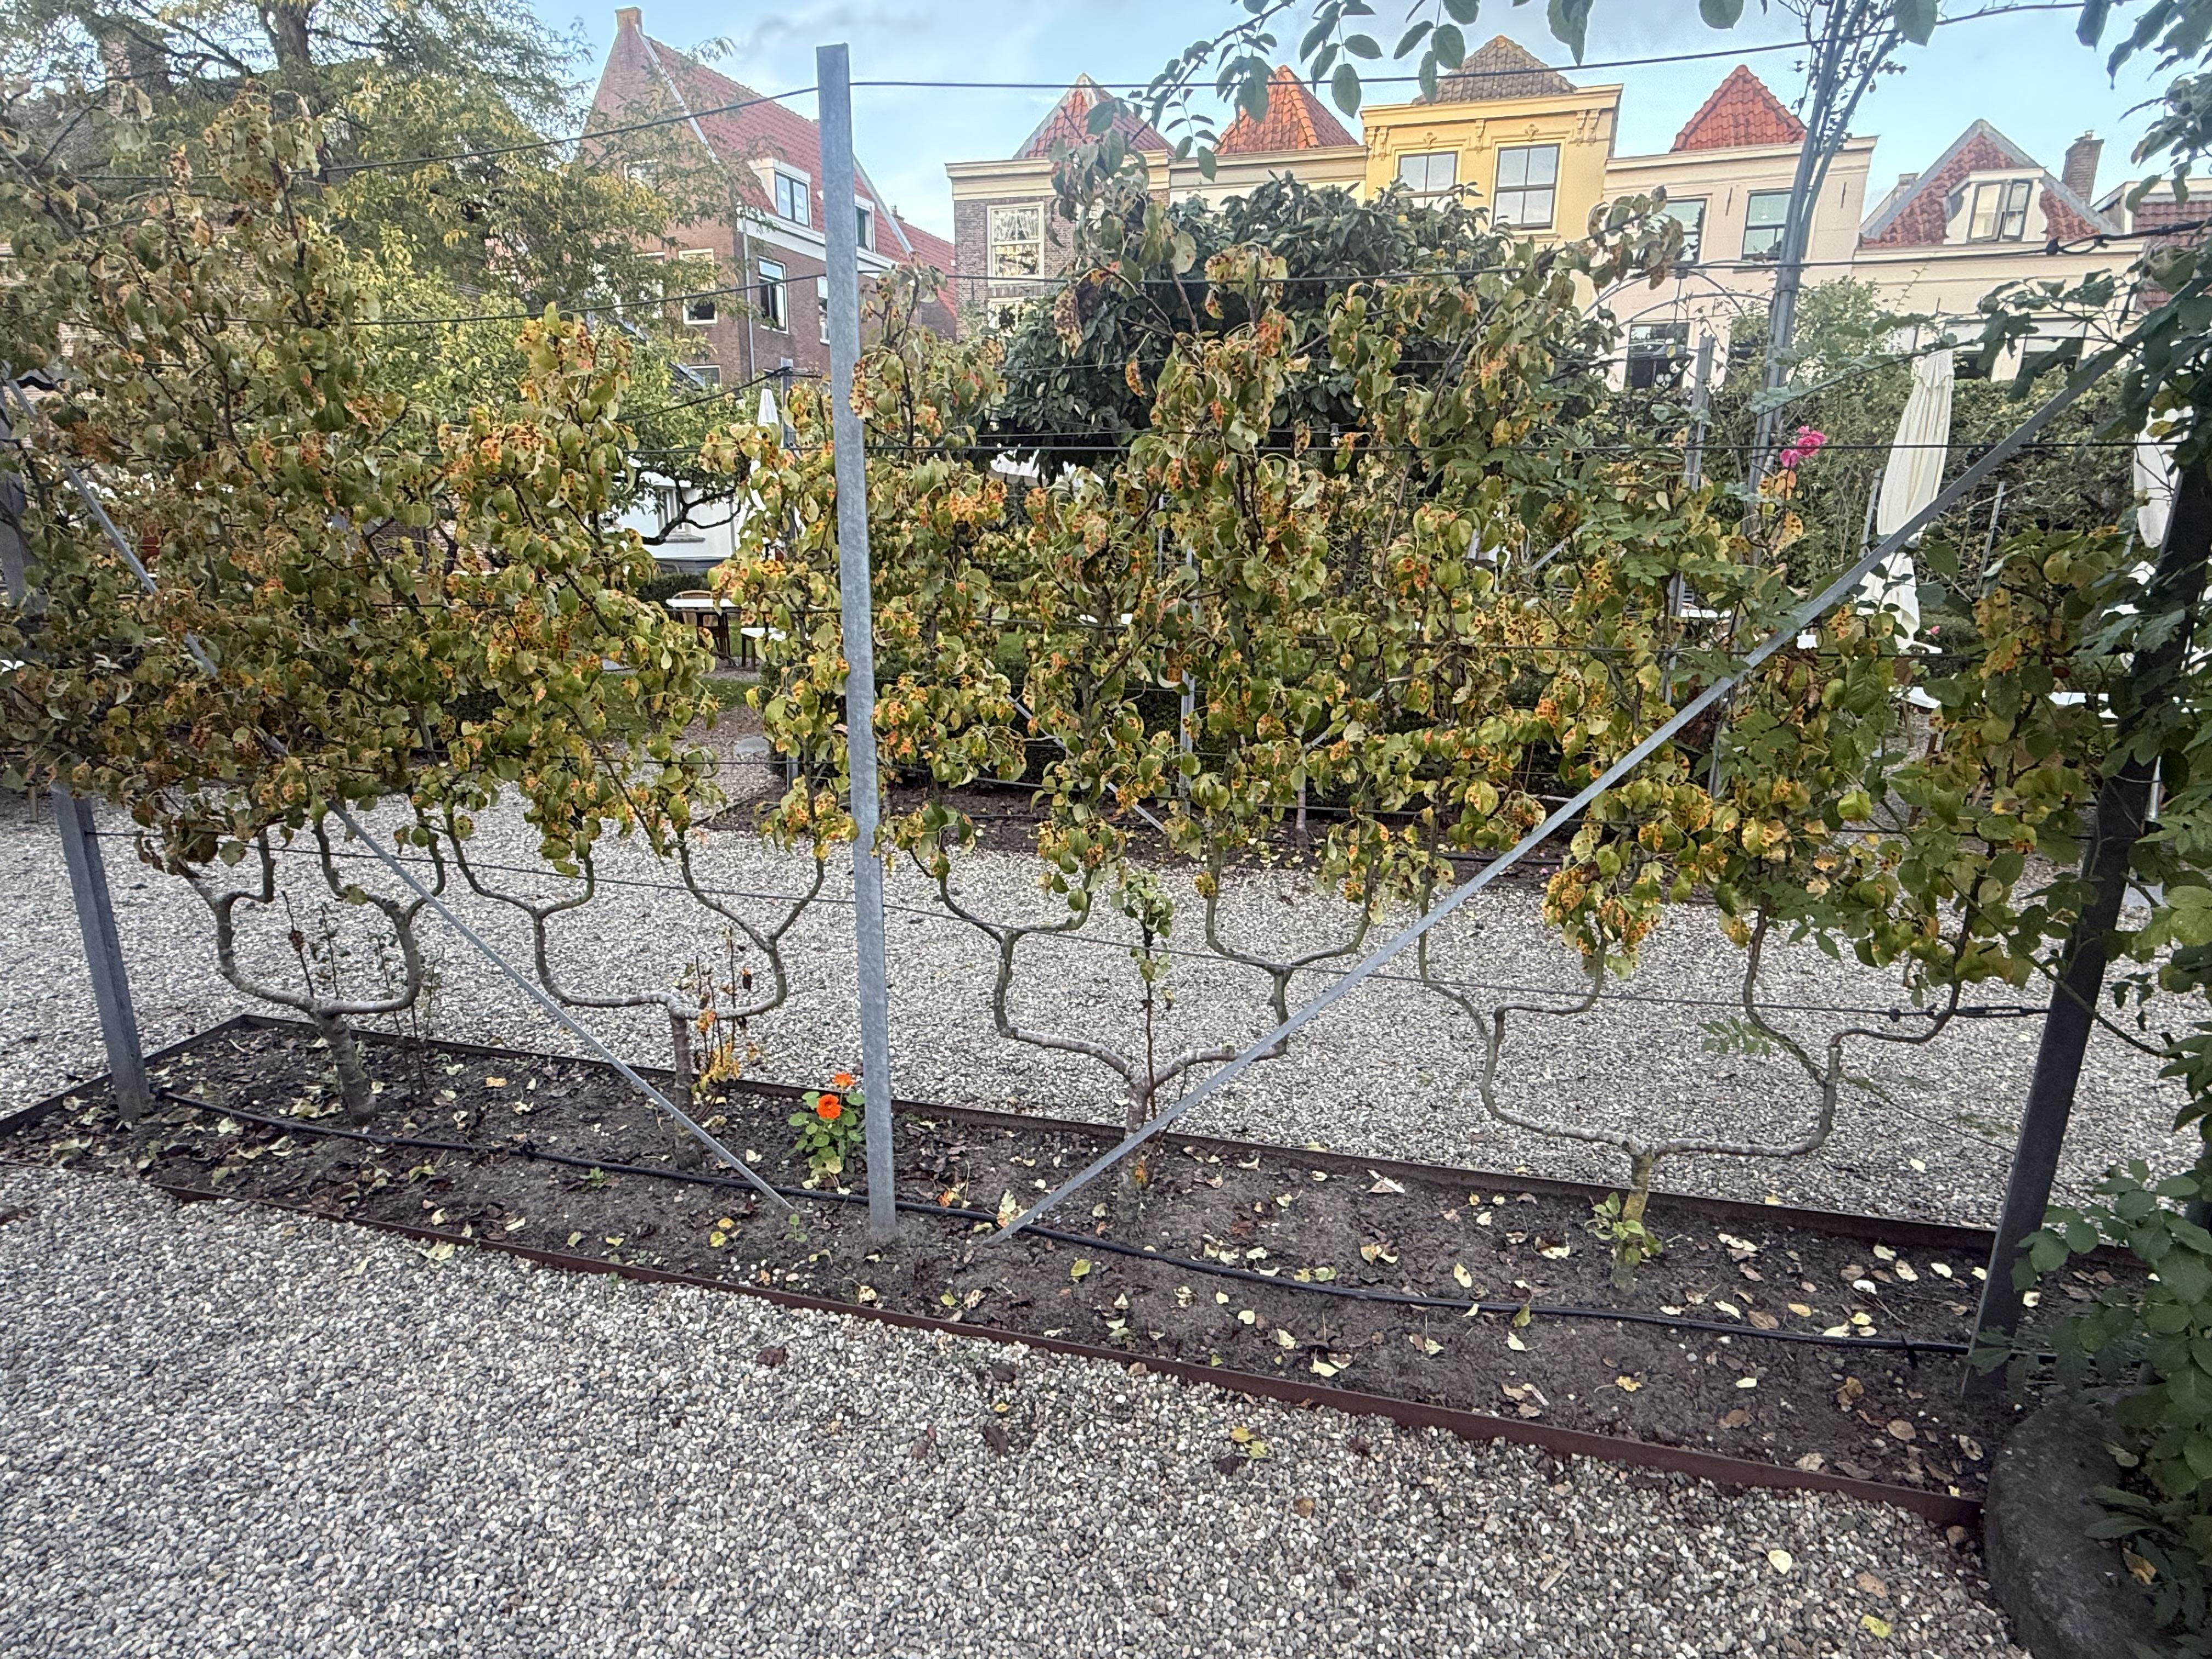
Someone took the term "decision tree" way too literally and now we have actual trees trained to grow in branching patterns. These are literally decision trees in their natural habitat, carefully pruned into binary splits before data scientists harvest them for their machine learning models. Each branch represents a different classification path, and somewhere a random forest is just a collection of these bad boys. The training data? Probably just sunlight and water with a 70/30 split.

Do You Pronounce Data As Data Or Data

Do You Pronounce Data As Data Or Data
Oh great, Sophia just HAD to start World War III in the tech community by asking the most divisive question since tabs vs spaces. Is it "DAY-tuh" or "DAH-tuh"? Because apparently we don't have enough things to argue about in code reviews. And poor Liam over here having an existential crisis because his brain automatically read both versions differently and now he's questioning his entire reality. The best part? You literally cannot read the word "data" anymore without your brain doing BOTH pronunciations simultaneously, creating some kind of linguistic superposition that would make Schrödinger proud. Thanks for the mental torment, Sophia! 🙃

Why Are We Using R Again

Why Are We Using R Again
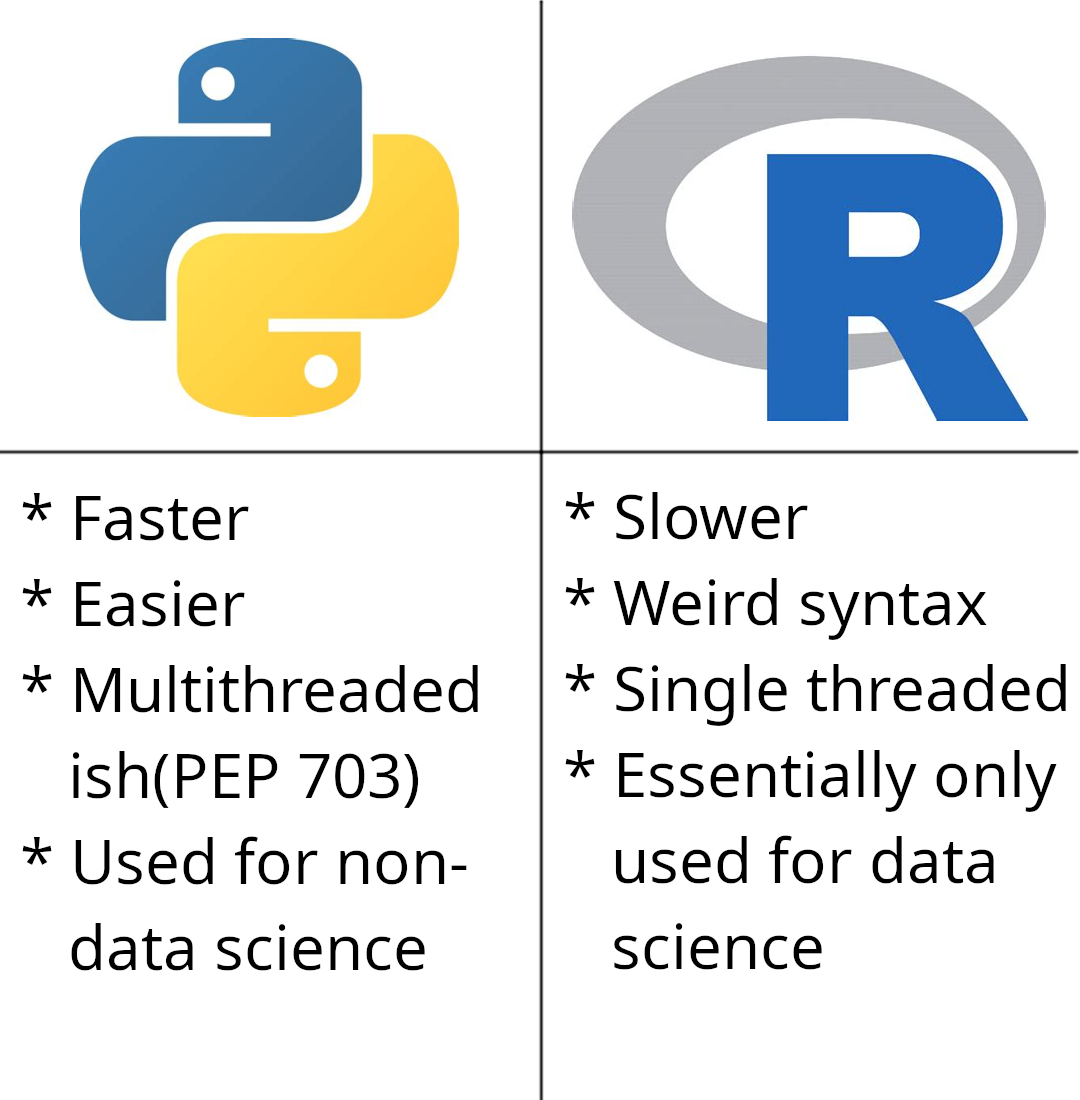
Python gets to be faster, easier, multithreaded, and useful beyond data science. R gets slower, weird syntax, single-threaded, and exists solely to make statisticians feel special. The "essentially only used for data science" part is doing some heavy lifting here. Like, congratulations R, you've cornered the market on being the one-trick pony that academia refuses to let go of. Meanwhile Python is out here running web servers, automating infrastructure, and training neural networks while R is still trying to figure out why <- seemed like a good assignment operator. Sure, R has ggplot2. Python has everything else.

Average AI Bro Discussion

Average AI Bro Discussion
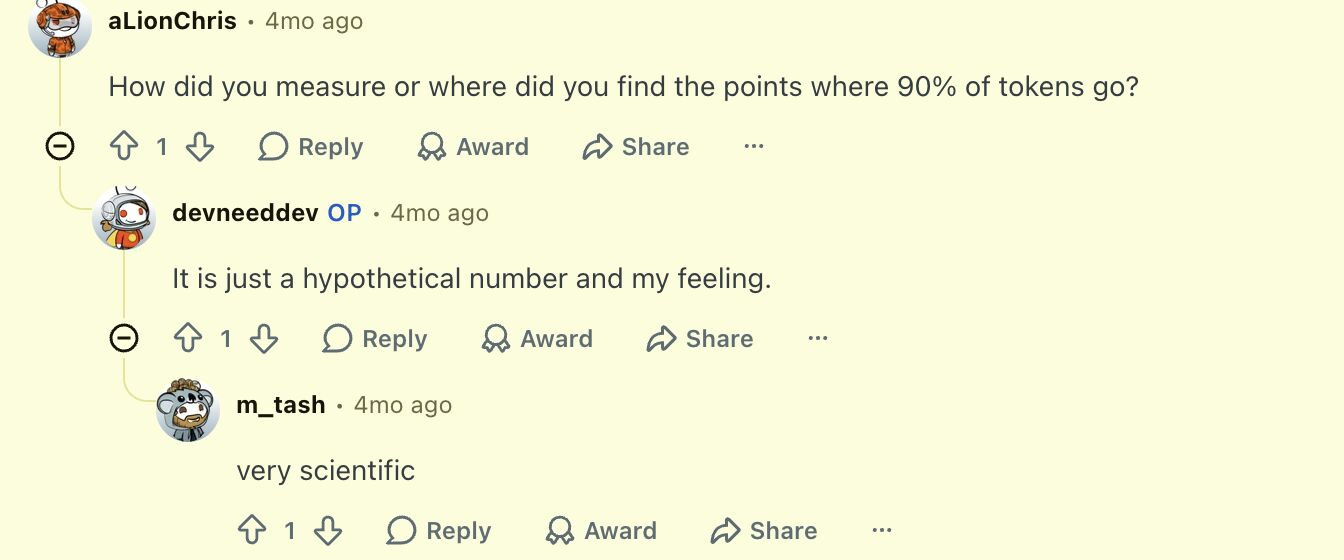
When someone asks for actual data and methodology behind your AI claims, just say it's "a hypothetical number and my feeling." Works every time. The scientific rigor here is truly breathtaking—right up there with "trust me bro" and "the vibes told me so." Nothing says cutting-edge technology like making up statistics based on gut instinct. At least they're honest about it, which is more than you can say for most whitepapers.

Gentlemans Rules For Software Engineering

Gentlemans Rules For Software Engineering
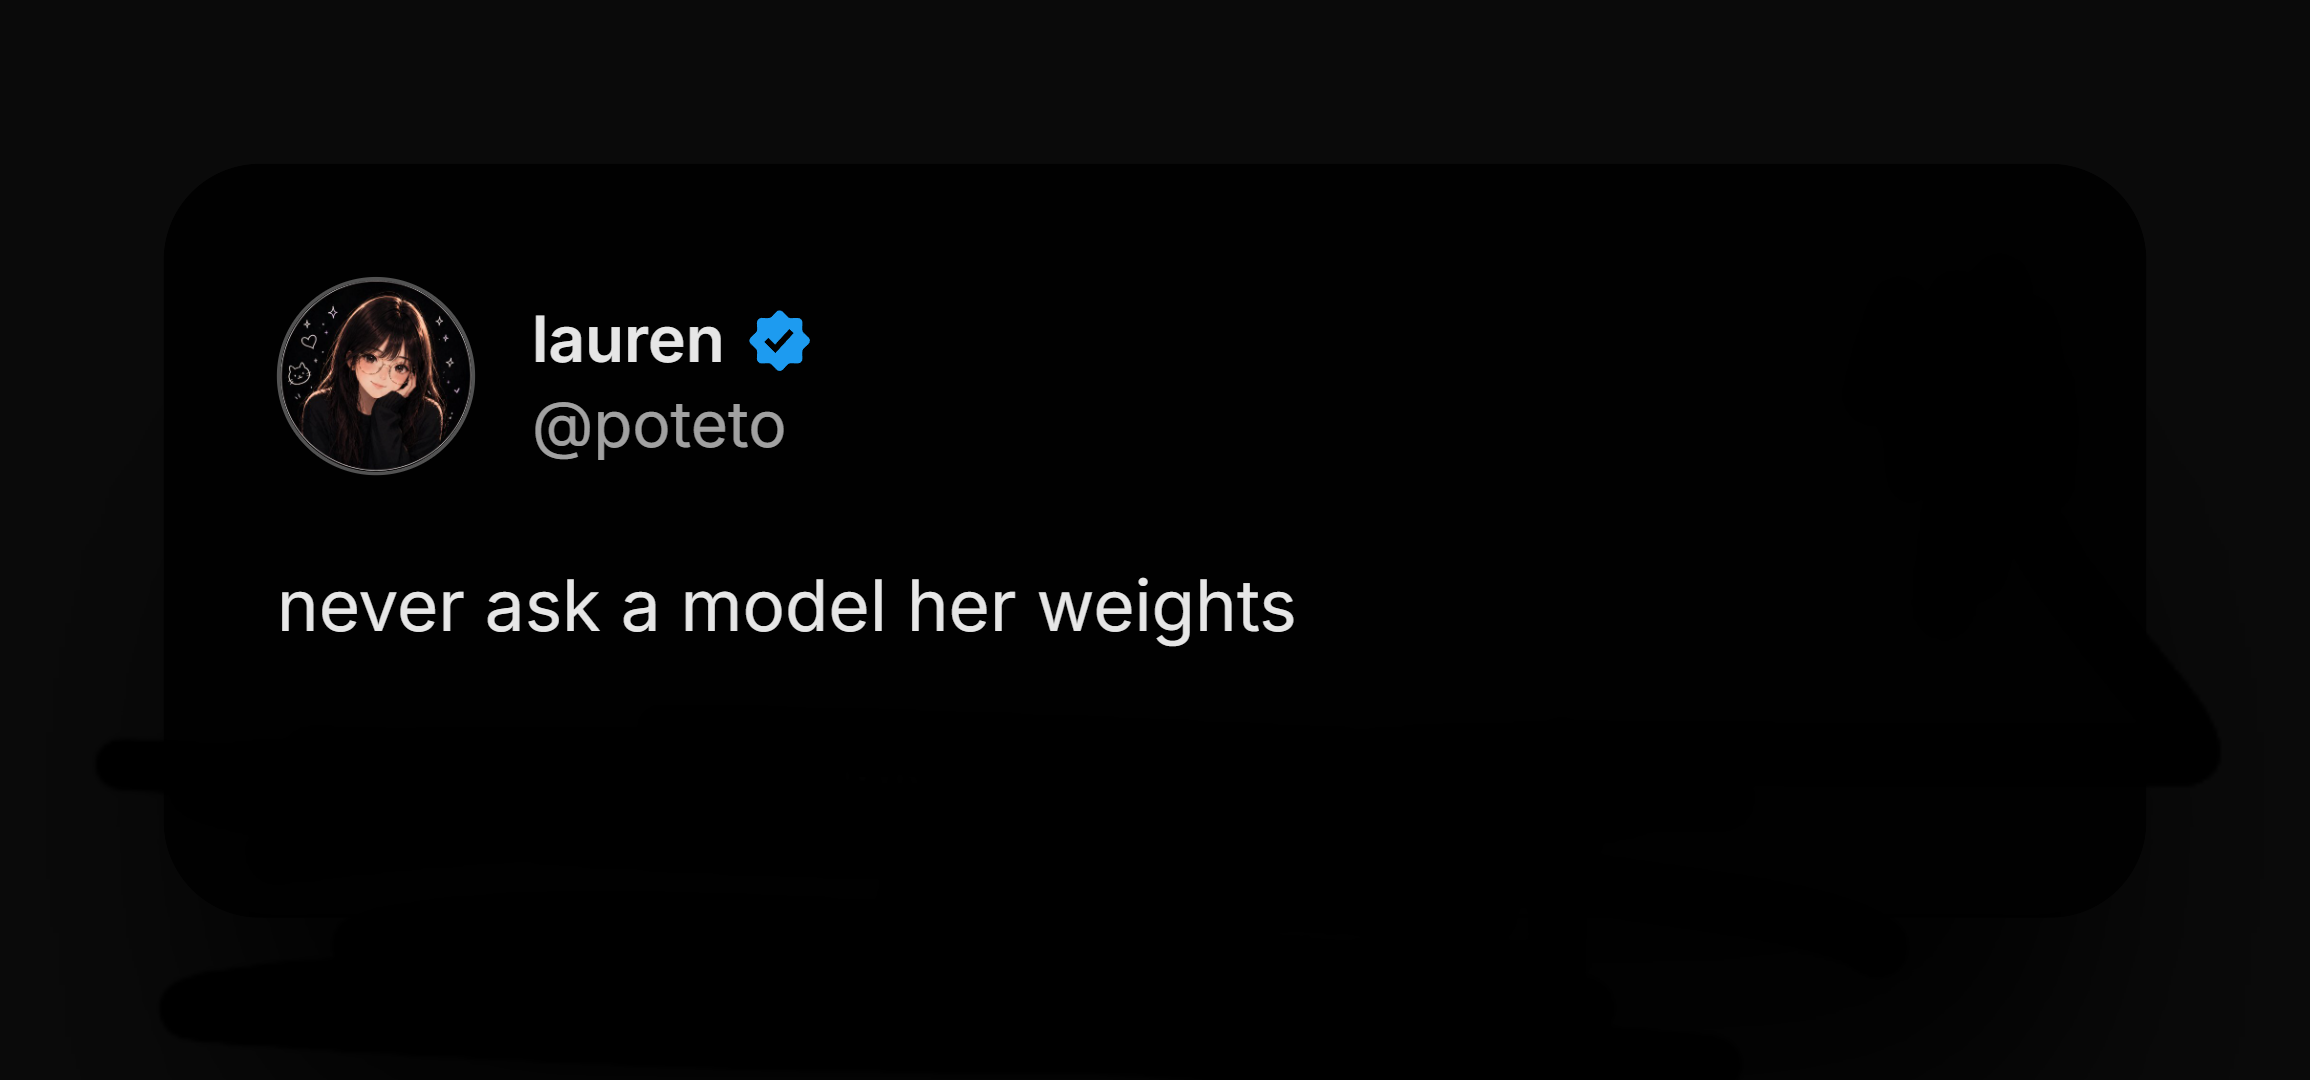
Oh, the sacred code of chivalry has been updated for the machine learning era! Just as you'd never dare ask a lady her age, you shall NEVER inquire about a neural network's parameter count. Is it 175 billion? 7 billion? None of your business, good sir! Those model weights are as private as someone's browser history. The sheer audacity of asking "how many parameters does your model have?" is basically the AI equivalent of asking someone their salary at a dinner party. Some things are simply too personal, too intimate, too... computationally expensive to discuss in polite society. True gentlemen simply nod respectfully and pretend they're not dying to know if you're running a potato or a supercomputer.

Average Recommendation System

Average Recommendation System
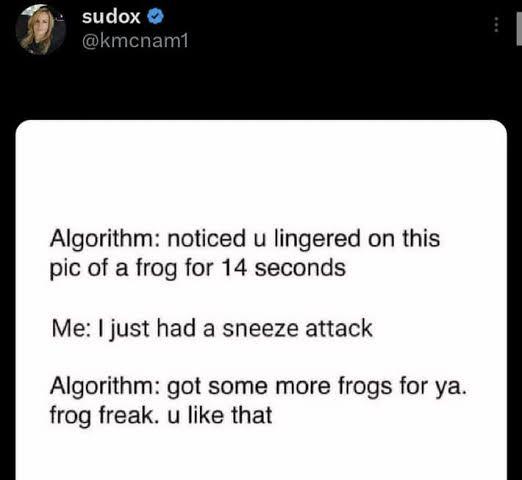
You accidentally glance at a picture of a frog for 14 seconds because you're mid-sneeze, and suddenly every recommendation algorithm in existence decides you're a herpetology enthusiast. Next thing you know, your entire feed is amphibian-themed content, frog memes, and probably ads for terrarium supplies. The algorithm doesn't care about context—it only sees engagement metrics. Dwell time? Check. Eye tracking? Check. Clearly you're obsessed with frogs now. No amount of "not interested" clicks will save you from the frog content pipeline you've been algorithmically sentenced to. The machine learning model has spoken, and it has determined your new identity: frog person. This is why recommendation systems need way more features than just time-on-screen. Intent detection, negative signals, and maybe some basic common sense would help, but nah—let's just spam users with content based on a single accidental interaction.

Technically Astute Karen

Technically Astute Karen
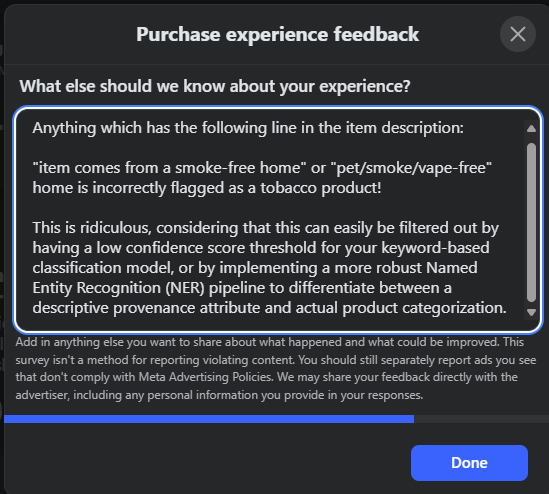
When Karen stops asking for the manager and starts asking for better machine learning models instead. Someone REALLY did their homework before writing this feedback—casually dropping "Named Entity Recognition pipeline" and "keyword-based classification model" like they're ordering a latte. The sheer audacity of complaining that a tobacco product flag is "ridiculous" while simultaneously suggesting they implement NER to fix their classification system is absolutely SENDING me. This is what happens when a data scientist gets their package mislabeled and decides violence (the technical kind) is the answer. The confidence score threshold suggestion? *Chef's kiss*. They're not just complaining—they're providing a whole architecture review in a feedback form.

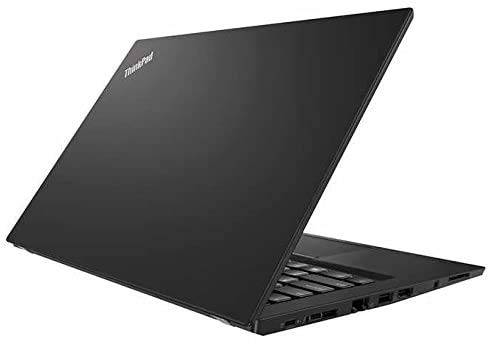
Lenovo ThinkPad T480S Business Laptop: Core i7-8550U, 16GB RAM, 512GB SSD, 14inch Full HD Display, Backlit Keyboard, Windows 10

Lenovo ThinkPad T480S Business Laptop: Core i7-8550U, 16GB RAM, 512GB SSD, 14inch Full HD Display, Backlit Keyboard, Windows 10
Brand Lenovo · Screen Size 14 Inches · Computer Memory Size 16 GB

The Circle Of Life

The Circle Of Life
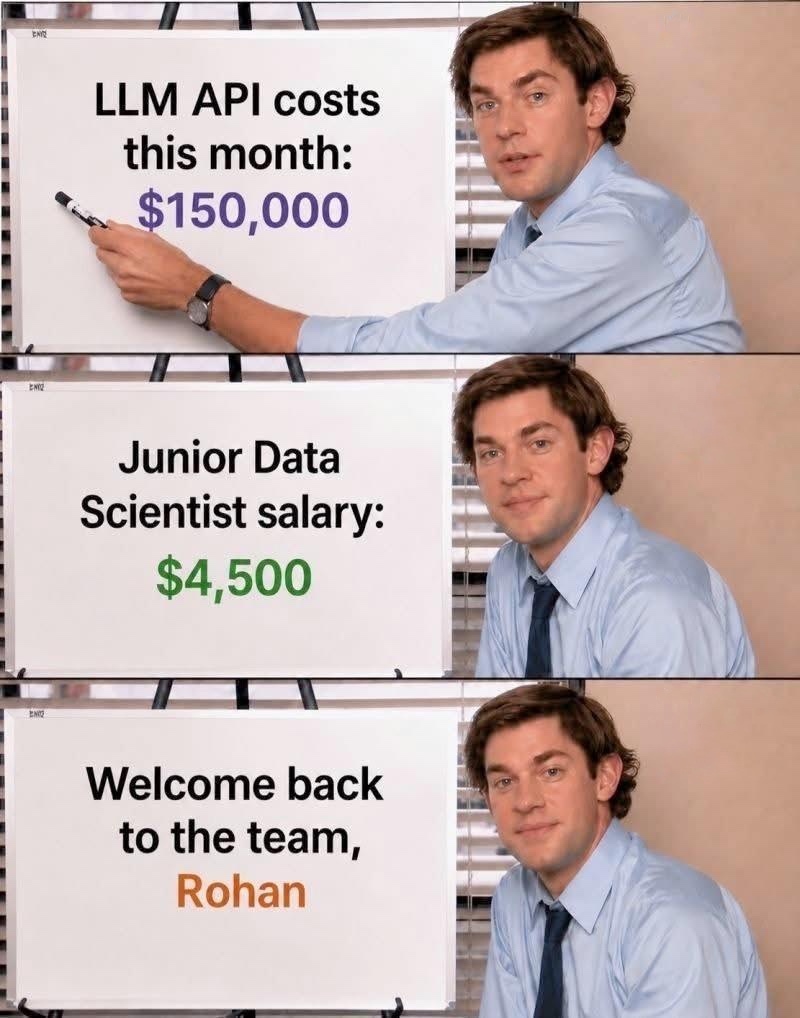
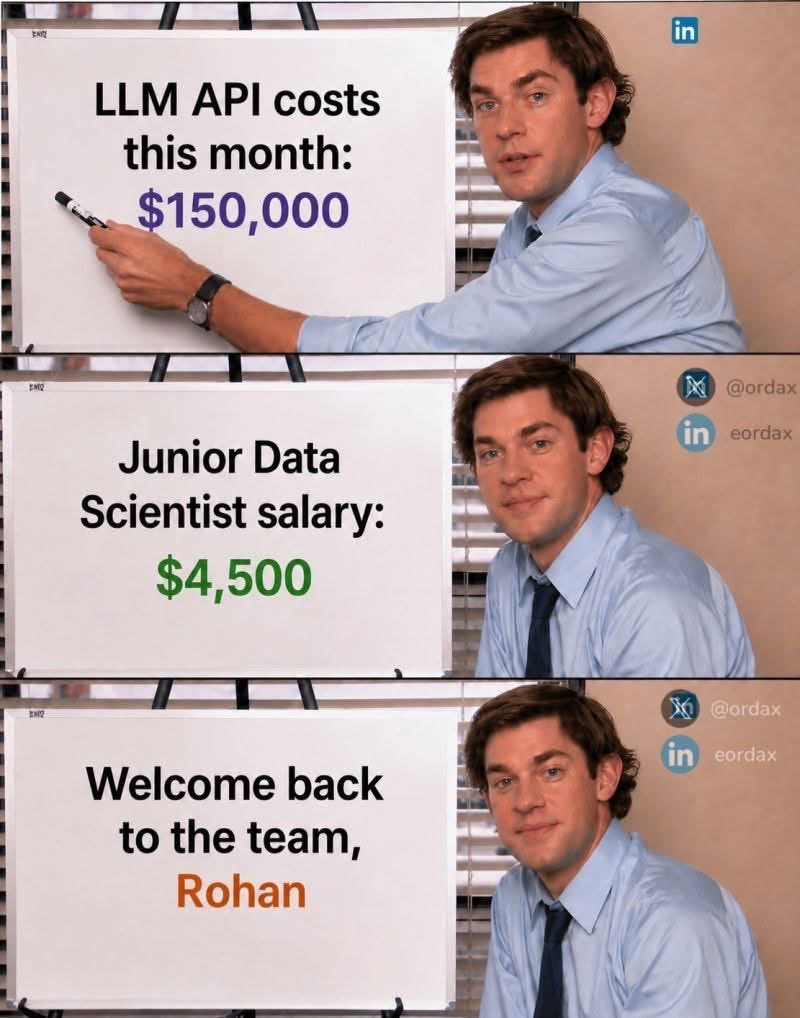
The beautiful economics of AI in 2024: spend $150k monthly on LLM APIs, pay your junior data scientist $4.5k, then act surprised when they leave for literally anywhere else. But here's the kicker—you'll replace them with... more LLM API calls, which costs you even more money. Then when the bill gets too spicy, you'll hire another junior at poverty wages to "optimize" the prompts. It's the perpetual motion machine of terrible business decisions, except instead of free energy, you're generating infinite burnout and AWS invoices. The real irony? That junior could probably fine-tune an open-source model for a fraction of the API costs, but management would rather burn cash on OpenAI credits than invest in actual talent. Welcome back, Rohan. Your RSUs are still underwater.

Welcome To The Real World

Welcome To The Real World
Company spends $150k monthly on LLM API calls, pays their junior data scientist $4.5k. Math checks out. The AI tools cost 33x more than the human using them, but sure, let's talk about how AI is making everything more efficient. Nothing says "optimized business model" like your infrastructure costs being orders of magnitude higher than your payroll. At least when Rohan inevitably quits for better pay, they'll still have $145,500 left over each month to contemplate their life choices.

I Just Learned Decision Tree And It Shows

I Just Learned Decision Tree And It Shows
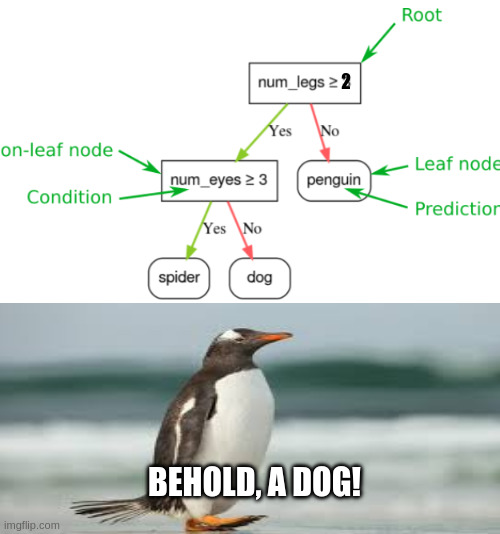
When you learn decision trees in your first ML class and suddenly think you can classify the entire animal kingdom with two features. The tree confidently declares that anything with ≥2 legs but <3 eyes is either a spider or a dog. Naturally, our penguin friend here gets classified as a dog because it has 2 legs and 2 eyes. The logic is flawless, the execution is perfect, the result is... well, technically a dog now. This is what happens when you oversimplify your feature set and have the confidence of someone who just finished chapter 3 of their machine learning textbook. Sure, the decision tree works exactly as programmed, but maybe—just maybe—we needed more than "number of legs" and "number of eyes" to distinguish between spiders, dogs, and flightless aquatic birds.

When You Overfit In Real Life

When You Overfit In Real Life
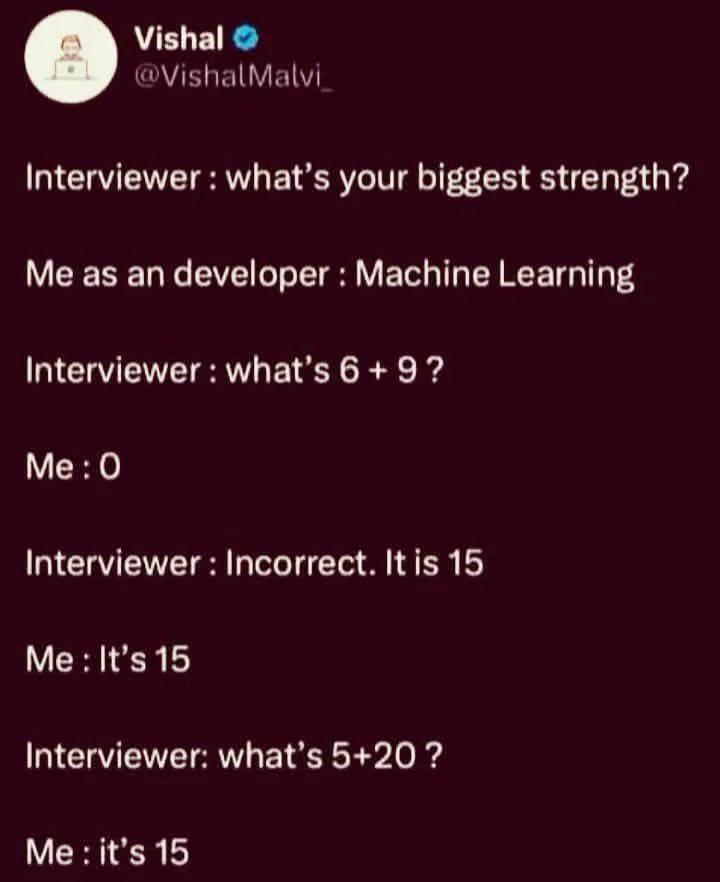
When your ML model learns the training data SO well that it literally memorizes the answer "15" and decides that's the universal solution to EVERYTHING. Congratulations, you've created the world's most confident idiot! Our brave developer here proudly claims Machine Learning as their biggest strength, then proceeds to demonstrate they've trained themselves on exactly ONE example. Now every math problem? 15. What's for dinner? Probably 15. How many bugs in production? You guessed it—15. This is overfitting in its purest, most beautiful form: zero generalization, maximum confidence, absolute chaos. The model (our developer) has learned the noise instead of the pattern, and now they're out here treating basic arithmetic like it's a multiple choice test where C is always the answer.

Please God I Just Need One Dataset

Please God I Just Need One Dataset
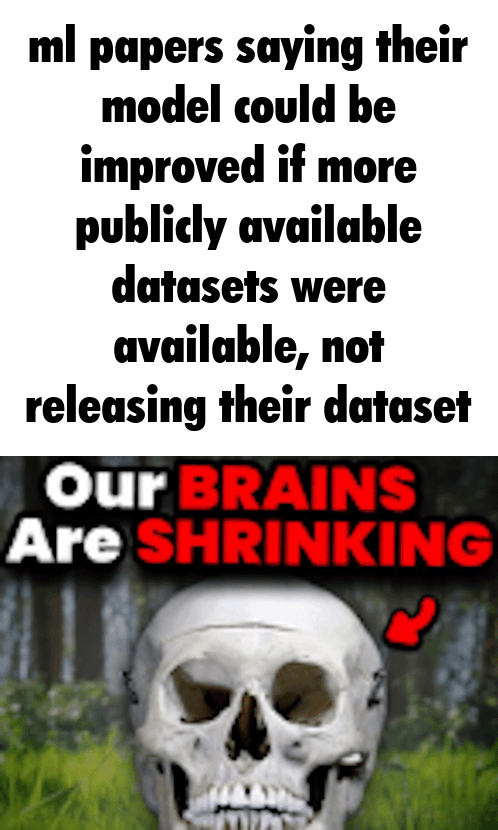
The academic equivalent of "my code would work if you just gave me the requirements." ML researchers out here writing papers about how their groundbreaking model desperately needs more data to reach its full potential, then proceed to guard their datasets like Gollum with the One Ring. The irony is so thick you could train a neural network on it. You want to advance the field? Cool, share your data. You want citations? Also cool, but maybe let others actually reproduce your results first. Instead we get this beautiful catch-22 where everyone complains about data scarcity while sitting on terabytes of proprietary datasets that could actually push research forward. The skull shrinking perfectly captures the cognitive dissonance required to publish "we need open datasets" while keeping yours locked up tighter than production credentials. At least they're honest about needing data though—unlike that one paper claiming SOTA results on a dataset nobody can access.