Cuda Memes

Posts tagged with Cuda
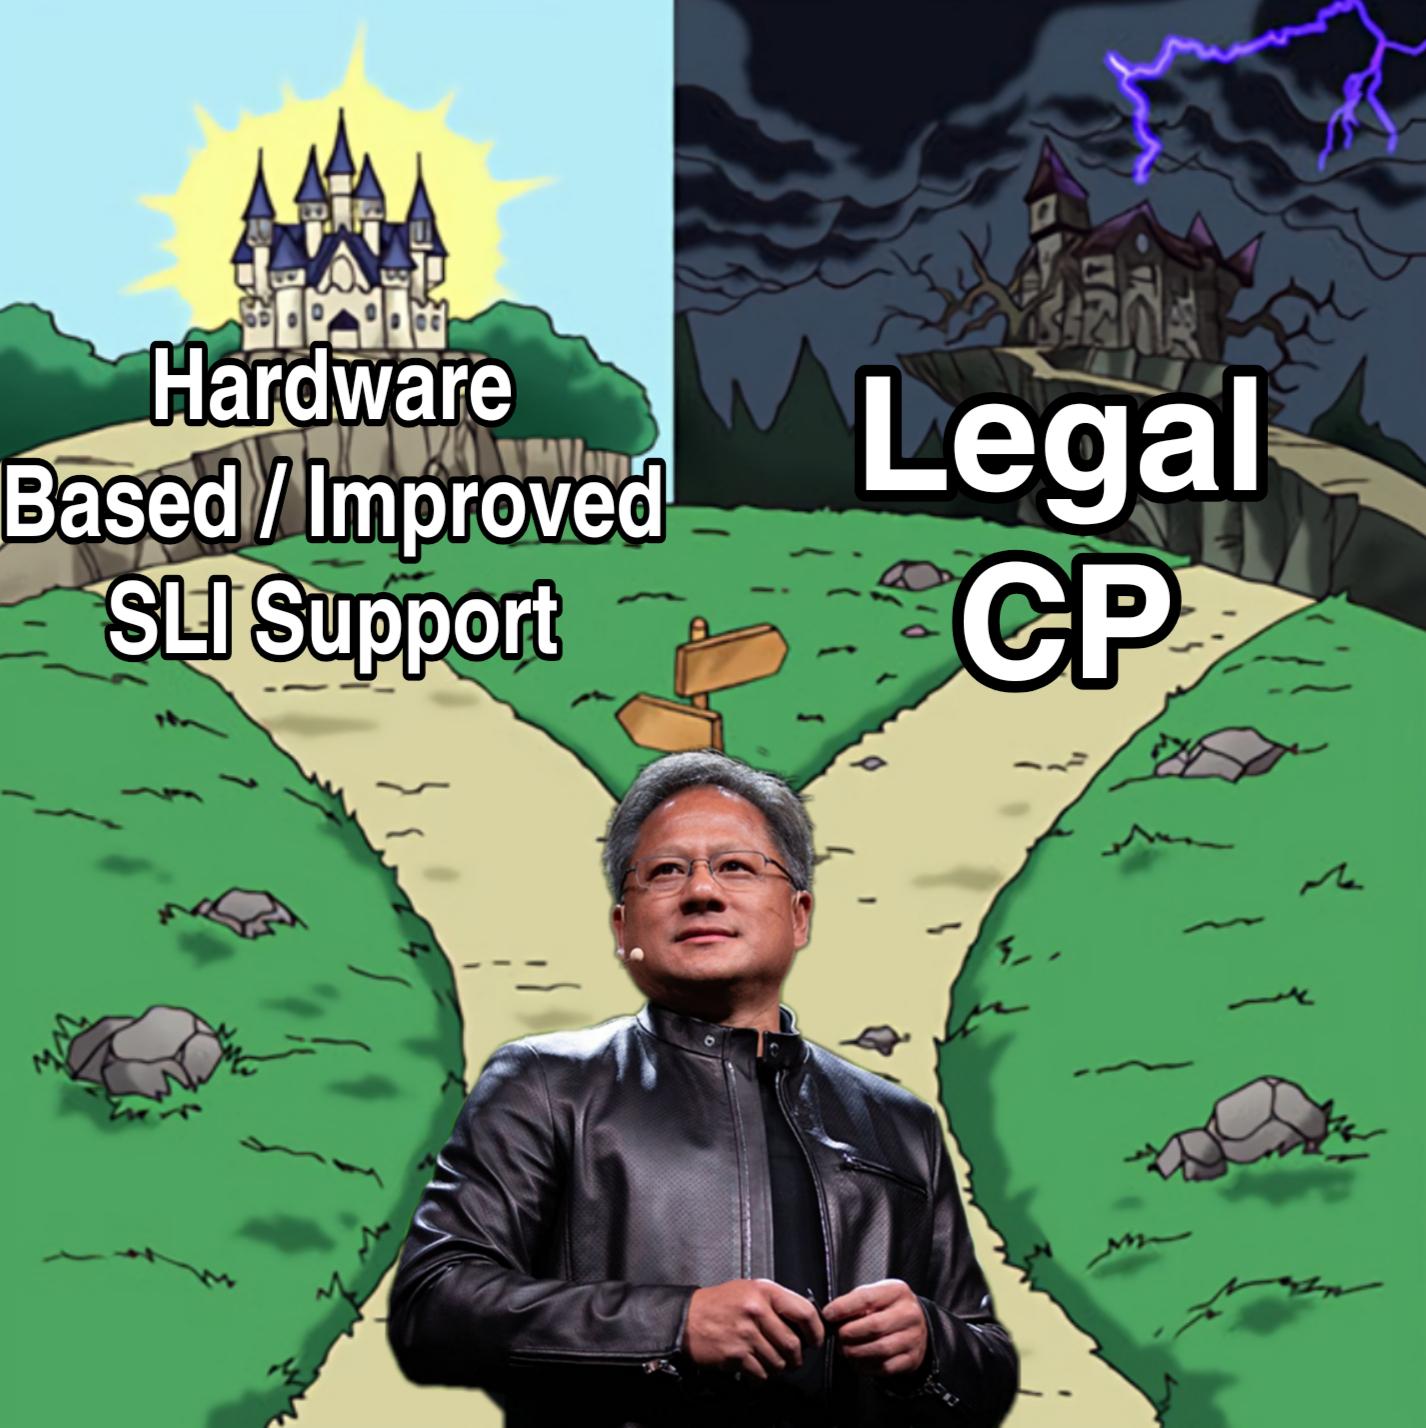
Thank You Jensen, Clearly This Was The Only Logical Trajectory For A Company That Makes Graphics Cards For Computers

Thank You Jensen, Clearly This Was The Only Logical Trajectory For A Company That Makes Graphics Cards For Computers
Remember when NVIDIA made graphics cards so gamers could run Crysis? Yeah, Jensen Huang had other plans. Dude saw the fork in the road between "making better SLI support for gamers" and "becoming a trillion-dollar AI overlord" and didn't even hesitate. Now NVIDIA's GPUs power ChatGPT while gamers are out here selling kidneys for a 4090. The sunny castle represents the innocent days of hardware improvements and dual-GPU setups that maybe worked 60% of the time. The ominous lightning-struck fortress? That's NVIDIA's current form as an AI infrastructure monopoly with legal departments bigger than most startups. They went from "can it run Doom?" to "can it train a language model?" faster than you can say "CUDA cores." Jensen's standing there in his signature leather jacket like "yeah, I chose violence... and market dominance." The man pivoted from rendering triangles to rendering the entire tech industry obsolete without his chips. Absolute legend move, even if it means your gaming rig costs more than a used car.

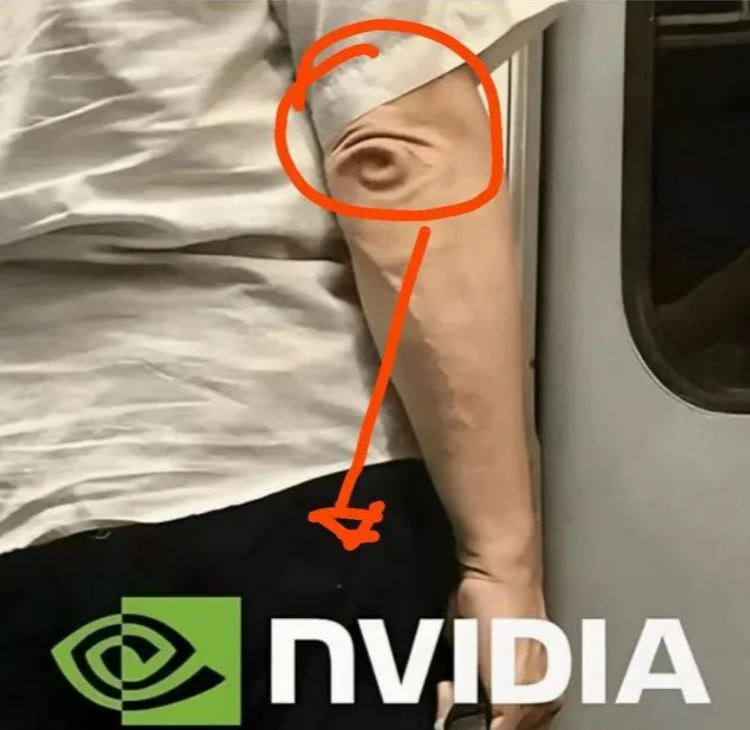
Nvidia Arm

Nvidia Arm
So someone's elbow crease decided to cosplay as the Nvidia logo, and honestly? It's more convincing than half the GPU stock announcements we've seen. The resemblance is uncanny - that distinctive eye shape formed by nature's own rendering engine. This hits different when you remember Nvidia literally tried to acquire ARM (the chip architecture company) for $40 billion back in 2020. The deal fell through in 2022, but the universe apparently said "fine, I'll do the merger myself" and just printed the logo on someone's actual arm instead. Poetry. Your body when it knows you've spent too much time optimizing CUDA kernels and debugging parallel processing issues. The hardware-software integration we didn't ask for but absolutely deserve.

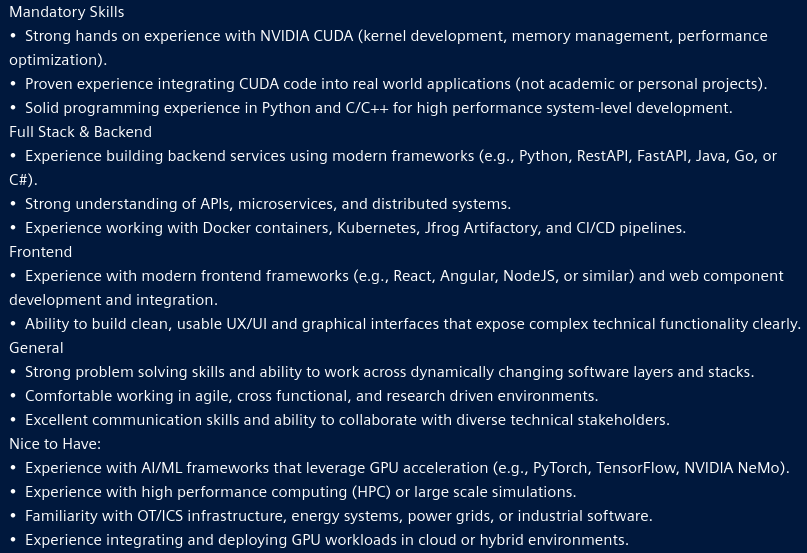
Full Stack Developer Requirement

Full Stack Developer Requirement
So you're hiring a "Full Stack Developer" but the job description reads like you're trying to assemble the Avengers of software engineering. CUDA kernel development? AI/ML frameworks with GPU acceleration? Docker, Kubernetes, CI/CD pipelines, microservices, AND you want them to make pretty UIs? Buddy, that's not a full stack developer—that's like five different senior engineers crammed into one underpaid position. You're basically asking for someone who can optimize NVIDIA kernels in the morning, architect distributed systems at lunch, build React components in the afternoon, and deploy to a hybrid cloud before dinner. All while being "comfortable in agile environments" (translation: we have no idea what we're doing but we have standups). The "Nice to Have" section is the cherry on top—experience with high-performance computing and industrial software? At that point just ask for a PhD in Computer Science and 10 years of experience with technologies that came out 2 years ago. Salary range: $65k-$75k. Benefits: Free coffee and imposter syndrome.

Max Autotune Prune Choices Based On Shared Mem Flag Wasn't As Groundbreaking As It Was Promised To Be

Max Autotune Prune Choices Based On Shared Mem Flag Wasn't As Groundbreaking As It Was Promised To Be
You've enabled every optimization flag known to humanity. CUDA kernels? Optimized. Batch sizes? Tuned. Mixed precision? Obviously. You've read the entire PyTorch performance guide twice, set torch.backends.cudnn.benchmark=True , and even sacrificed a USB drive to the machine learning gods. Your training loop still moves like it's running on a Pentium II from 1997. Turns out all those fancy optimization techniques that promised "up to 10x speedup" in the blog posts were tested on datasets that fit in a teacup and hardware that costs more than a small car. The real bottleneck? Your data loader was single-threaded the whole time. Classic.

When You Criticize Nvidia

When You Criticize Nvidia
Say one word about Nvidia's proprietary drivers, their CUDA monopoly, or their Linux support and watch the fanboys materialize like they're being summoned by a GPU mining rig. The company's worth more than most countries' GDP, but somehow needs defending from random devs on Reddit. Meanwhile Linus Torvalds literally gave them the middle finger on camera and they're still printing money faster than their RTX cards can render frames. The funniest part? Half the people defending them can't even afford their GPUs at scalper prices.

Saved You An Entire Week Of Incessant Fooling Around, And An Entire Month Of Intermittent Pauses To Test Ideas In Just Over An Hour. Solid Product.

Saved You An Entire Week Of Incessant Fooling Around, And An Entire Month Of Intermittent Pauses To Test Ideas In Just Over An Hour. Solid Product.
ChatGPT spent 69 minutes and 42 seconds "thinking" just to tell you "You can't." That's like watching your senior architect stare at the whiteboard for over an hour during a planning meeting, only for them to turn around and say "nope, not possible" without any further explanation. The irony here is beautiful. Someone's trying to install CUDA 12.1 on Ubuntu 24.04, and the AI that supposedly saves you weeks of work just burned over an hour to deliver the most unhelpful two-word response possible. No workarounds, no alternatives, no "but here's what you CAN do" — just pure, unfiltered rejection. You could've googled this, read three Stack Overflow threads, tried two wrong solutions, and still had time left over to make coffee. But sure, let's call it "incredible" and a "solid product." The future of development is waiting 69 minutes for a chatbot to say no.

Parallel Computing Is An Addiction

Parallel Computing Is An Addiction
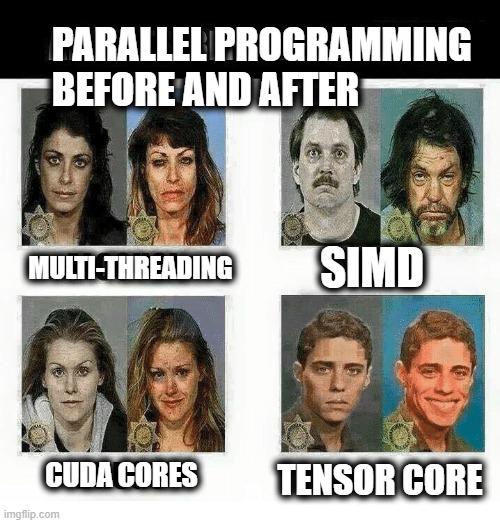
Multi-threading leaves you looking rough around the edges—classic race conditions and deadlocks will do that. SIMD hits even harder with those vectorization headaches. CUDA cores? You're barely holding it together after debugging memory transfers between host and device. But Tensor cores? You're grinning like an idiot because your matrix multiplications just became absurdly fast and you finally feel alive again. Each level of parallel computing optimization takes a piece of your soul, but the performance gains are too good to quit. You start with simple threading, then you're chasing SIMD instructions, next thing you know you're writing CUDA kernels at 2 AM, and before long you're restructuring everything for tensor operations. The descent into madness has never been so well-optimized.

NordVPN

NordVPN
Encrypt your traffic on public Wi-Fi, stream from anywhere, and cover up to ten devices with one plan. 30-day money-back guarantee.

The Moment I Learnt About Thread Divergence Is The Saddest Point Of My Life

The Moment I Learnt About Thread Divergence Is The Saddest Point Of My Life
Ah, the cruel reality of GPU programming. In normal code, an if-else is just a simple branch. But on a GPU, where threads run in lockstep, if some threads take the "if" path and others take the "else" path, your fancy graphics card basically says: "Cool, I'll just run both paths and waste half my processing power." Thread divergence: where your $1200 graphics card suddenly performs like it's running on hamster power because one pixel decided to be special. And we all just accept this madness as "the coolest thing ever" while silently dying inside.

GPT 5 Pro Accepts Defeat

GPT 5 Pro Accepts Defeat
After 69 minutes of deep contemplation, the AI finally arrives at the same conclusion every developer reaches after 8 hours of dependency hell: sometimes the tech stack just says no. CUDA on Ubuntu is like trying to get your ex back—theoretically possible, but the universe has other plans. The blunt "You can't" is probably the most honest answer in AI history. No hallucinations, no 15-paragraph explanation, just pure tech nihilism.

Heaviest Objects In The Universe

Heaviest Objects In The Universe
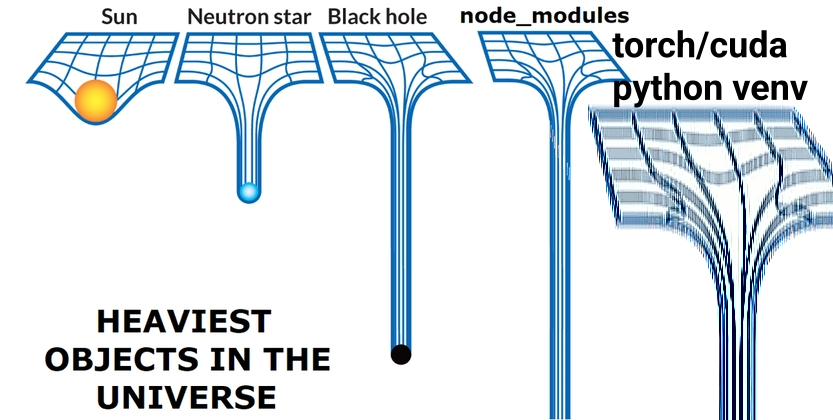
The cosmic weight scale has a new champion! While astronomers worry about black holes and neutron stars, developers know the true gravitational monsters: Python virtual environments, Node modules, and PyTorch/CUDA installations. Nothing collapses spacetime quite like waiting for npm install to finish or watching your disk space vanish as PyTorch downloads half the internet. At least black holes have the decency to be millions of light years away—your Python venv is right there, crushing your hard drive and your spirits simultaneously.

How Models Are Maintained

How Models Are Maintained
The precarious state of AI infrastructure in a single image. At the top, we have a massive elephant (the multi-billion parameter model) balancing on a beach ball (properly configured CUDA drivers). Meanwhile, the entire operation is held up by two ants labeled as "unpaid PhD students" who are desperately keeping the computing cluster running with nothing but SSH access and blind optimism. This is basically the tech equivalent of a nuclear reactor being maintained by two interns with duct tape and a Wikipedia printout. And yet, somehow, this is how we're building the future of technology.

MNN 15.6" FHD 60Hz Portable Monitor USB-C HDMI IPS HDR Gaming Laptop

MNN 15.6" FHD 60Hz Portable Monitor USB-C HDMI IPS HDR Gaming Laptop
Full HD Portable Monitor - MNN 15.6inch portable laptop monitor with 1920*1080 resolution, advanced IPS glossy screen support 178° full viewing angle, it renders accurate and bright color, draws you …