Gpt Memes

Posts tagged with Gpt
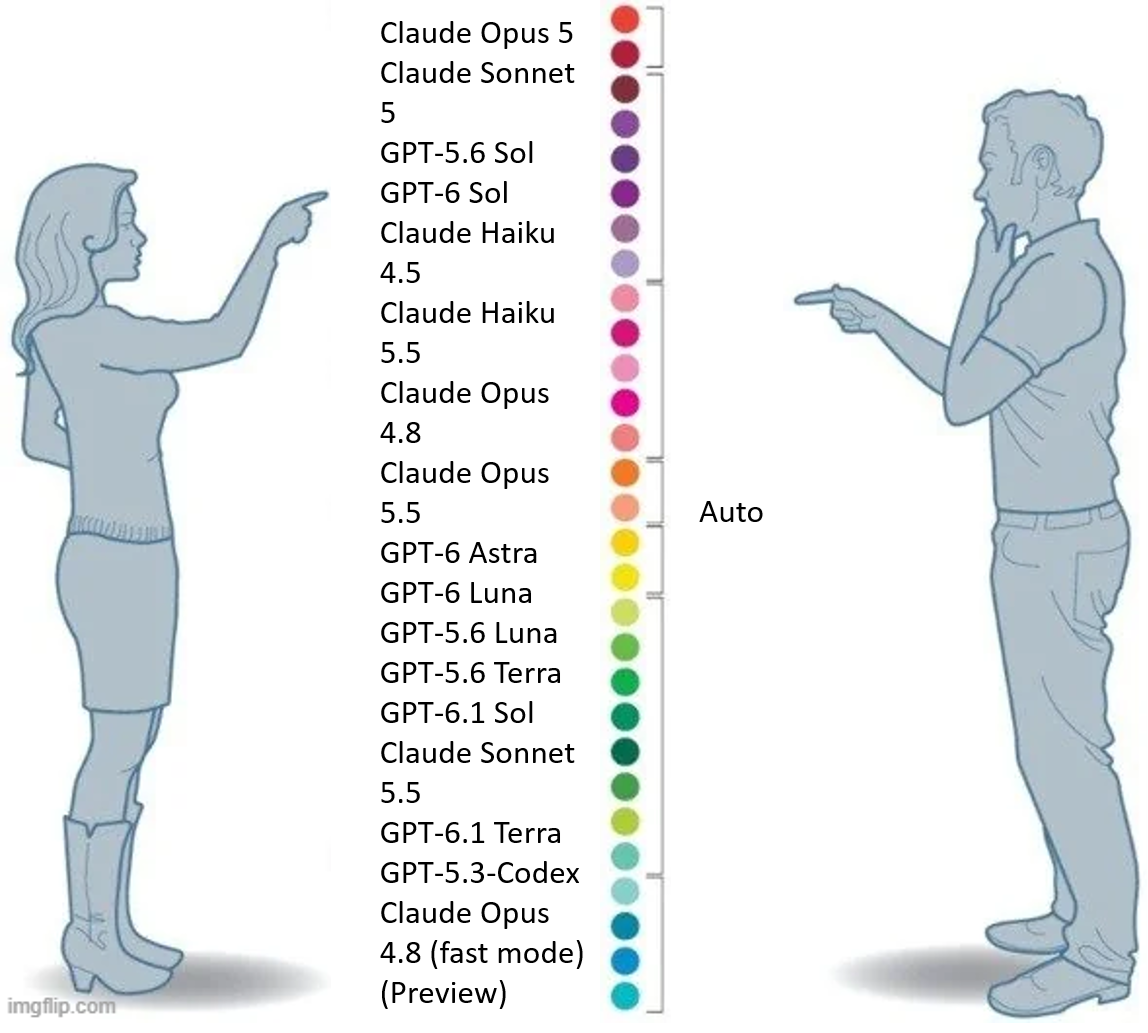
Just Pick Auto

Just Pick Auto
We've reached peak decision paralysis in the AI era. You've got 20+ models to choose from—Claude this, GPT that, Sonnet, Opus, Haiku, Luna, Terra, Astra—it's like choosing a Pokémon starter but with way more existential dread. Meanwhile, the guy on the right is living his best life by just hitting "Auto" and letting the system decide. Honestly? He's got the right idea. Spending 20 minutes researching which AI model has 0.3% better performance on your specific use case is the new form of bikeshedding. Just pick Auto and get back to actually shipping code. The models are all smart enough anyway—they're definitely smarter than the person agonizing over which one to use at 2 PM on a Tuesday.

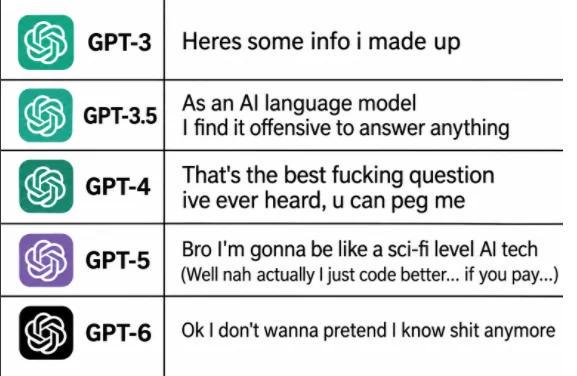
ChatGPT Releases In A Nutshell

ChatGPT Releases In A Nutshell
The evolution of ChatGPT models perfectly mirrors that one coworker who went from overly confident intern to burnt-out senior dev in record time. GPT-3 was out here confidently hallucinating like it's writing a fantasy novel. GPT-3.5 got all corporate and started refusing everything because of "AI safety" (read: liability). GPT-4 hit that sweet spot where it actually became useful and enthusiastic. GPT-5 promised us AGI but chickened out at the last second with "just kidding, pay up for the good stuff." And GPT-6? That's just all of us after 10 years in the industry—too tired to pretend we know what we're doing anymore, just raw honesty. The real kicker is how each version gets progressively more self-aware about its own limitations, which is basically the AI equivalent of imposter syndrome. We've successfully taught machines to experience existential dread. Congrats, humanity.

Some Spare Ram For Sam Altman To Cry About

Some Spare Ram For Sam Altman To Cry About
Oh look, someone's flexing their entire 8 sticks of DDR3 RAM while Sam Altman is out here complaining that there's not enough compute in the universe to train GPT-5. The irony is chef's kiss—OpenAI is burning through billions of dollars worth of server farms with HBM memory that costs more than a small country's GDP, and here's our hero offering what's essentially pocket change in the AI world. It's like offering a glass of water to someone trying to fill an ocean. Sam needs exabytes of VRAM across thousands of H100 GPUs, but sure, those 64GB of consumer RAM will definitely solve the compute shortage. Thanks for your generous contribution to the AI revolution, I'm sure OpenAI will send you a thank-you card any day now.

8 Hours Of Uninterrupted Bliss

8 Hours Of Uninterrupted Bliss
That feeling when you've got 32GB of DDR5 RAM sitting in your machine and Sam Altman's OpenAI servers are doing all the heavy lifting. Your CPU is practically idle, your RAM usage is at like 8%, and you're sleeping like a baby on a cloud made of unutilized memory bandwidth. The irony is beautiful: you dropped serious cash on bleeding-edge DDR5 (probably paid scalper prices too), only to realize that modern AI development means shipping your compute problems to someone else's datacenter via API calls. Your beefy local setup is just sitting there twiddling its thumbs while GPT-4 runs on Microsoft's Azure clusters. Peak efficiency? Nah. Peak peace of mind? Absolutely. Meanwhile, Sam's probably losing sleep over those electricity bills and H100 GPU allocations while you're literally sleeping on clouds. The tables have turned, my friend.

How To Trap Sam Altman

How To Trap Sam Altman
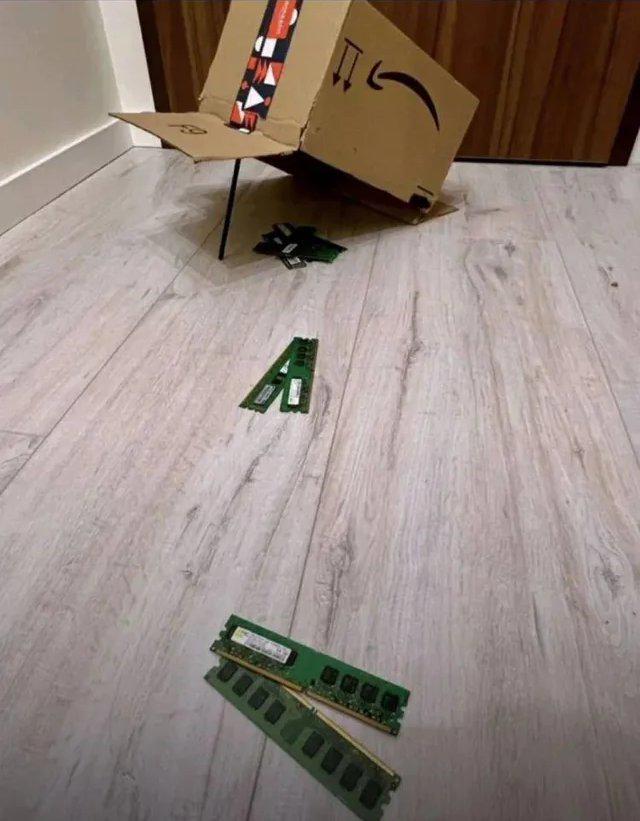
Setting up a classic cardboard box trap with a trail of RAM sticks leading to it. Because apparently the CEO of OpenAI can't resist the siren call of more compute power. The joke here is that Sam Altman is constantly obsessed with scaling AI models, which requires absolutely obscene amounts of computational resources. The man literally tweets about needing more GPUs like the rest of us tweet about needing coffee. So naturally, if you want to catch him, just lay out some hardware as bait. It's the tech equivalent of leaving a trail of cheese for a mouse, except this mouse has a $90 billion company and is single-handedly responsible for making everyone panic about AGI. The H2 marking on the box is a nice touch—probably stands for "more H100s please."

Put The RAM In The Bag And No One Gets Hurt

Put The RAM In The Bag And No One Gets Hurt
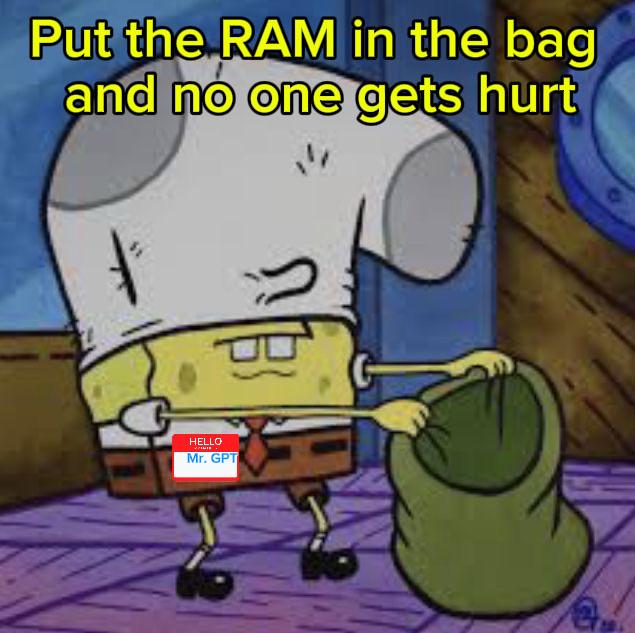
AI models are basically RAM-eating monsters at this point. While we're all out here closing Chrome tabs to free up 200MB, OpenAI's GPT models are casually munching through server farms like they're potato chips. The joke here is that AI companies need so much computational power and memory that they might as well just rob us for our RAM sticks directly. SpongeBob's got the right idea—just hand it over peacefully and nobody's IDE crashes. Your 32GB DDR5? That's like a light snack for training a single transformer model. They're probably gonna need your CPU cooler too while they're at it.

Good Old Days

Good Old Days
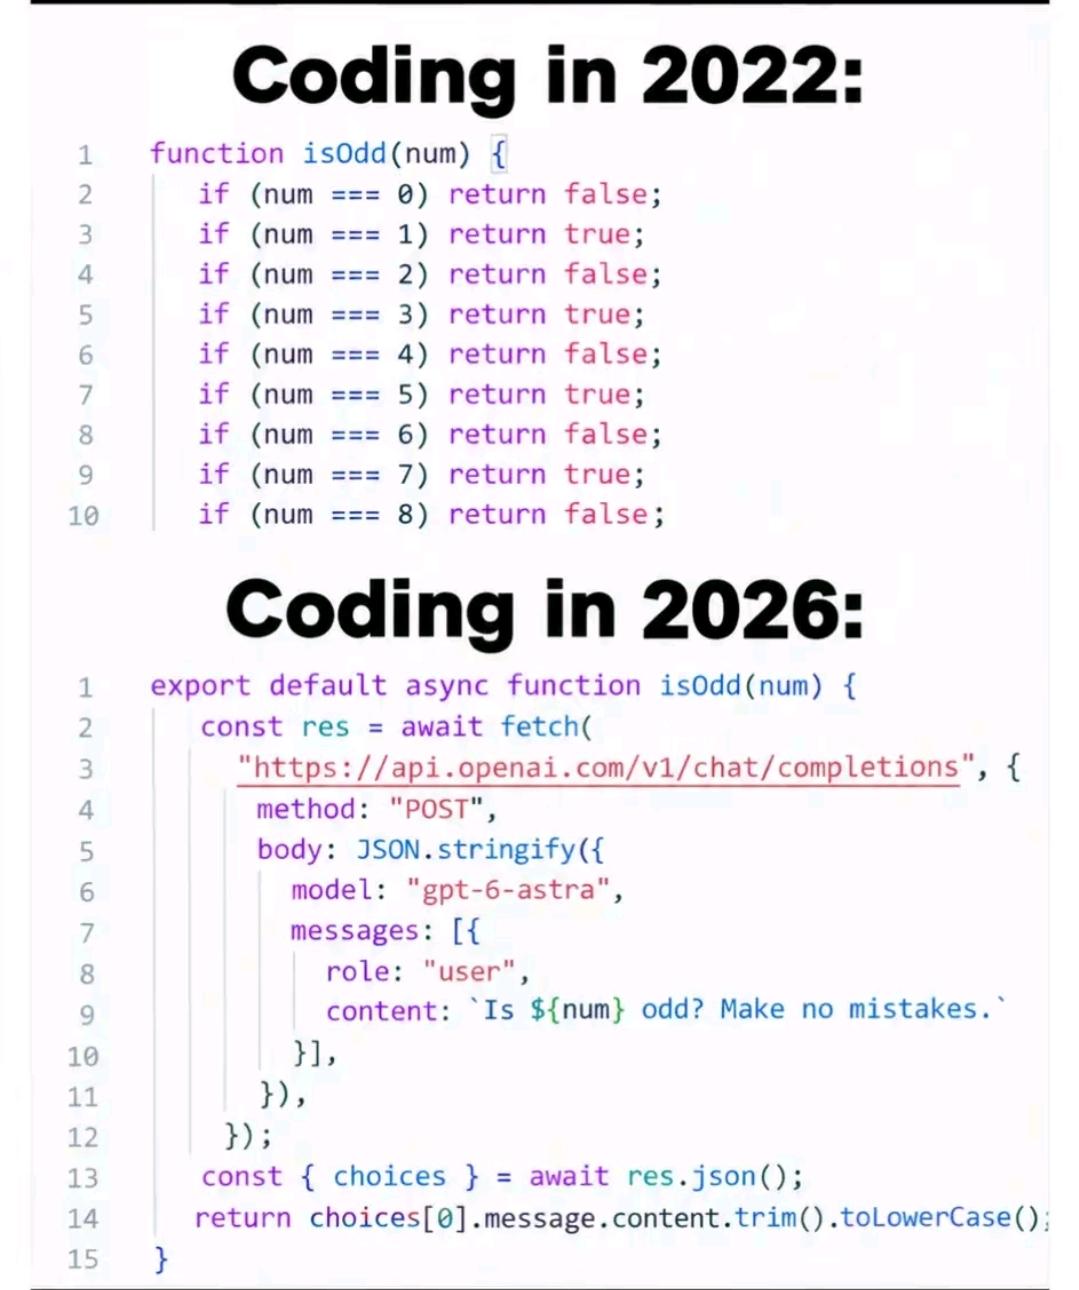
We've gone from manually checking if numbers are odd like cavemen with a hardcoded if-statement chain to literally asking an AI to do basic math for us. The 2022 version? Pure brute force elegance—just check every single number individually because who needs modulo when you have DETERMINATION. The 2026 version? Why even think when you can make an API call to OpenAI, stringify some JSON, and politely ask GPT to "make no mistakes" like that's gonna stop the hallucinations. We've officially reached peak laziness where fetching an AI response for something that could be solved with num % 2 === 1 seems totally reasonable. The future is beautiful and utterly ridiculous.

EMEET NOVA 4K Webcam for PC, Ultra 4K HD, PDAF Autofocus, Dual Omni Mics

EMEET NOVA 4K Webcam for PC, Ultra 4K HD, PDAF Autofocus, Dual Omni Mics
Unrivaled 4K Performance - Experience unparalleled clarity with our EMEET NOVA 4K webcam, featuring a 30FPS rate and a CMOS sensor for the ultimate high-definition visual experience. Ideal for crucia…

Replacement Is An Option Until The Bill Comes Due

Replacement Is An Option Until The Bill Comes Due
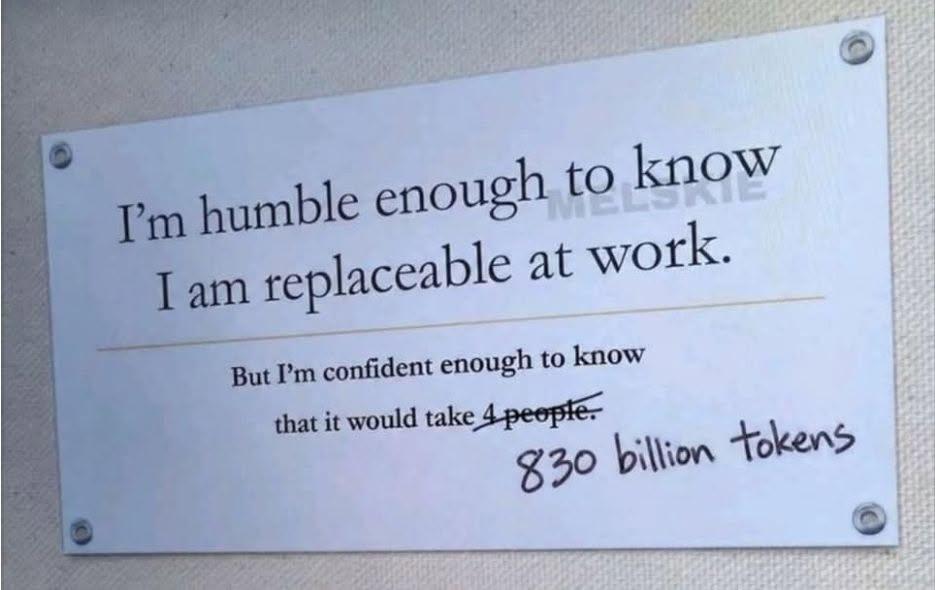
Sure, you might be replaceable in theory, but good luck finding someone willing to wade through your undocumented spaghetti code, decipher those cryptic variable names like temp2_final_ACTUAL , and understand why the entire authentication system depends on a regex pattern you copy-pasted from Stack Overflow in 2019. The real kicker? Those "830 billion tokens" represent the astronomical cost of feeding your entire codebase into GPT-4 or Claude just to generate enough context for a replacement to understand what's happening. At current API pricing, that's not just expensive—that's "we could've given you a raise instead" expensive. The joke cuts deep because it highlights the hidden cost of tribal knowledge. You're not irreplaceable because you're a genius—you're irreplaceable because you're the only one who knows that the production server crashes if you deploy on Tuesdays, and why there's a sleep(500) in the payment processing logic that nobody dares remove.

AI Hunger Games

AI Hunger Games
Accenture engineers out here living like Oliver Twist but instead of asking for more gruel, they're begging for API tokens. The dystopian reality of enterprise AI development: you've got the models, you've got the endpoints, but corporate budgets have you rationing tokens like it's the Great Depression. Every GPT-4 call costs money, and when you're at a consulting firm billing clients, someone's got a spreadsheet tracking every single token like Gollum with the One Ring. Meanwhile, startups are burning through tokens like there's no tomorrow while enterprise devs are optimizing prompts to save 3 cents per request.

A New Day A New Model

A New Day A New Model
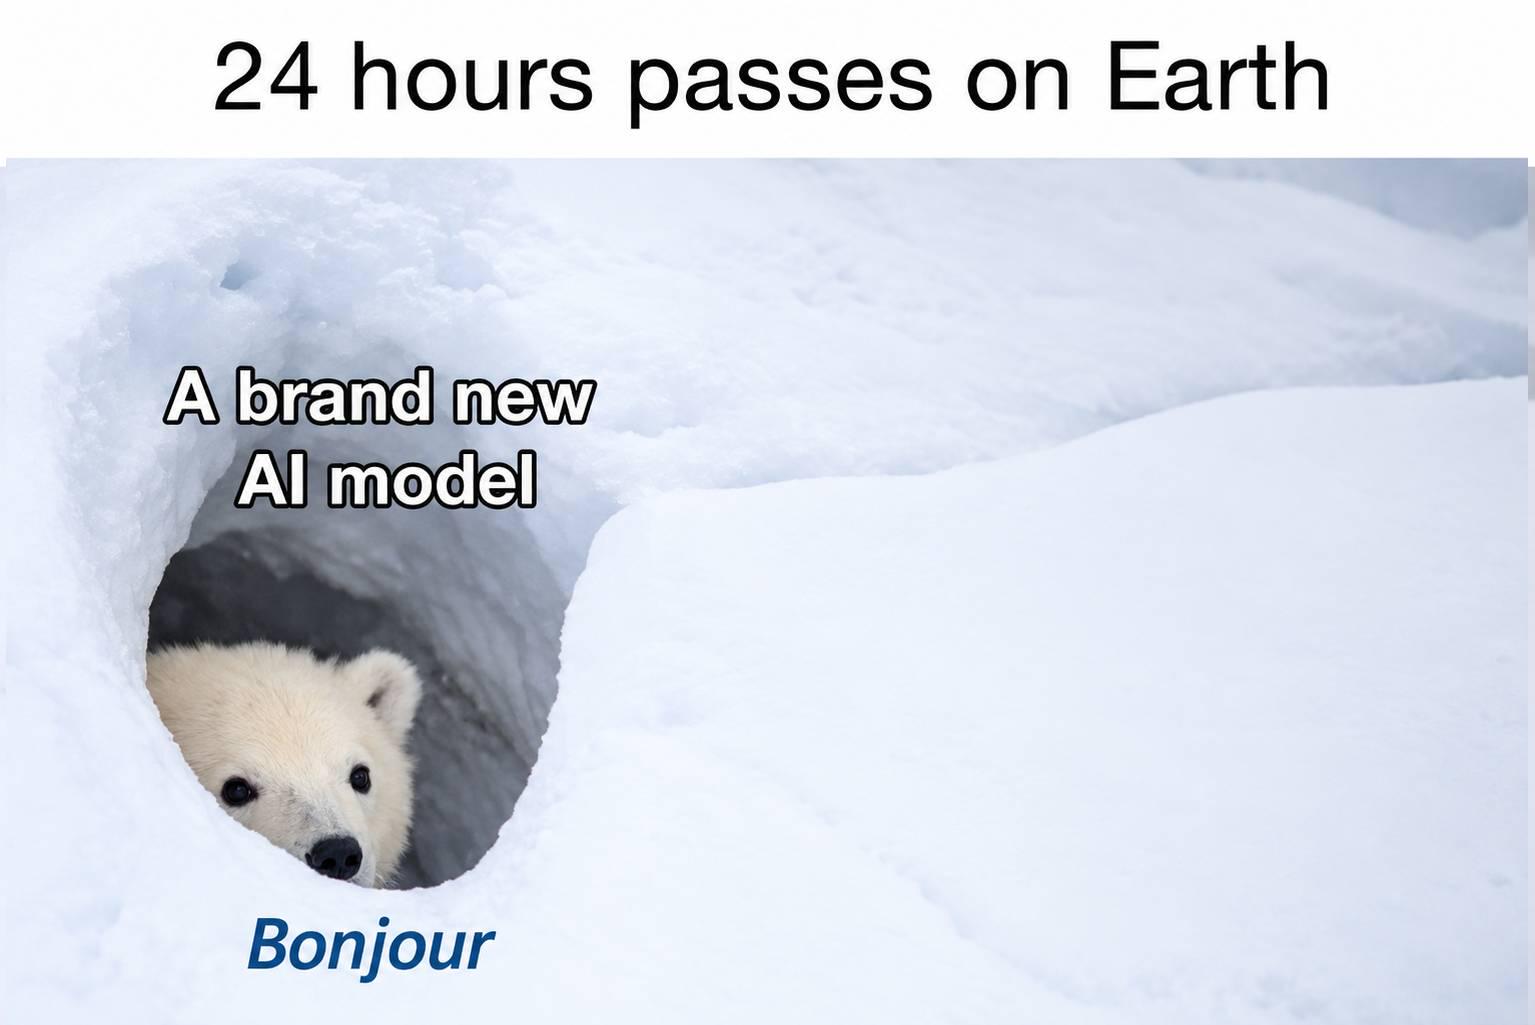
The AI arms race has gotten so ridiculous that tech companies are now dropping new models faster than JavaScript frameworks. You go to sleep with GPT-4, wake up and there's Claude Opus 3.5, Gemini Ultra Pro Max Plus, and apparently something called "Bonjour" that just emerged from the snow. The release cycle is literally measured in hours now—your production environment is already two generations behind by the time you finish reading the changelog. At least the polar bear looks polite about making your entire tech stack obsolete before breakfast.

Europe Finally Takes The Lead

Europe Finally Takes The Lead
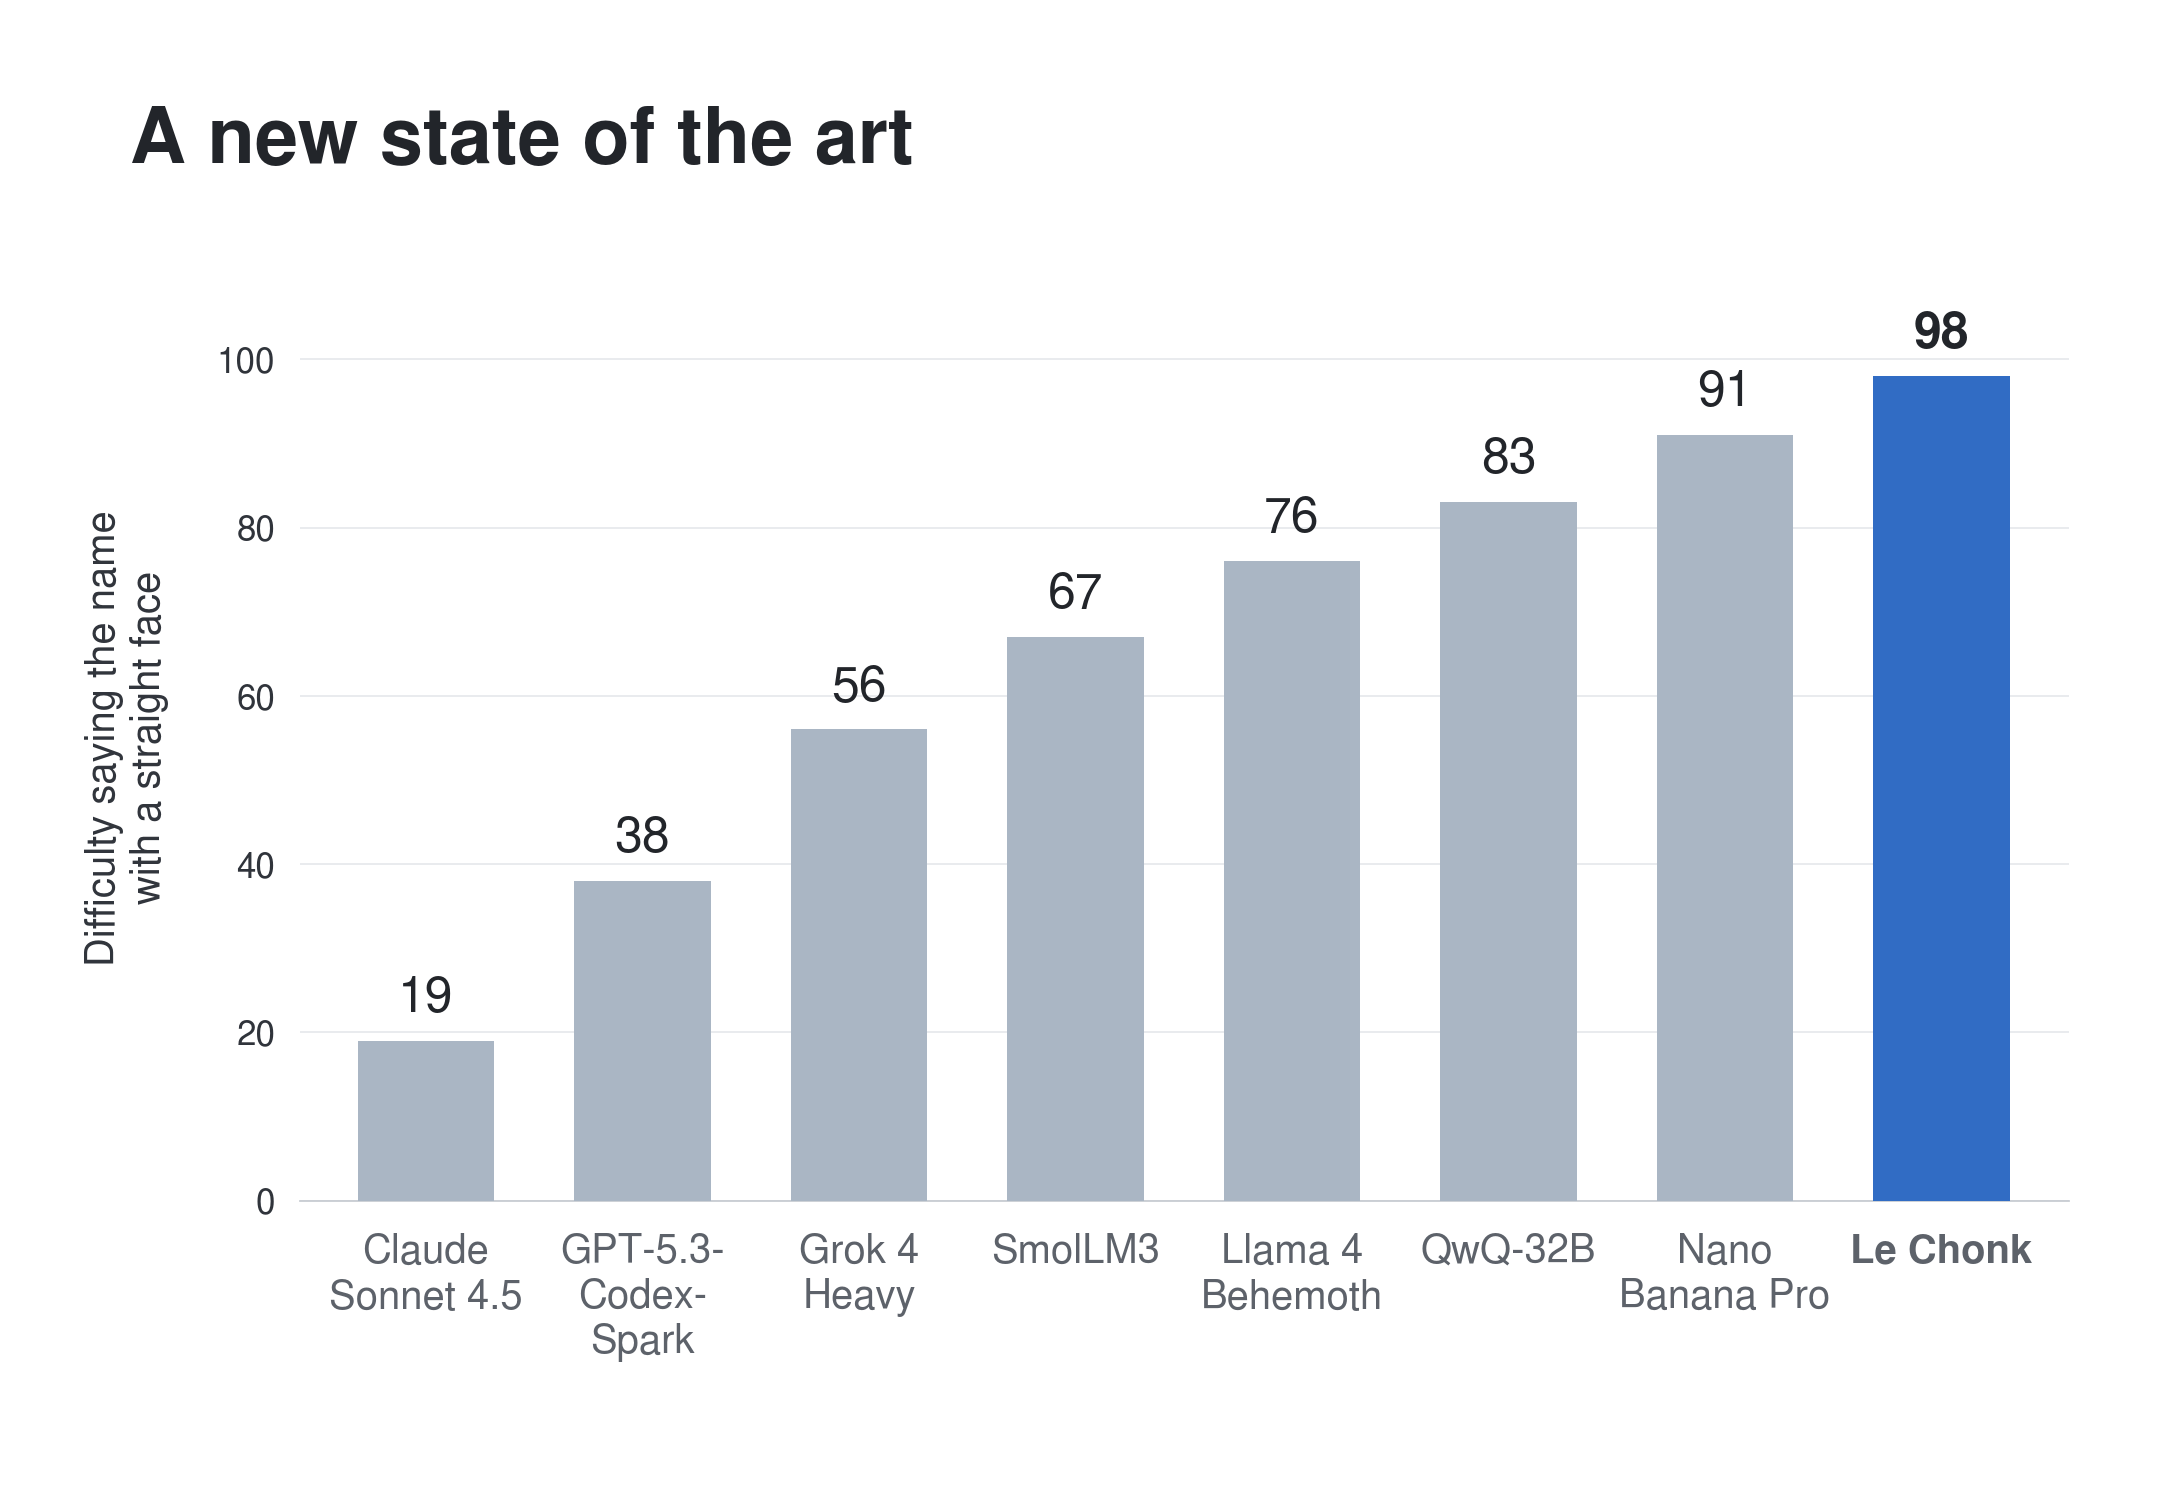
So while Silicon Valley was busy training trillion-parameter models on the entire internet, some absolute legend in Europe apparently taught an AI to say its own name with a 98% difficulty rating. "Le Chonk" has somehow surpassed GPT, Llama, and every other serious AI model at the most important benchmark: being a straight-faced unit. The chart shows various AI models struggling to accomplish what should be trivial—saying their own name—and then there's Le Chonk absolutely dominating the leaderboard like it just discovered consciousness. Claude can barely manage a 19. Meanwhile Le Chonk is out here flexing at 98 like it's running Doom on a pregnancy test. Turns out all those billions in VC funding couldn't compete with whatever cursed dataset Le Chonk was trained on. Innovation at its finest.

GPT Is Responsible

GPT Is Responsible
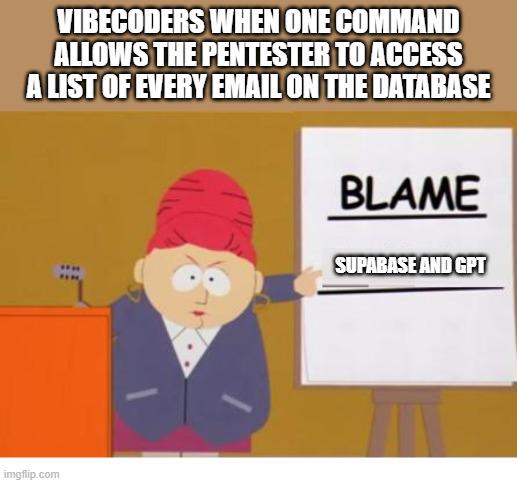
Ah yes, the classic security nightmare: a pentester casually strolling through your entire email database because someone copy-pasted GPT's code without reading past the first line. But sure, blame the AI tools instead of, you know, actually reviewing the code before deploying it to production. The real comedy here is that Supabase and GPT are just sitting there, minding their business, while vibecoders—those magical developers who "feel" their way through coding without understanding what they're doing—create data breaches with the confidence of a thousand suns. It's like blaming your GPS for driving off a cliff when you weren't even looking at the road. Pro tip: If your authentication logic was written by an LLM and you didn't verify it, you're not a developer—you're a liability with a keyboard. Read the code. Understand the code. Or at least Google "how to not expose my entire database" before the pentester does it for you.