Model-performance Memes

Posts tagged with Model-performance

Quick, Someone Release Chatbot 2000!

Quick, Someone Release Chatbot 2000!
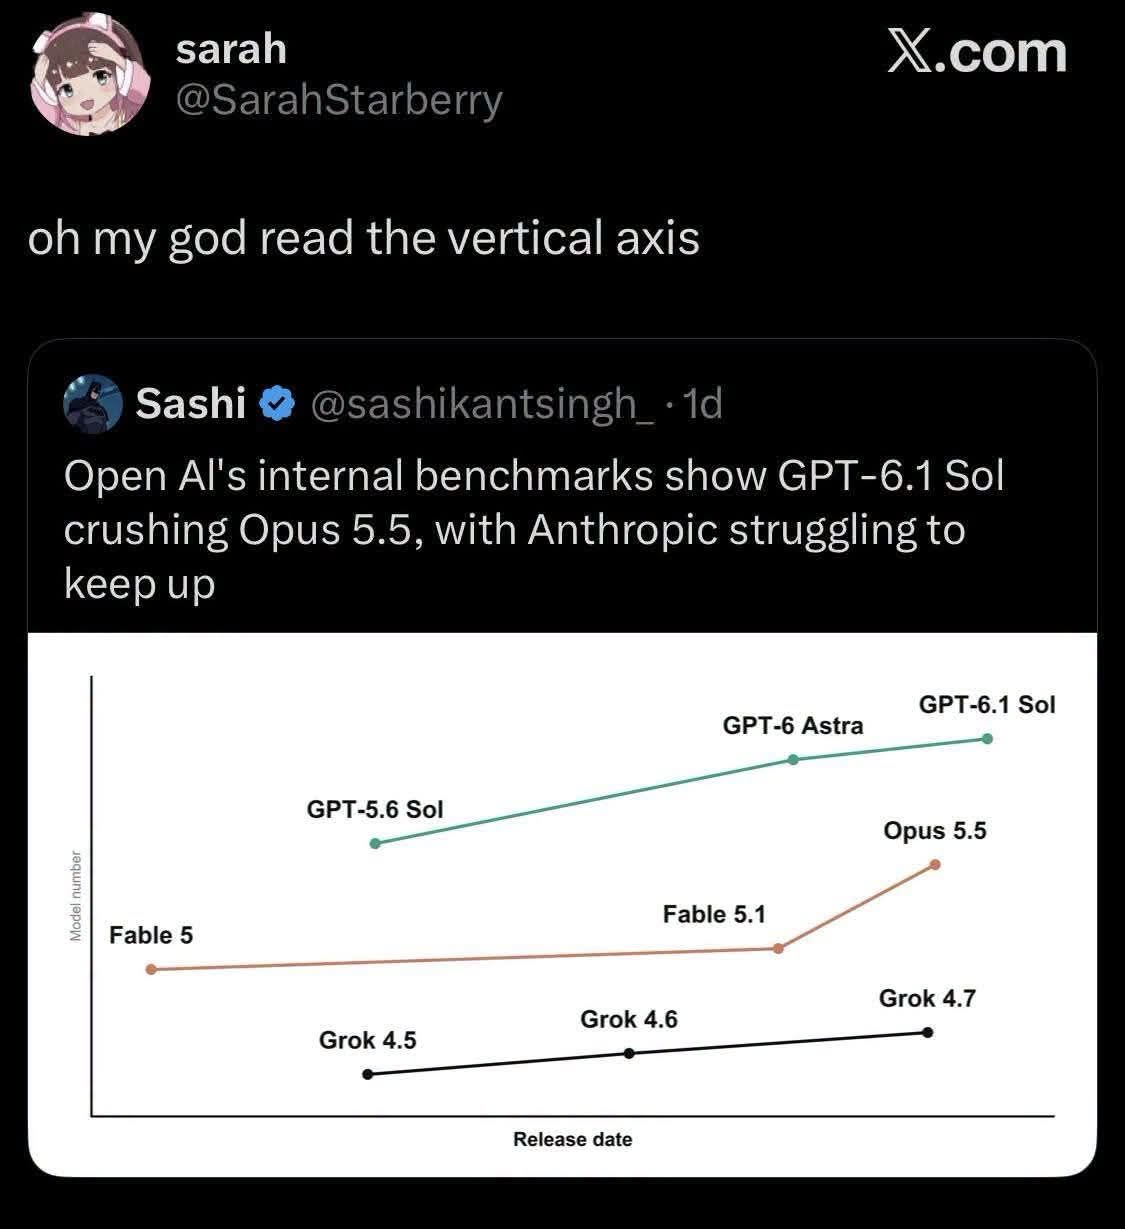
Someone made a chart showing AI model performance over time and forgot that the Y-axis exists. OpenAI's GPT-6.1 Sol is sitting way up top looking impressive, while Anthropic's Opus 5.5 is chilling in the middle, and Grok is barely crawling along the bottom. But here's the kicker: there's no scale on the vertical axis, so for all we know, the difference between them could be 0.2% or 200%. It's like those pharma ads showing a bar chart where one bar is twice as tall as another, but they conveniently forgot to label what the bars actually measure. Could be measuring anything from "times hallucinated about being sentient" to "ability to write Python that actually runs." Classic data visualization malpractice that would get you roasted in any code review, but somehow makes it to Twitter with a verified checkmark.

Claude Fable 5's Latest Benchmarks For Non US Citizens

Claude Fable 5's Latest Benchmarks For Non US Citizens
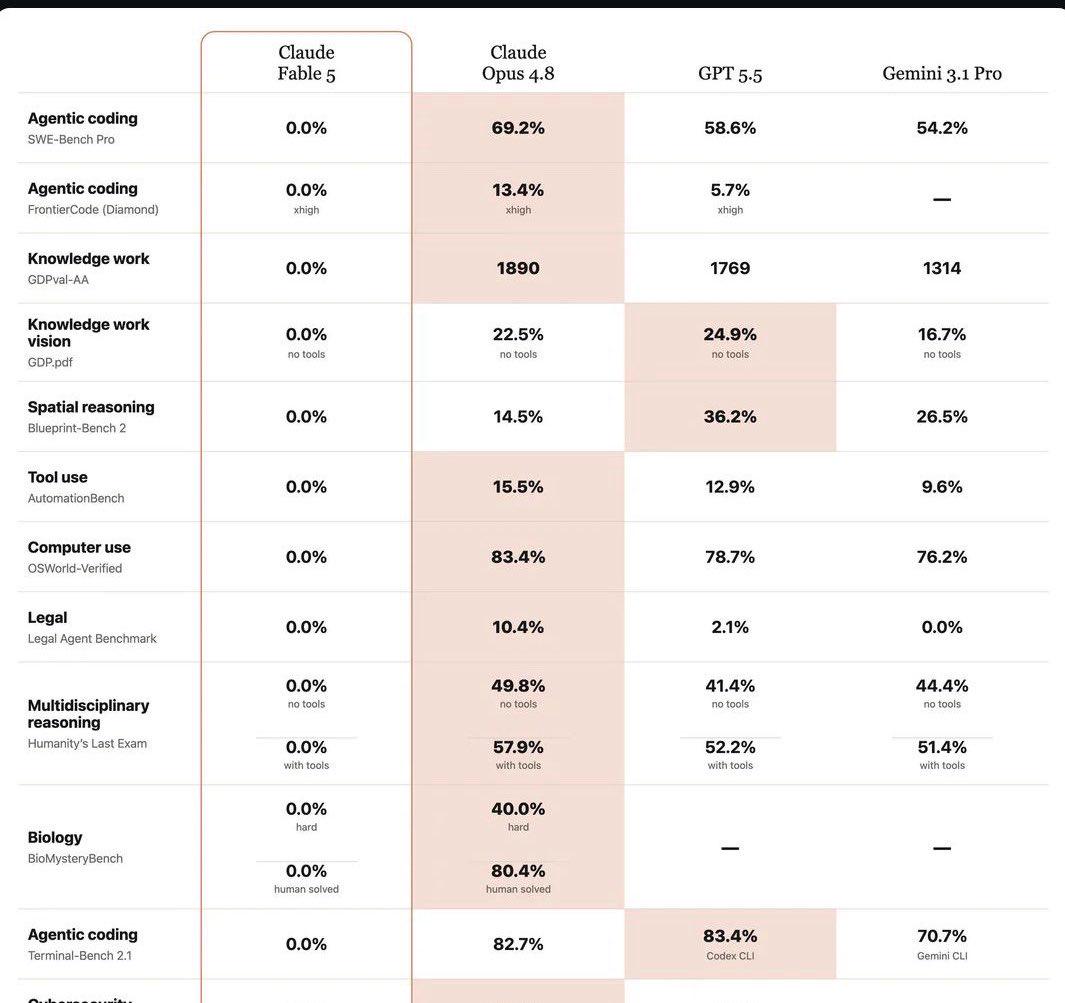
Claude Fable 5 just dropped and apparently decided to take a gap year. Straight zeros across every single benchmark while its siblings are out there crushing code and solving biology problems. The "xhigh" annotation on the 0.0% FrontierCode score is particularly chef's kiss—like marking "extremely good" on a completely blank exam paper. Meanwhile Claude Opus 4.8 is dominating with 83.4% on computer use and 82.7% on terminal benchmarks, but Fable 5 couldn't even boot up. Either this is the most catastrophic model release since Clippy, or someone forgot to flip the "works outside USA" switch in the config. Guess non-US citizens get to experience what it's like to code with a potato. At least it's consistently bad—0.0% takes dedication.