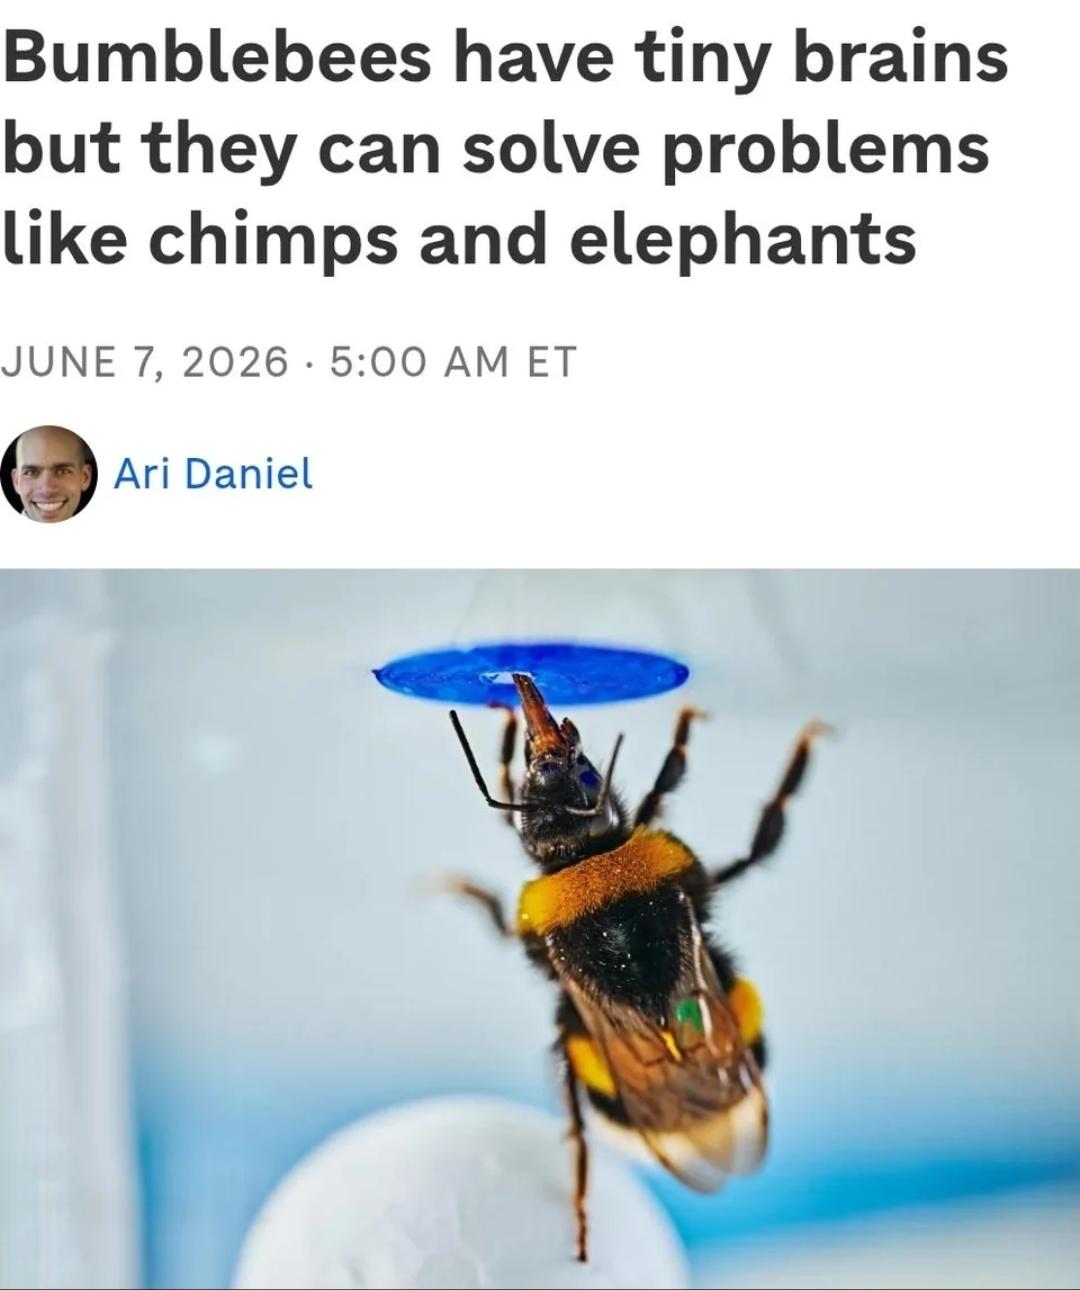
Model distillation is basically taking a massive, compute-hungry neural network (the "teacher" model) and compressing its knowledge into a smaller, more efficient "student" model. You're essentially teaching a tiny model to mimic the behavior of a behemoth without needing all those billions of parameters. The joke here perfectly captures the absurdity: bumblebees have brains the size of a poppy seed (about 1 million neurons), yet they can learn complex tasks, recognize faces, and solve problems that would stump much larger-brained creatures. Meanwhile, your distilled model went from GPT-4's 1.76 trillion parameters down to 7 billion and suddenly can't tell the difference between a cat and a toaster. The bumblebee with its tiny umbrella is literally carrying the weight of this comparison—nature achieved incredible efficiency through millions of years of evolution, while we're out here burning GPUs trying to compress transformers and wondering why the student model keeps hallucinating about elephants solving differential equations.
 AI
 AWS
 Agile
 Algorithms
 Android
 Apple
 Azure
 Backend
 Bash
 C++
 Cloud